To clean web-scraping data, preserve the raw values first, normalize the fields you will use, review duplicate records, and validate contact details before export.
I start with a separate copy of the source file because a cleaner-looking value can lose information. A URL query can identify a product variant, and a leading zero can be part of an account ID. Keep the source URL and original text alongside your cleaned fields.
For a scraped contact list, use this order:
- Import the data and check the suggested column types. Keep identifiers as Text.
- Remove HTML and extra spaces from descriptive text, then standardize only the fields needed for filtering or matching.
- Convert dates and quantities after reviewing their formats.
- Match duplicates on a reliable identifier such as email, then decide which values to retain.
- Check email syntax and domain information, review exceptions, and export the cleaned list.
The tools below let you carry out each step in Datablist without formulas. The examples show which values to inspect before applying a transformation to the full collection.
Here is a quick summary of the clean-up operations found in this article:
- Convert text to Datetime, Number, Boolean
- Convert HTML to text (remove HTML tags)
- Remove extra spaces from texts
- Normalize your data
- Remove symbols from texts
- Split full name into First Name and Last Name
- Deduplicate items
- Validate Email Addresses
- Extract person or business names from scraped texts
Import from CSV or copy-paste data
Datablist is a perfect tool for cleaning data. It's an online CSV editor with cleaning, bulk editing, and enrichment features. And it scales up to millions of items per collection.
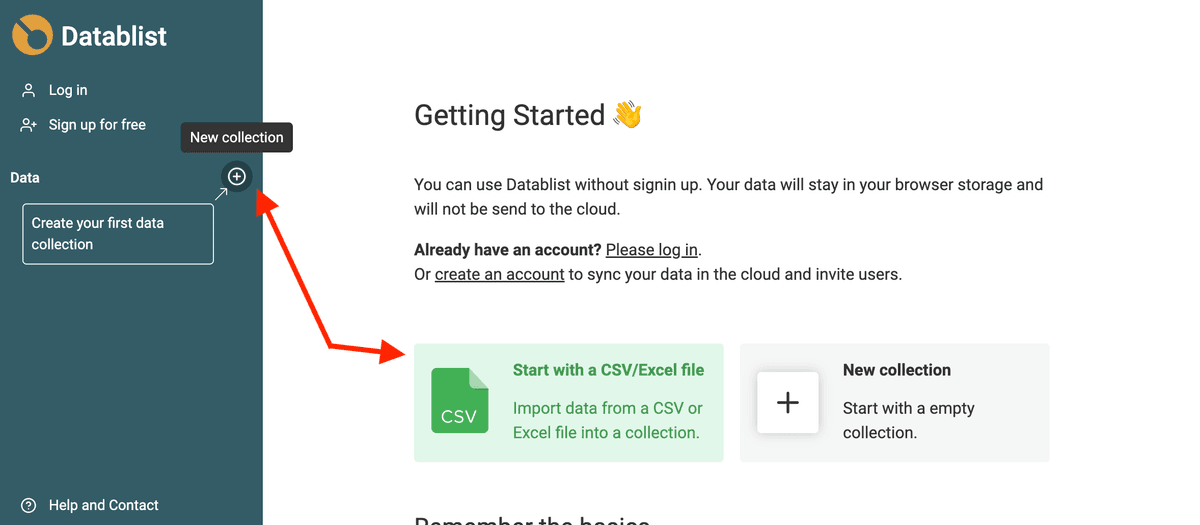
Open Datablist, create a collection and load your CSV file with your scraped data.
To create a new collection, click on the + button in the sidebar. And click "Import CSV/Excel" to load your file. Or click the shortcut from the getting started page to move directly to the file import step.
Auto detect format
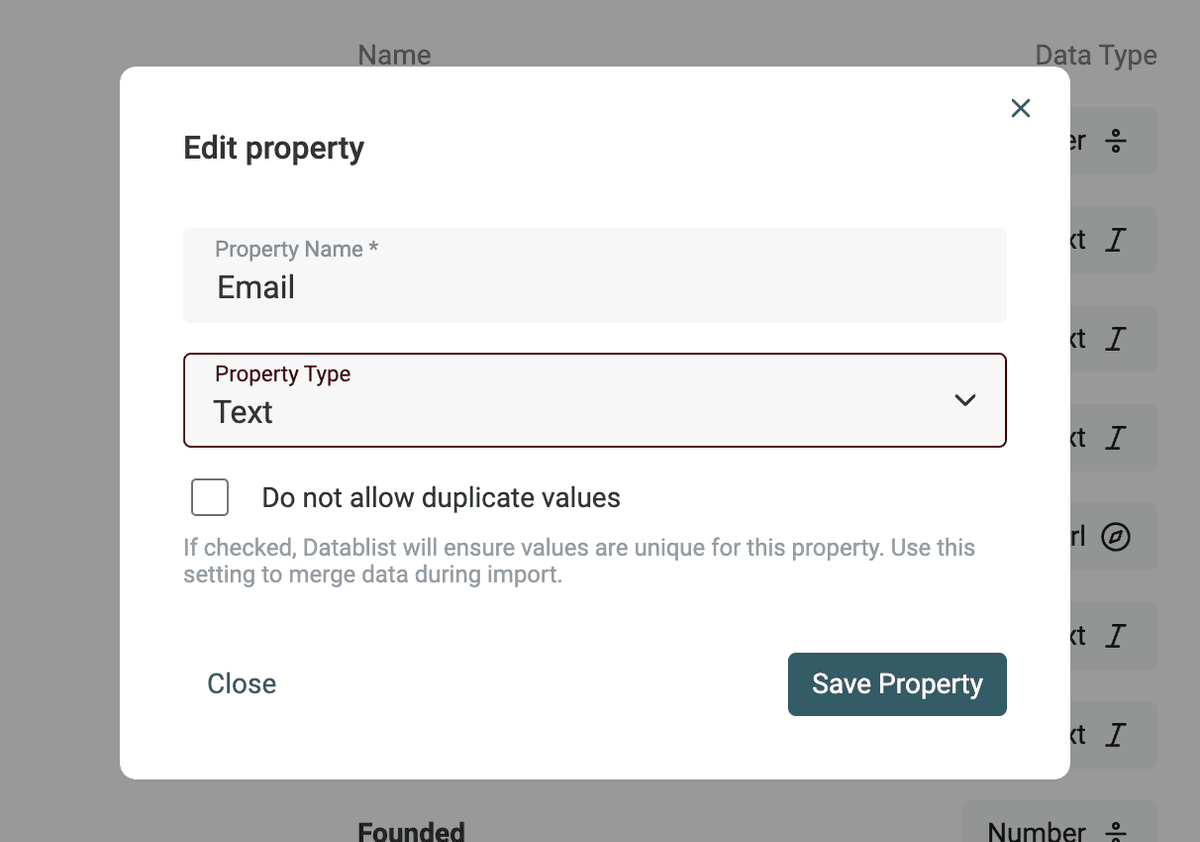
Datablist import assistant detects automatically email addresses, Datetimes in ISO 8601, Booleans, Numbers, URLs, etc. when they are well formated.
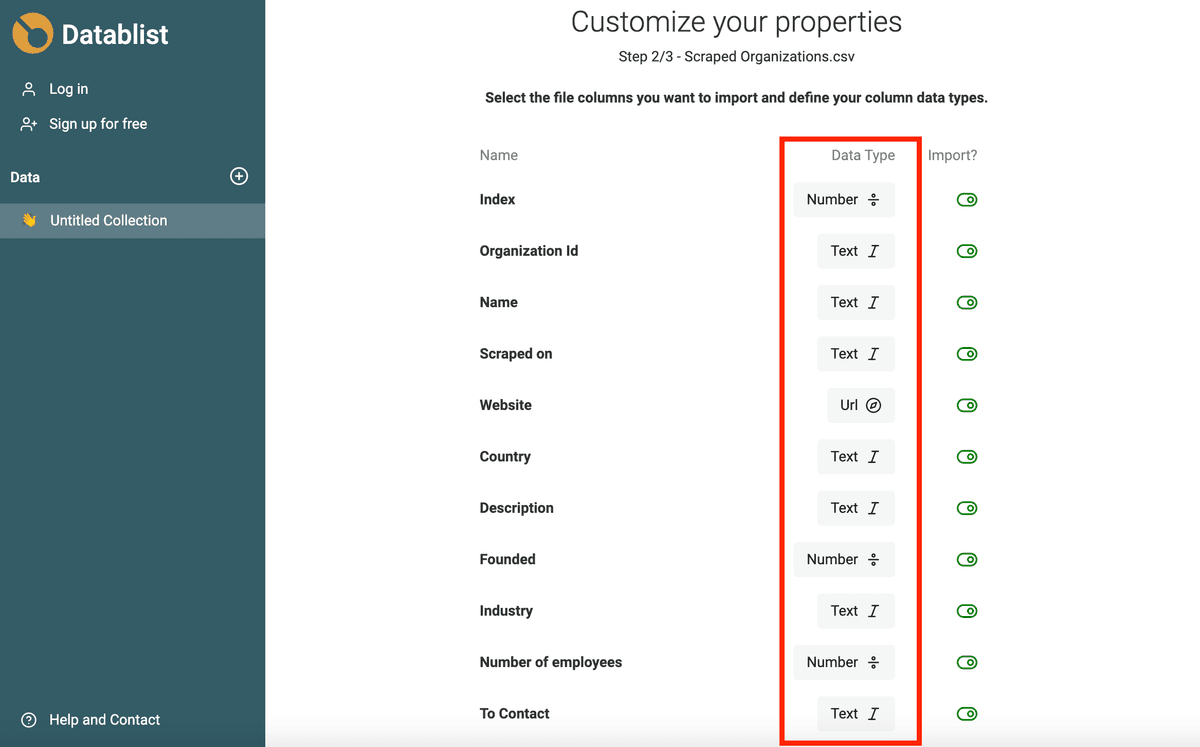
If your data required more complex analysis (different datetime format, typos in URL or email address), import them as Text property. I'll show you in the next section how to convert your text properties to Datetime, Boolean, or Number.
Convert text to datetime, boolean, number
Marie Kondo says "Life truly begins after you have put your house in order". Same with your scraped data: "Sales truly begins after you have put your data in order"! 😅
Filtering on a date (creation date, funding date, etc.), a number (price, number of employees), or a boolean is so much easier when they are native objects and not just text.
Open the "Text to Datetime, Number, Checkbox" tool from the "Clean" menu.
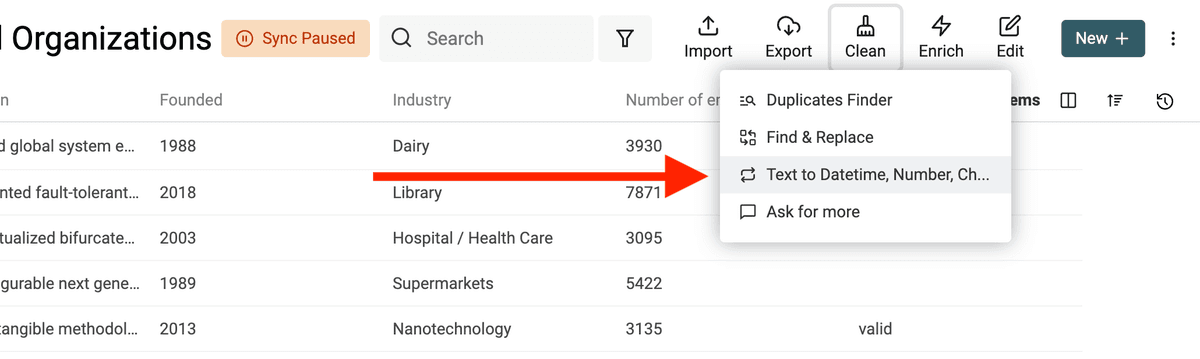
Convert any text to Datetime format
Datetime has an international format called ISO 8601 with a defined structure. If your data uses the ISO 8601 format, a Datetime property will be created automatically during import to store the data.
For Date and Datetime values in other formats, you have to specify the format used so Datablist can convert it to structured Datetime values.
Select the property to convert and select "Convert to Datetime".
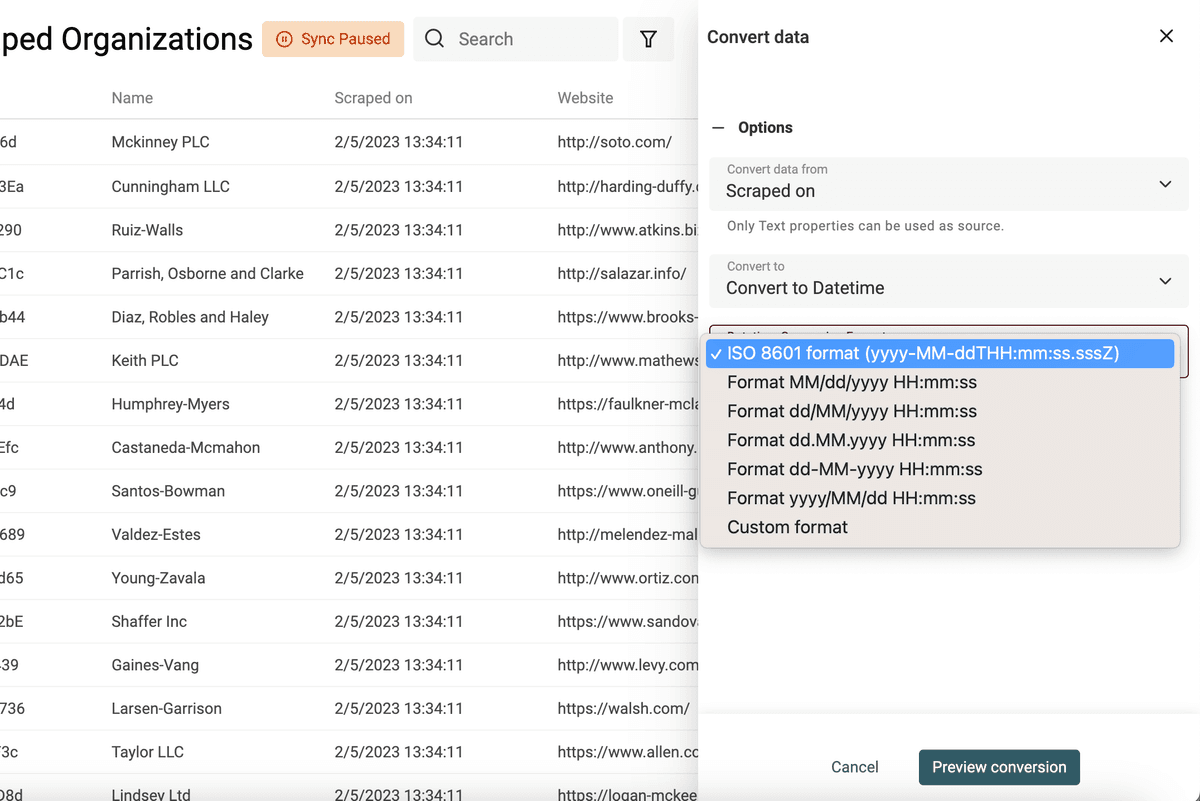
Common formats are listed (datetime formats used by Google Sheets and Excel) or select "Custom format" to define your datetime format.
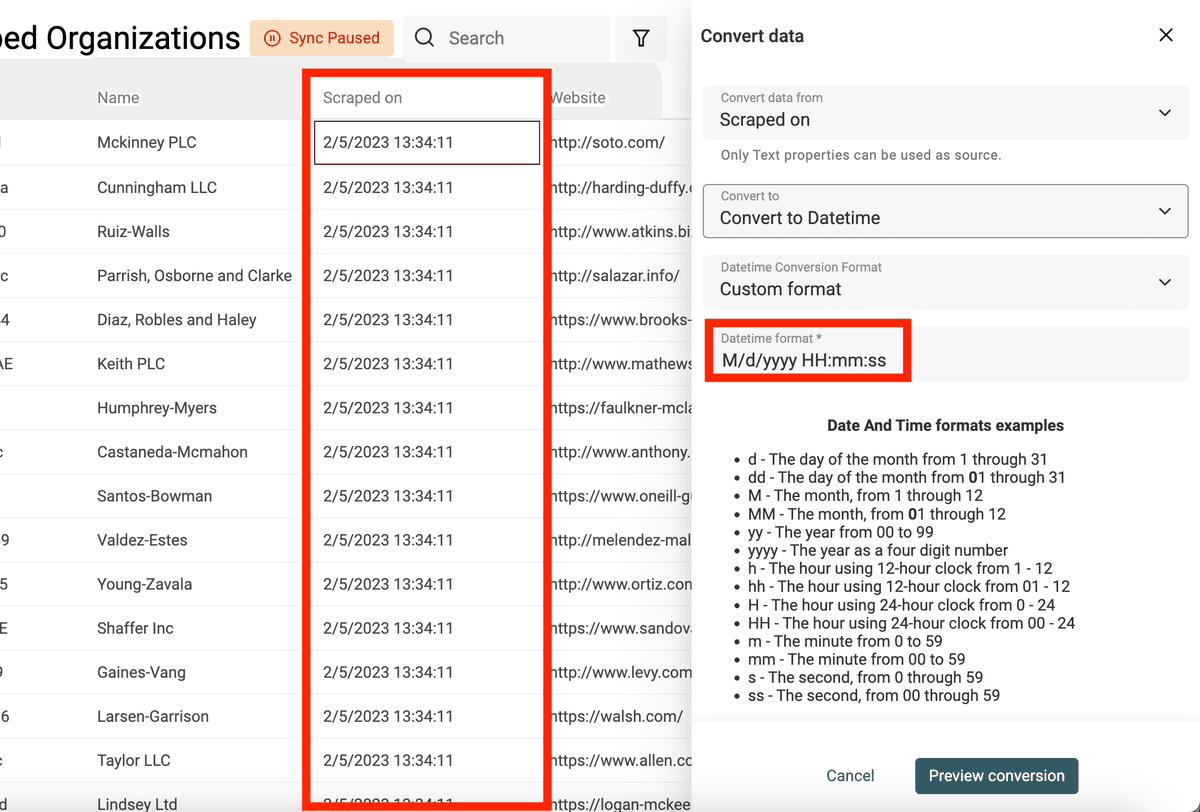
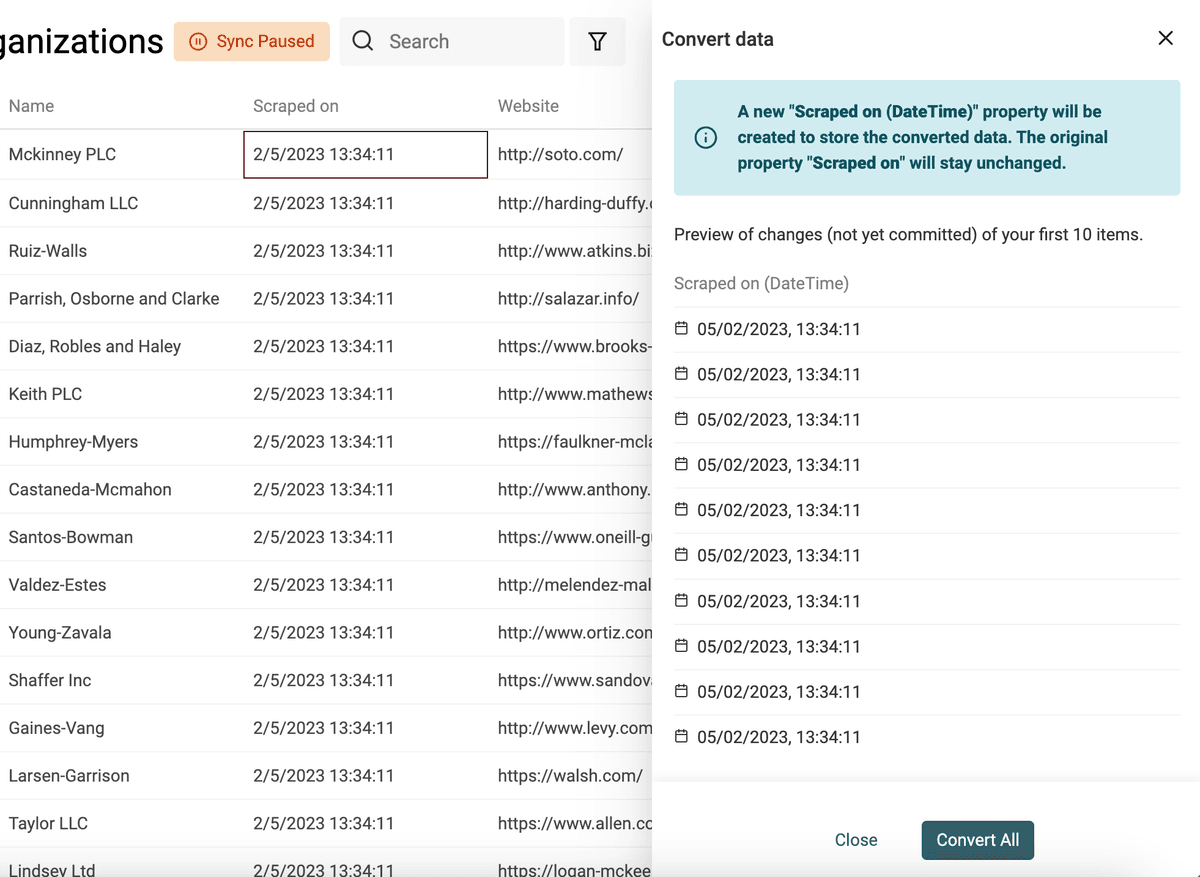
👉 Visit our documentation to learn more on custom datetime formats.
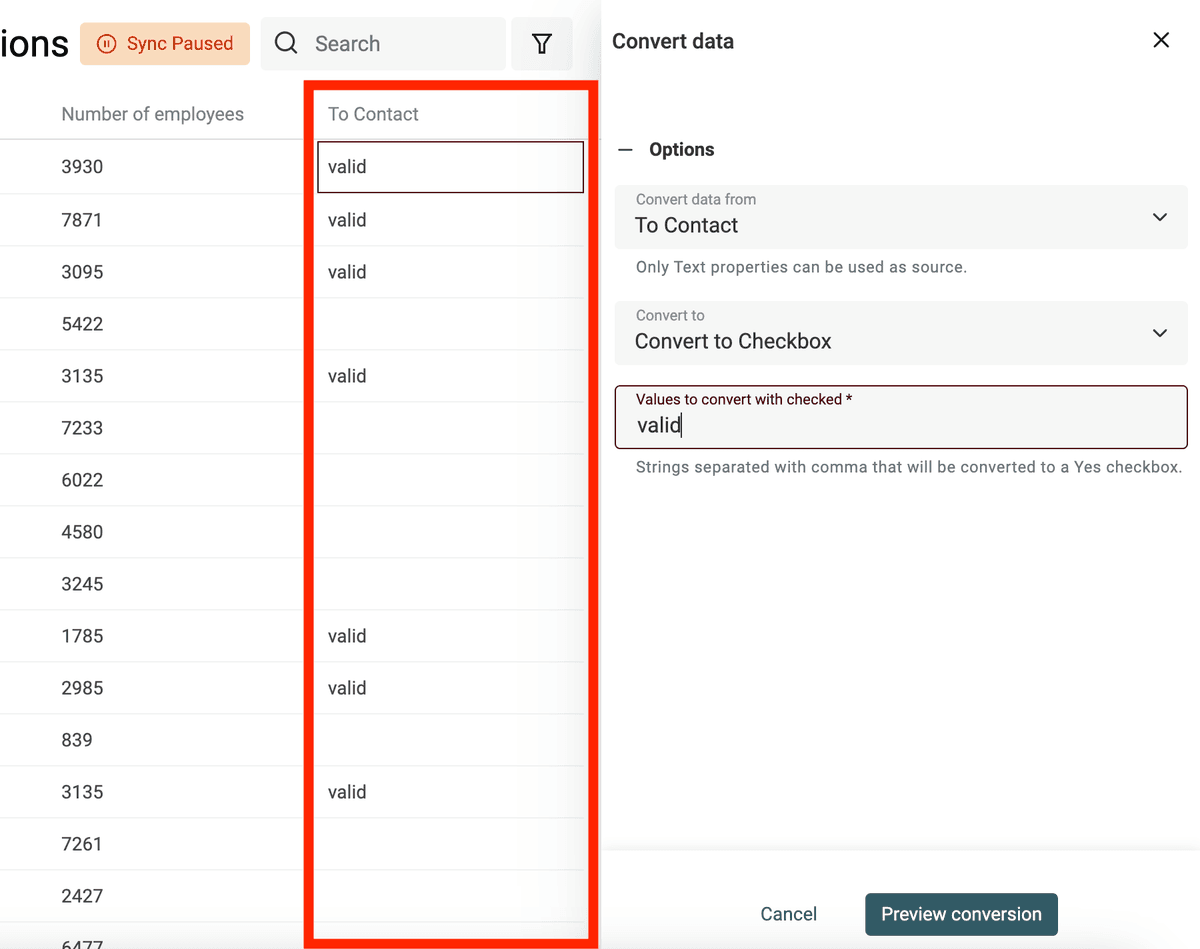
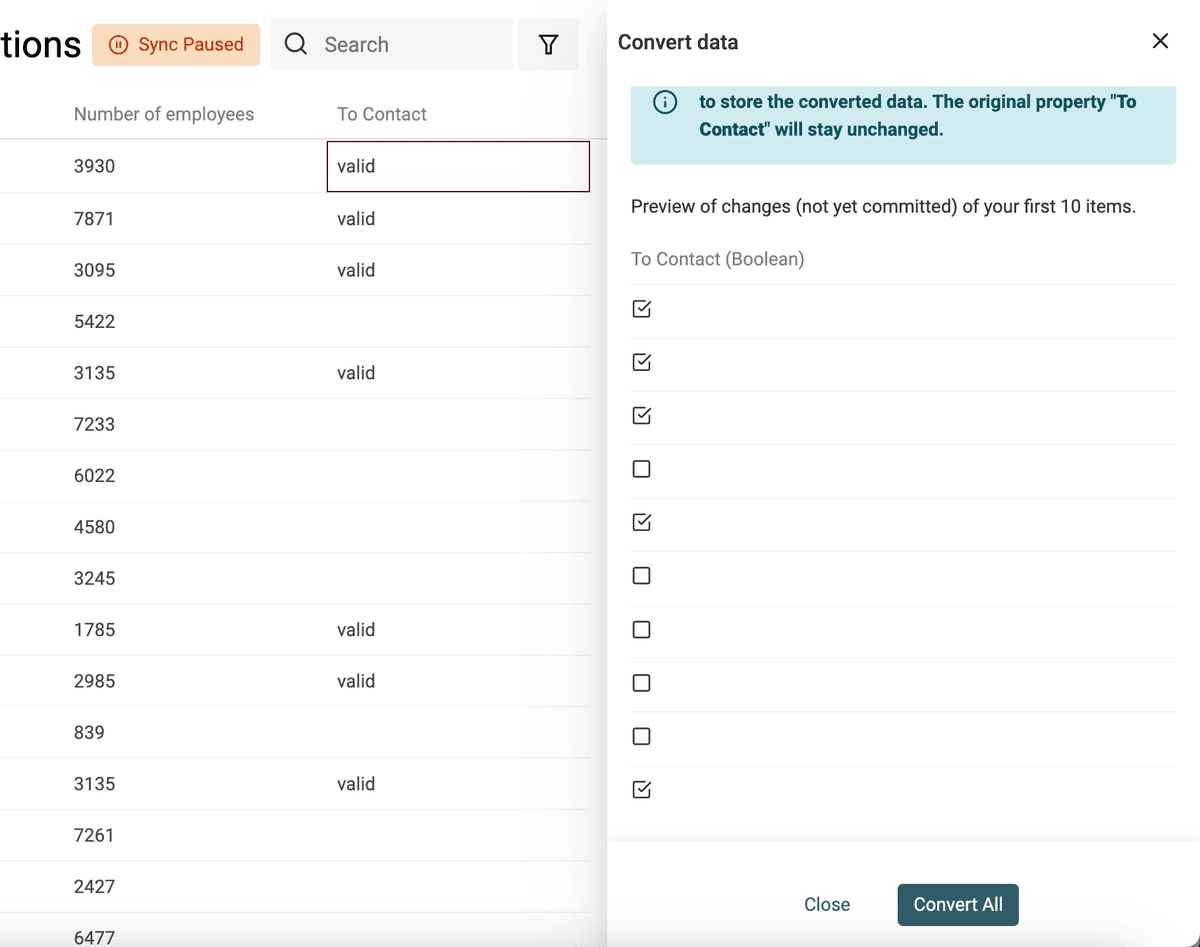
Create Checkboxes (Boolean) from text values
Datablist converts automatically columns with "Yes, No", "TRUE, FALSE", etc. to Checkbox properties on import. Use the converter for more complex conversions.
Define the values (separated with commas) that will be converted to a checked checkbox. Other values will be kept unchecked.
Extract number values from texts
Use the "Text to number" converter to:
- Normalize numbers with custom decimal and thousand separators
- Extract numbers from texts with letters
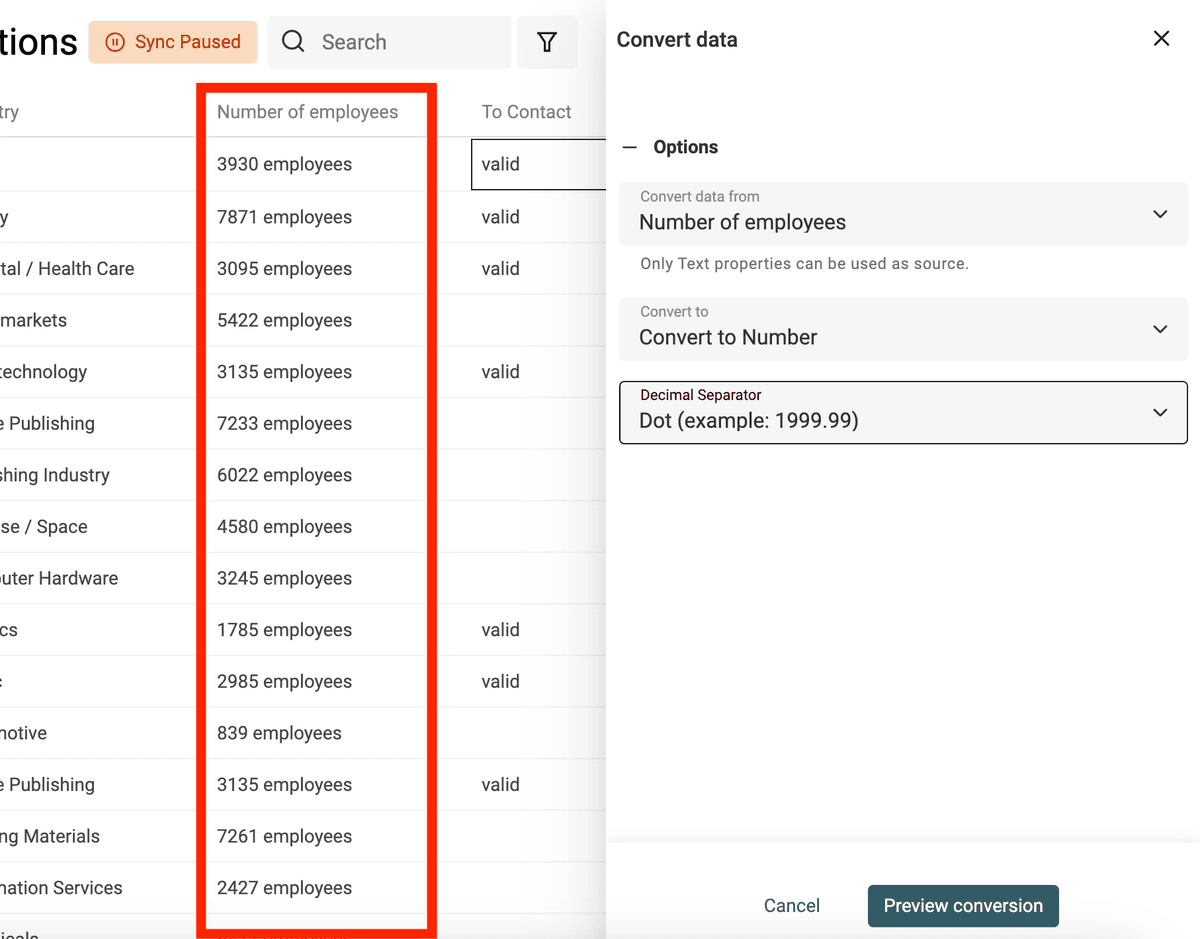
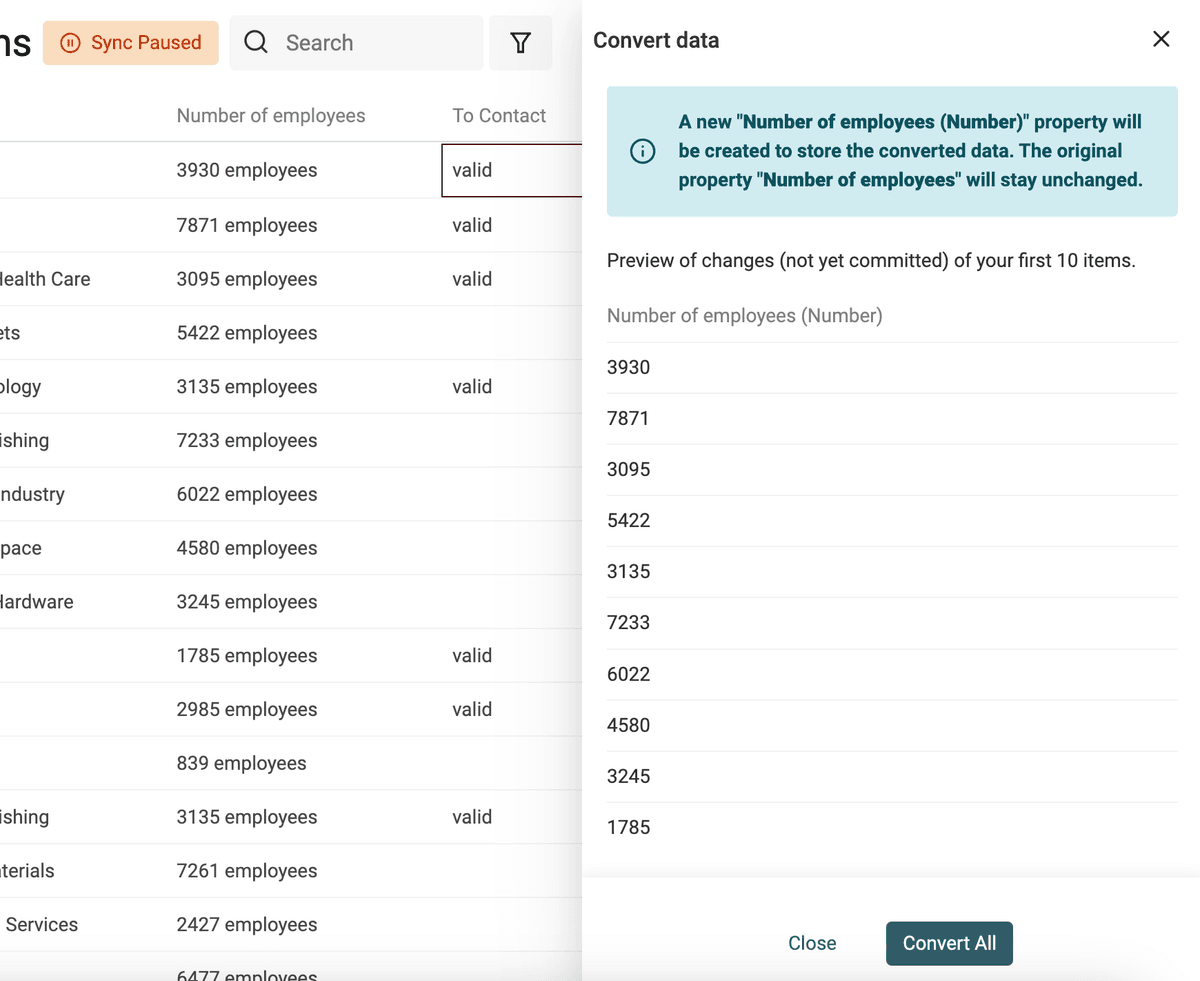
👉 Visit our documentation to learn more on number conversion.
Clean data
Convert HTML to text
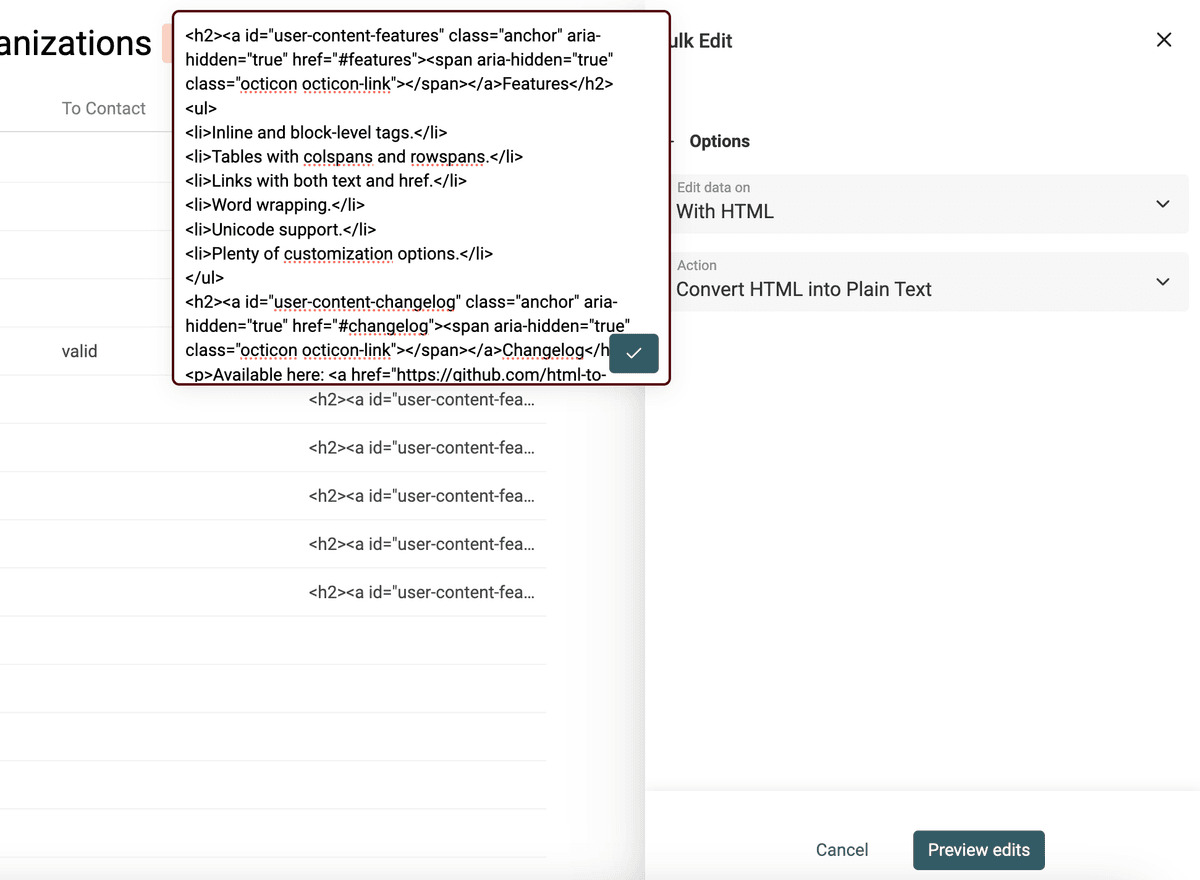
Scraping tools parse HTML code and you may get HTML tags in your texts.
HTML codes have links, images, and lists with bullet points. And are written with paragraphs and multi-lines.
The goal is to keep some of the order HTML brings but transform a non-readable code into plaintext.
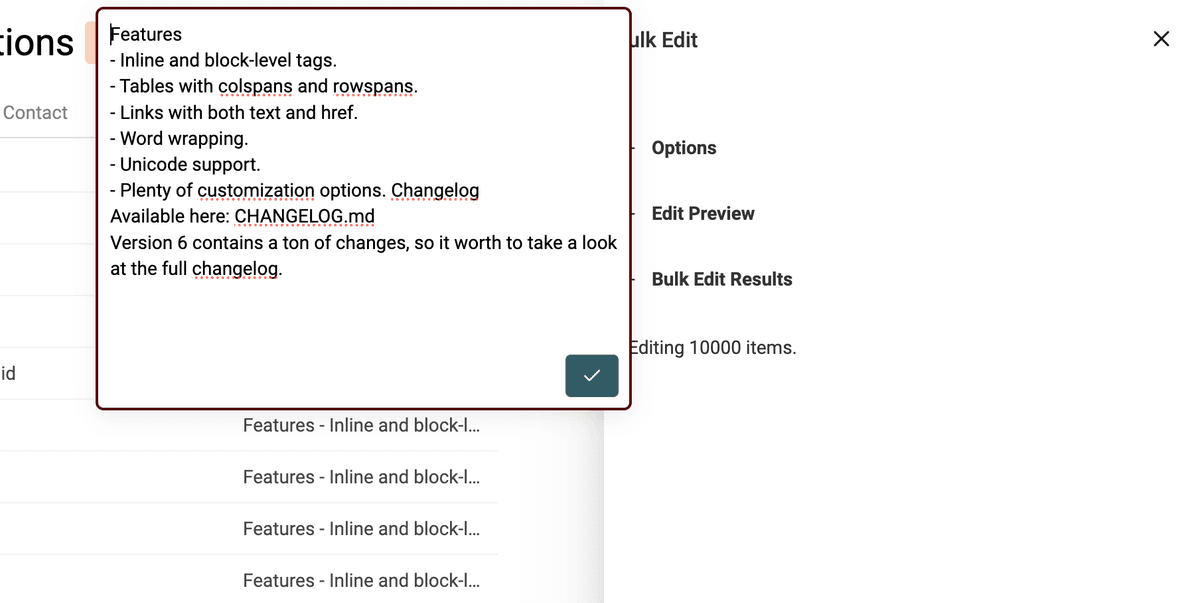
Datablist HTML to Text converter keeps newlines, and transforms bullet points into list prefixed with -.
To transform your text with HTML tags into plaintext, open the Bulk Edit tool in the Edit menu.
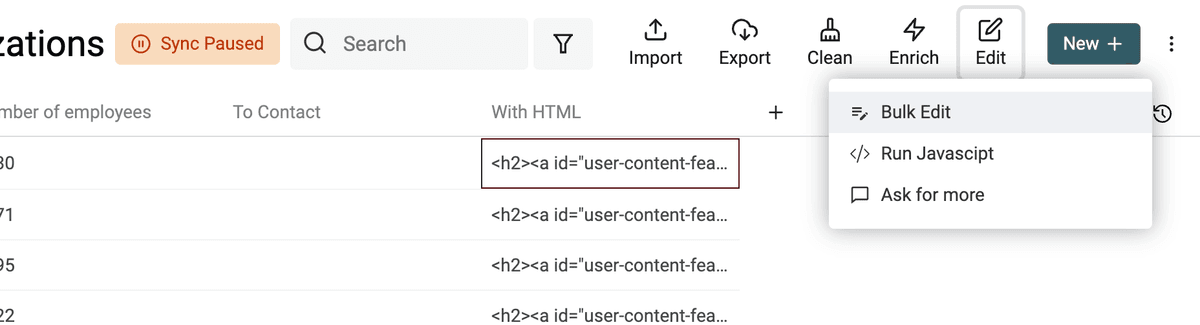
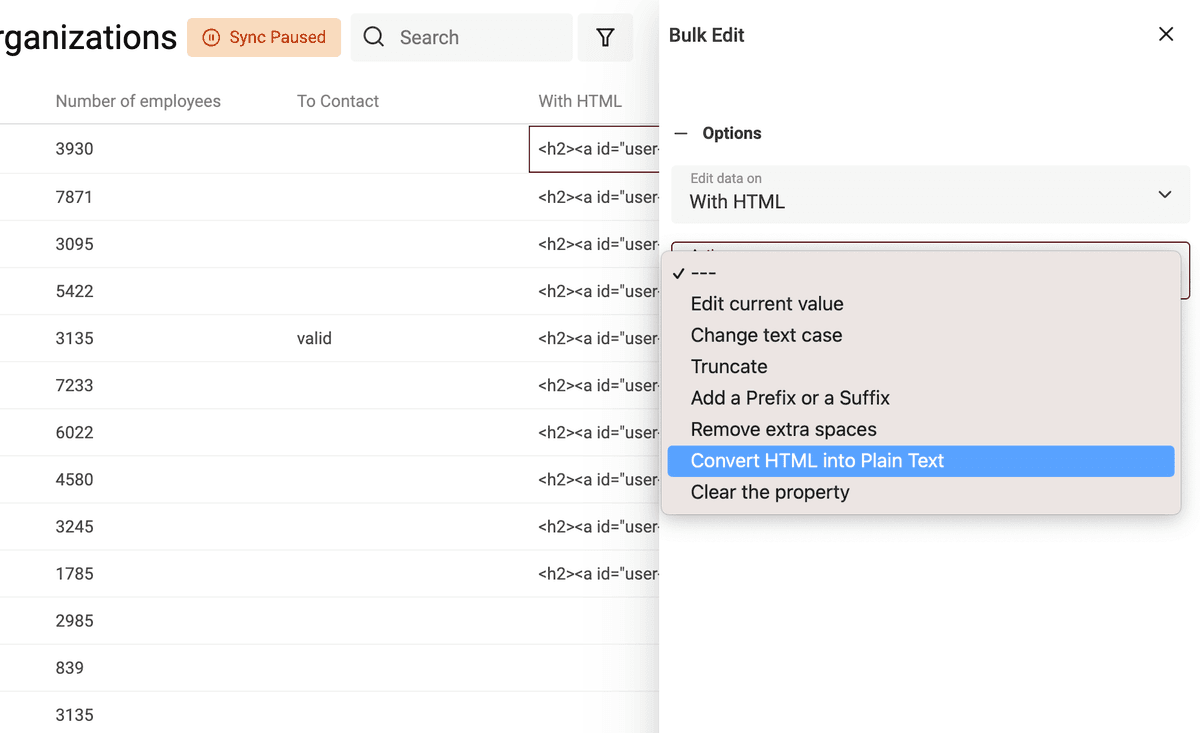
Select your property with HTML tags. And select "Convert HTML into plain text".
Remove extra spaces
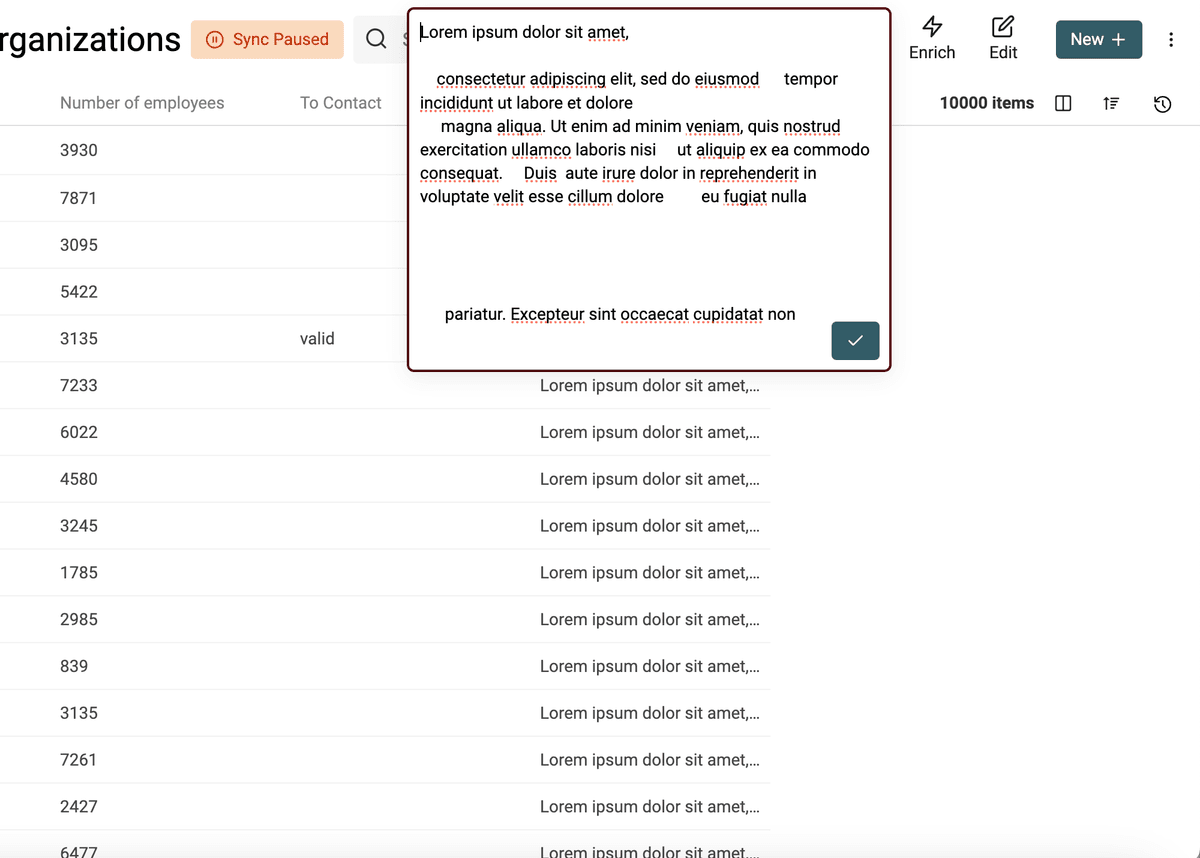
Another common issue with scraped data is extra spaces. Spaces come from new lines, from Tab, and other characters that represent a space in HTML.
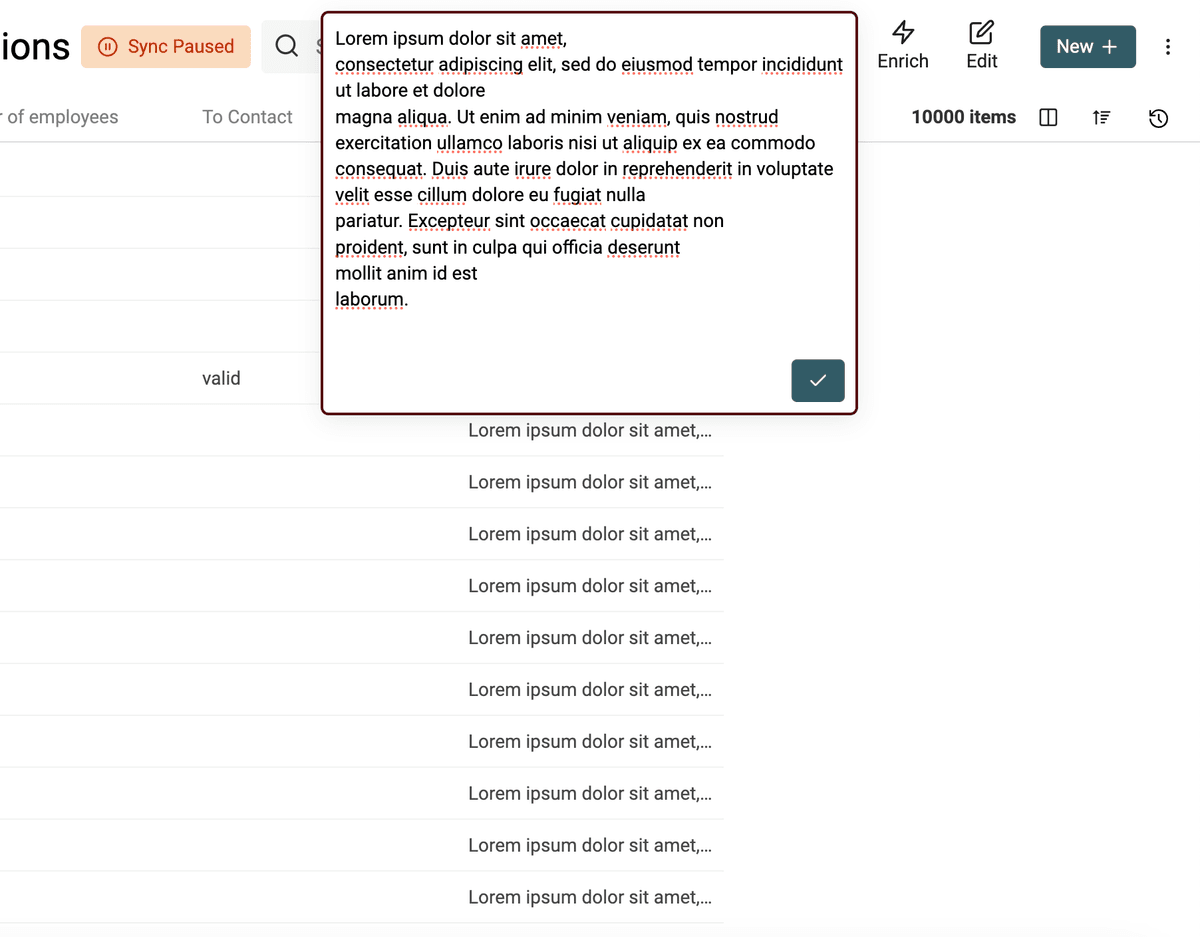
Datablist comes with a cleaning tool to get rid of extra spaces.
- It removes extra spaces between words
- It removes empty lines
- It removes leading and trailing spaces on each line
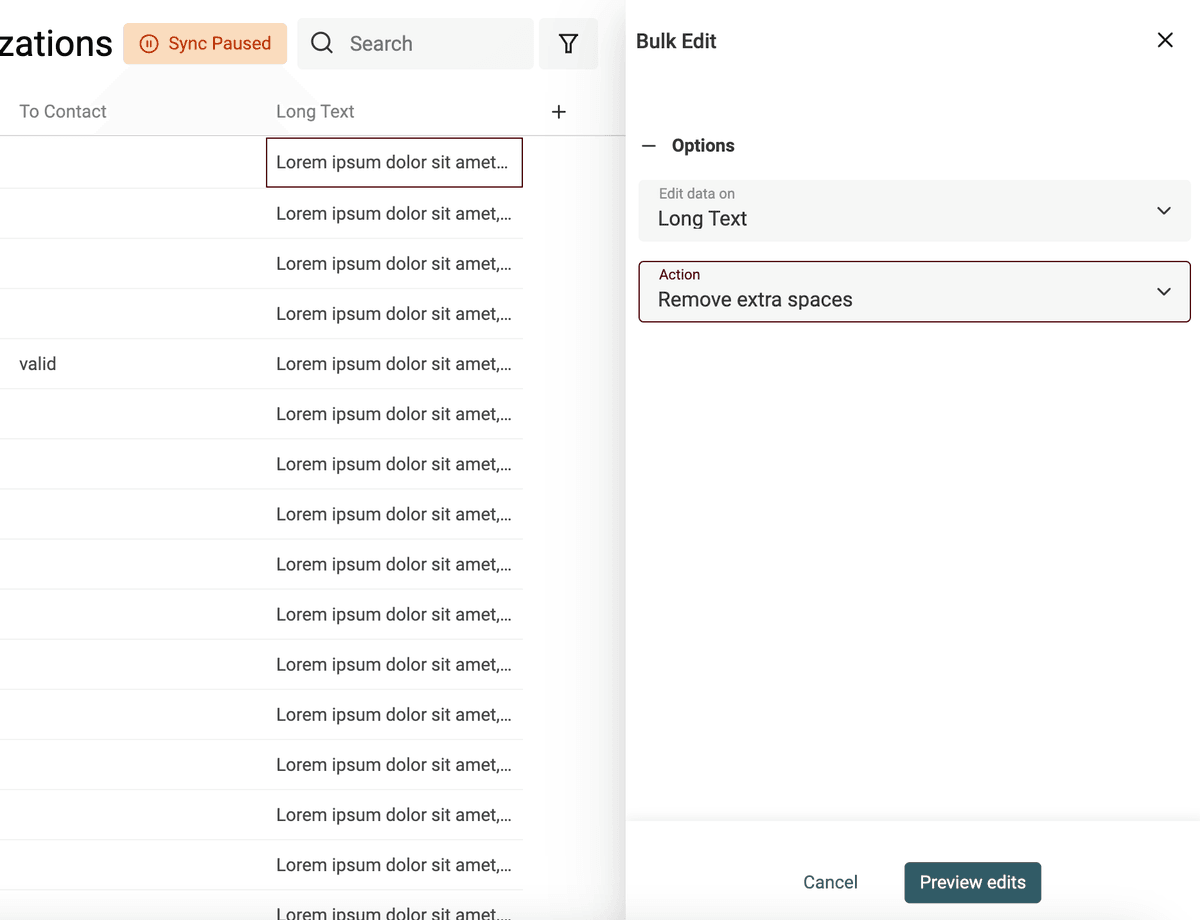
To remove extra spaces, go on the "Bulk Edit" tool from the "Edit" menu. Select your property and the "Remove extra spaces" action.
Clean text case
Changing the case of your text is simple. Open the "Bulk Edit" tool in the "Edit" menu.
Select the property to process and use the "Change text case" action.
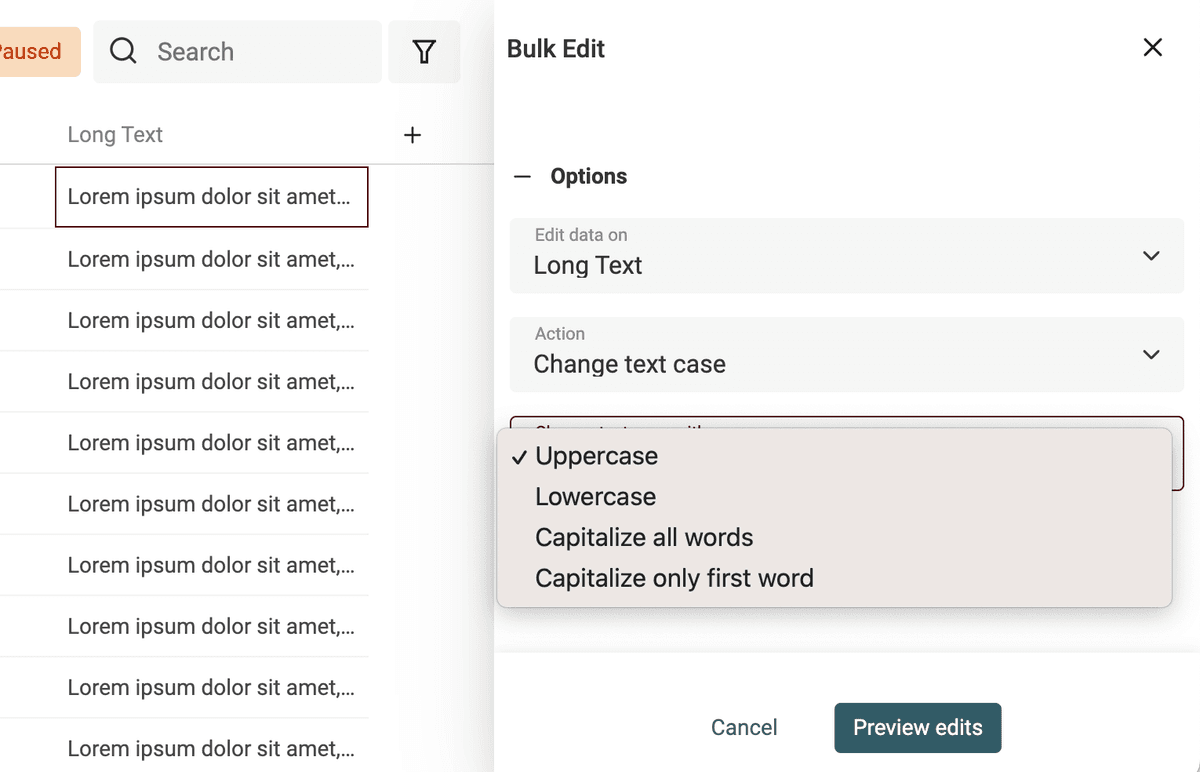
4 modes are available:
- Uppercase - All letters will be converted to their uppercase version. Ex:
john=>JOHN - Lowercase - All letters will be converted to their lowercase version. Ex:
API=>api - Capitalize - The first letter of all words will be capitalized. Ex:
john is a good man=>John Is A Good Man - Capitalize only the first word - Only the first letter of the first word will be capitalized. Ex:
john is a good man=>John is a good man
Remove symbols from texts
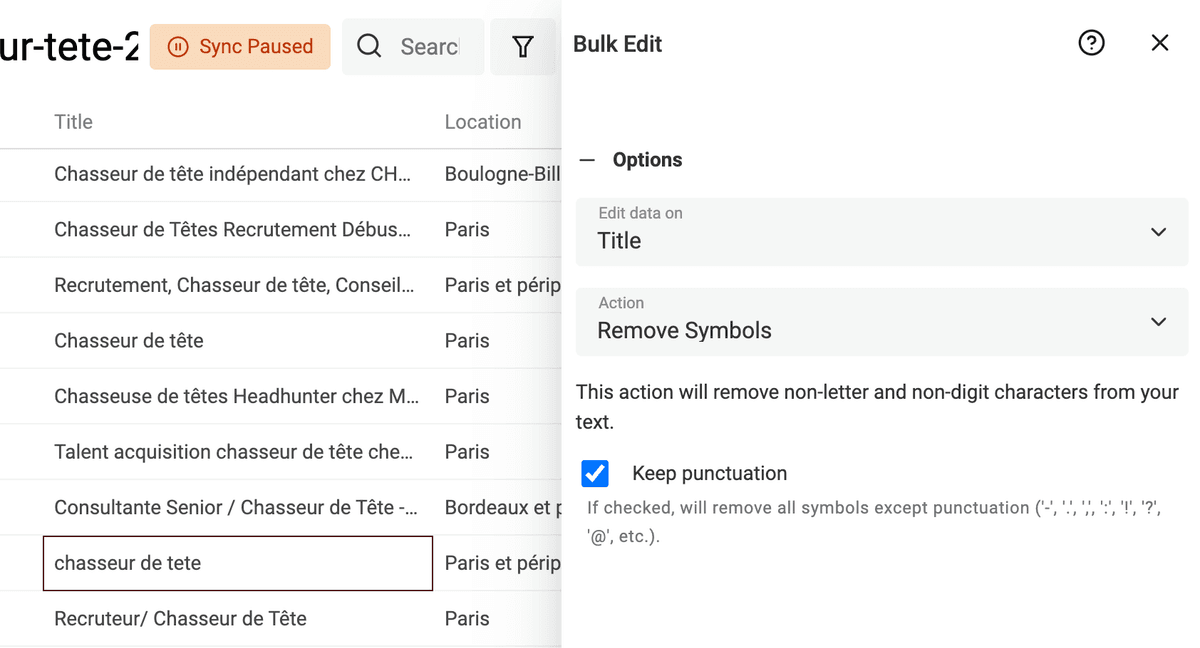
Texts scrapped from HTML pages, or with user inputs (for example LinkedIn profile titles) can contain text symbols: smiley, and other characters that will impact the processing of your data. A simple smiley at the end of a name can prevent it from being spotted by a deduplication algorithm.
Datablist has a built-in processor to remove any non-text symbols from your data.
Click on "Bulk Edit" from the "Edit" menu, select a text property and, pick the "Remove symbols" transformation.
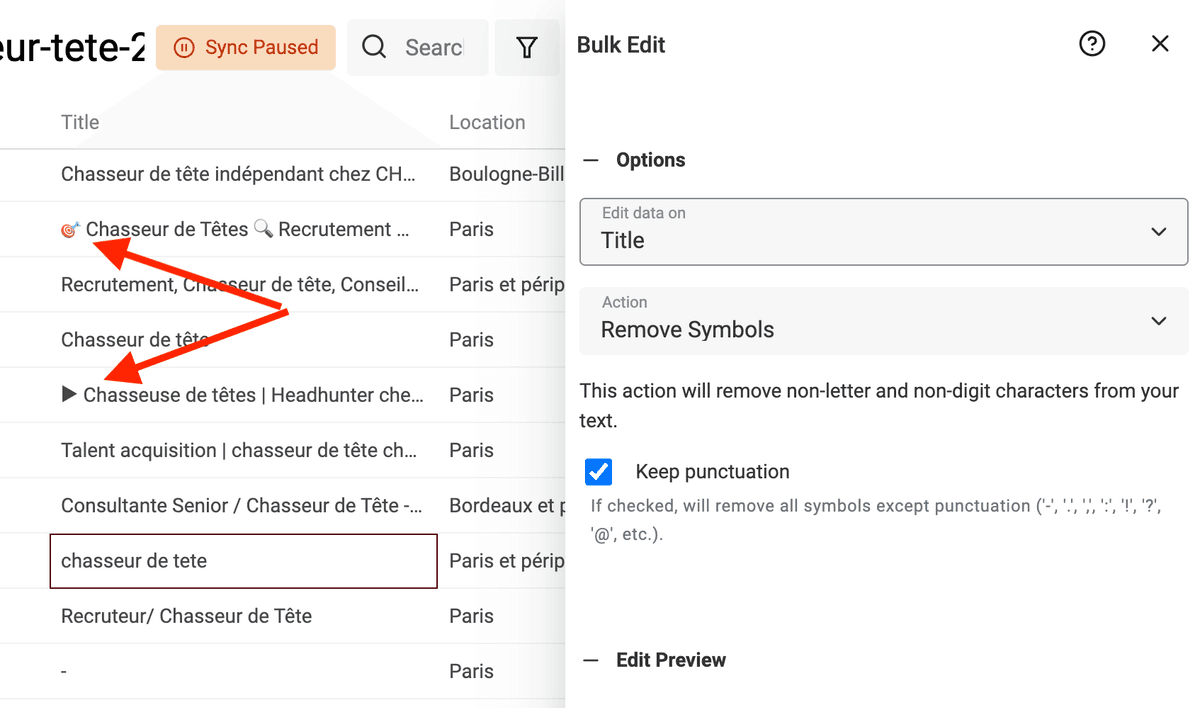
If the preview is good, run the transformation to process your items.
Normalization with Find and Replace
To build segments on your prospect lists, you must normalize your data.
- Normalize job titles
- Normalize countries, cities
- Normalize URL
- Etc.
Your goal is to reduce a property with free text into a property with limited choices. Or to transform your texts into a more basic version (URL with paths into a simple URL domain).
Datablist comes with a powerful Find and Replace tool. It works with simple text and with regular expressions.
Regular Expressions are both complex and very powerful.
Here are some examples of how to use RegEx to clean your data.
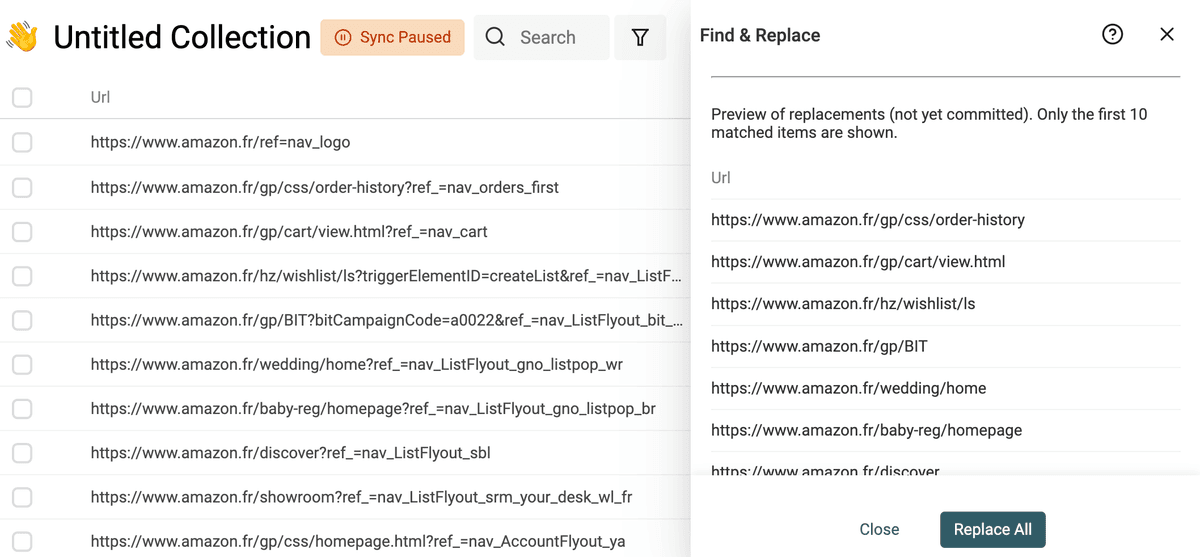
Remove query params from an URL
Some URL parameters track a campaign; others select a product, variant, search result, or page number. Removing all of them can collapse different records into one URL.
Duplicate your source URL property first. Use the expression below only when you have confirmed that every query parameter in that column can be discarded. For example, it removes ?utm_source=newsletter from a page URL, but it would also remove ?variant=blue from a product URL. If you need the variant, retain the query or remove only the specific tracking parameters with a separate transformation.
To remove the entire query, check Match using regular expression and use this expression with an empty replacement:
\?.*$
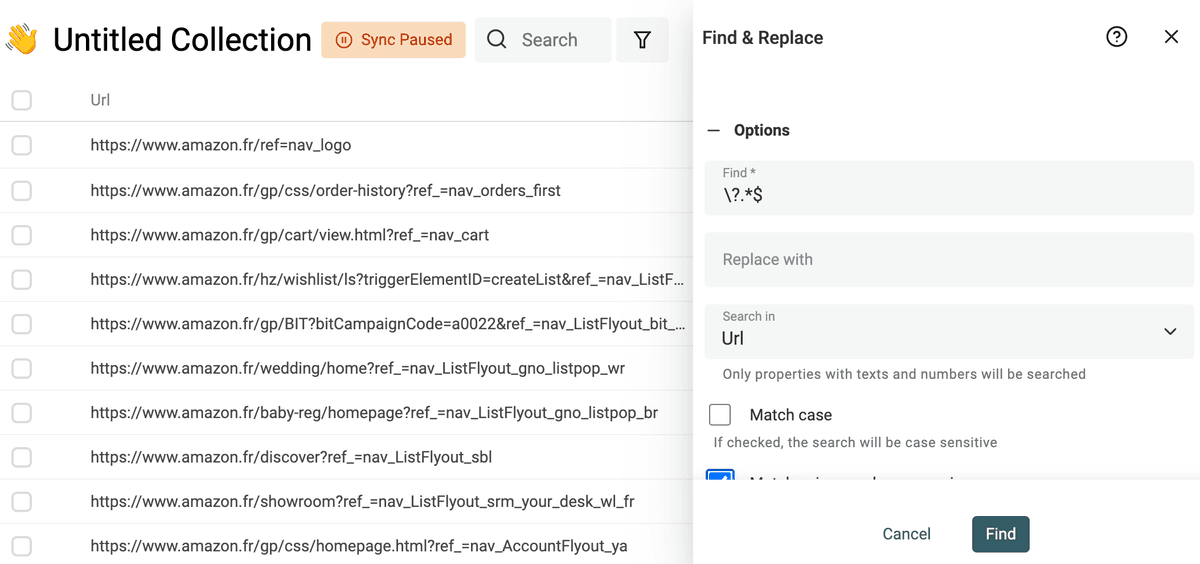
Review URLs with and without query strings in the preview, then apply it to the copied URL property only if they still identify the intended pages.
Get domain from email addresses
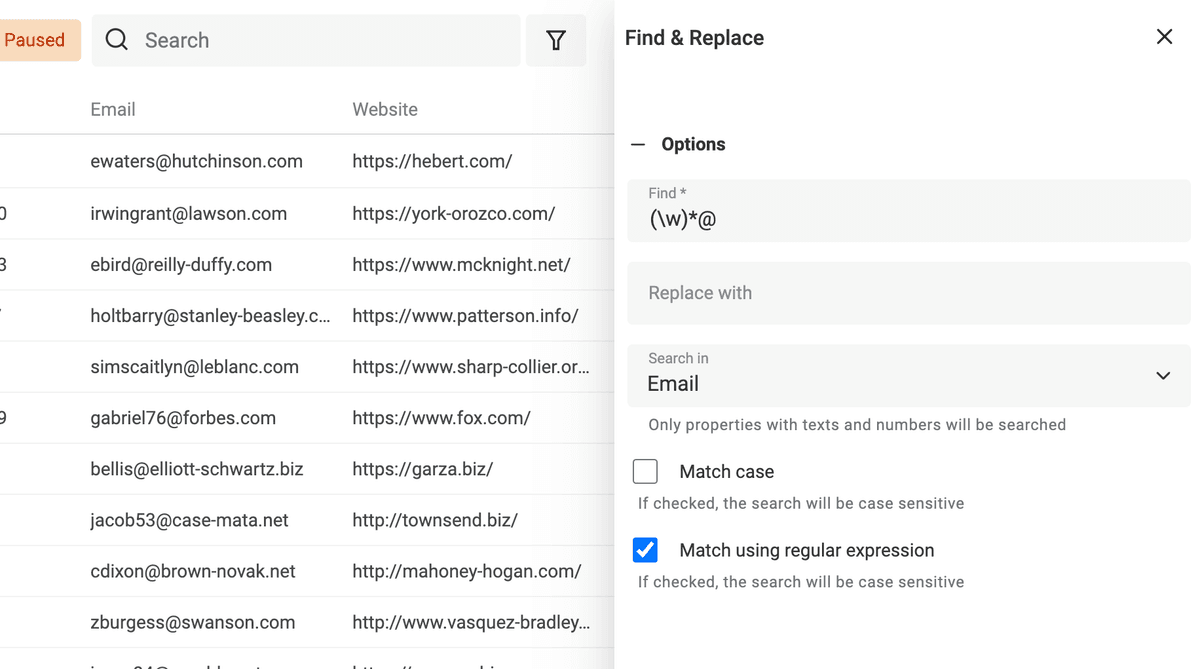
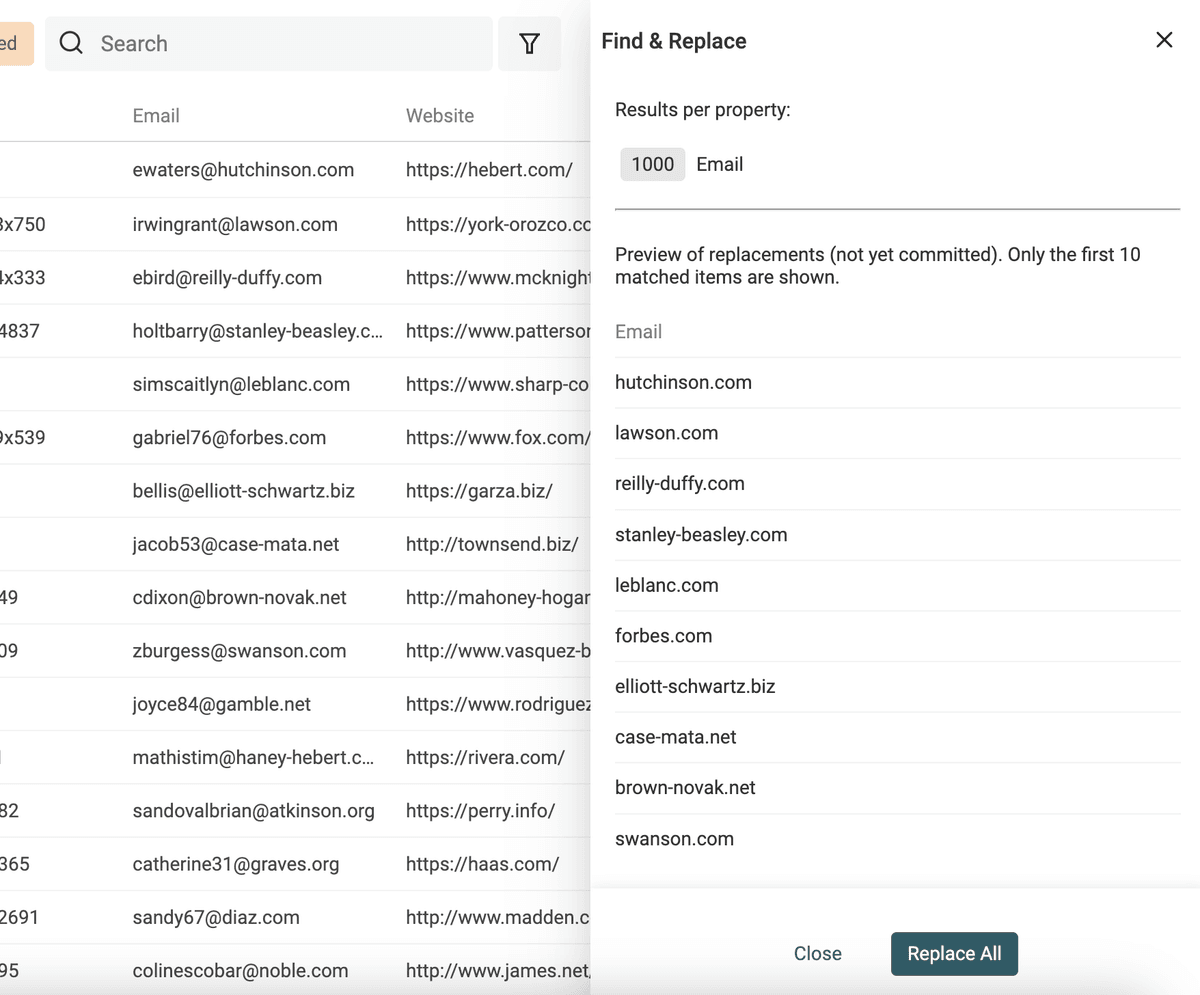
Another use of Find and Replace is to extract the email domain. This gives you the domain after @, which is not always the company website; a contact might use a personal email provider.
Duplicate your email property to preserve the source. For cells containing one plain email address, use this regular expression with an empty replacement:
^[^@\s]+@(?=[^@\s]+$)
This handles local parts with dots, plus signs, and hyphens. For example, jane.smith+sales@example.com becomes example.com. The older screenshot below uses a more restrictive pattern; use the expression above.
Trim surrounding spaces first. Cells with a display name, several addresses, or malformed email text need separate cleaning. This transformation extracts a domain; it does not validate the mailbox.
Split Full Name into First Name and Last Name
When scraping lead lists, you get contact with "Full Name" that you have to split into "First Name" and "Last Name". Being able to accurately parse a person's name into its constituent parts is a crucial step.
Separating name fields can help with addressing contacts and mapping data to a CRM. Keep the full name so you can review incorrect splits; a name alone does not establish a person's gender or title.
The task of splitting names can be complicated. Fortunately, Datablist provides an easy-to-use tool to split "Name" into two values using the space as a delimiter.
To start, open the "Split Property" tool in the "Edit" menu.
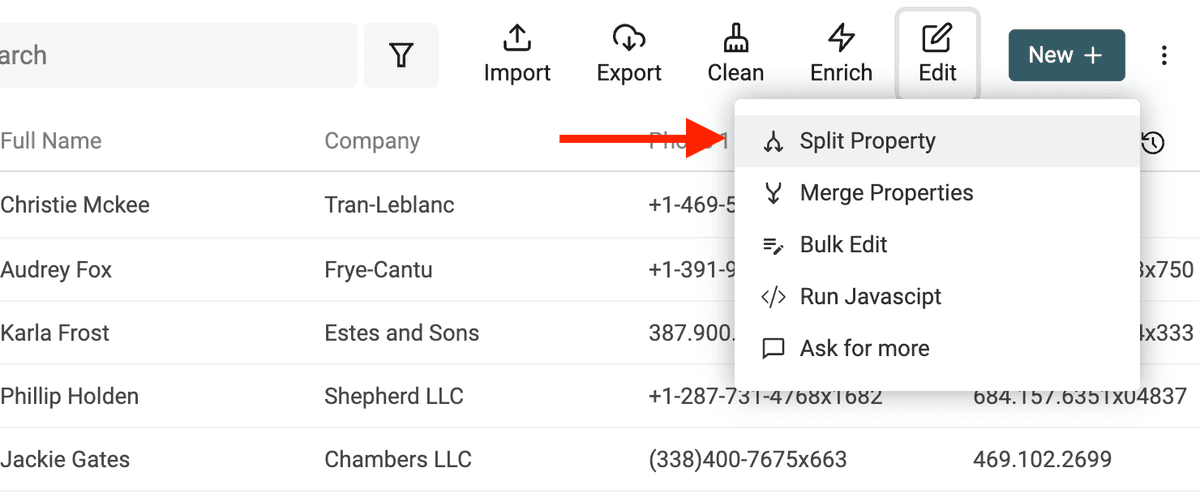
Then, select your property with the names to parse. Select Space for the delimiter. And set the max number of parts to 2.
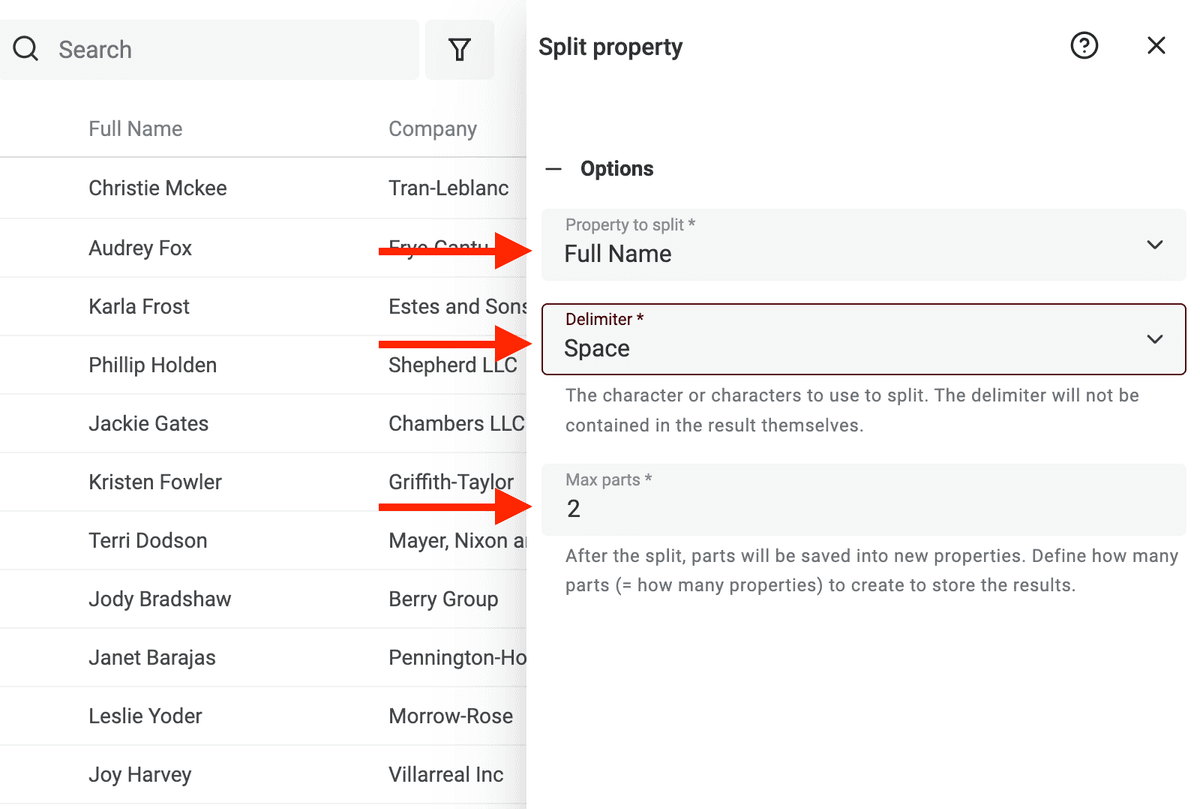
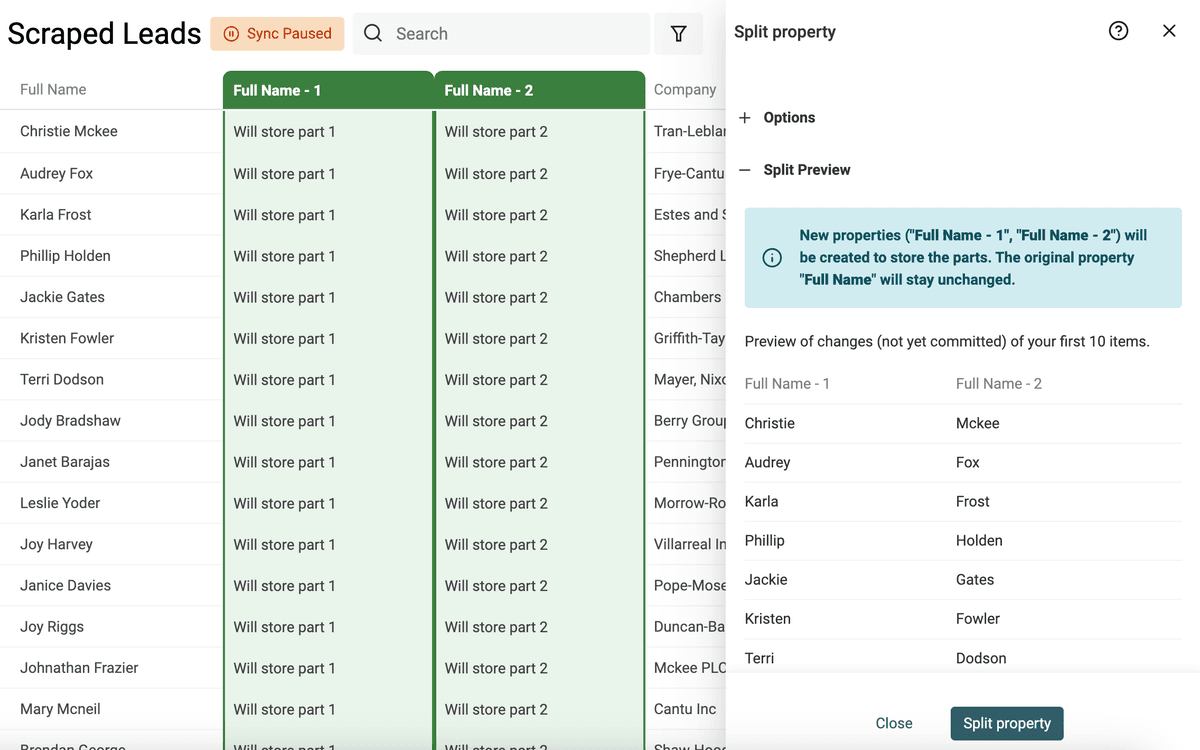
Run the preview. Datablist will parse your first 10 items to generate a preview. If the results are good, click "Split Property" to run the algorithm on all your current items.
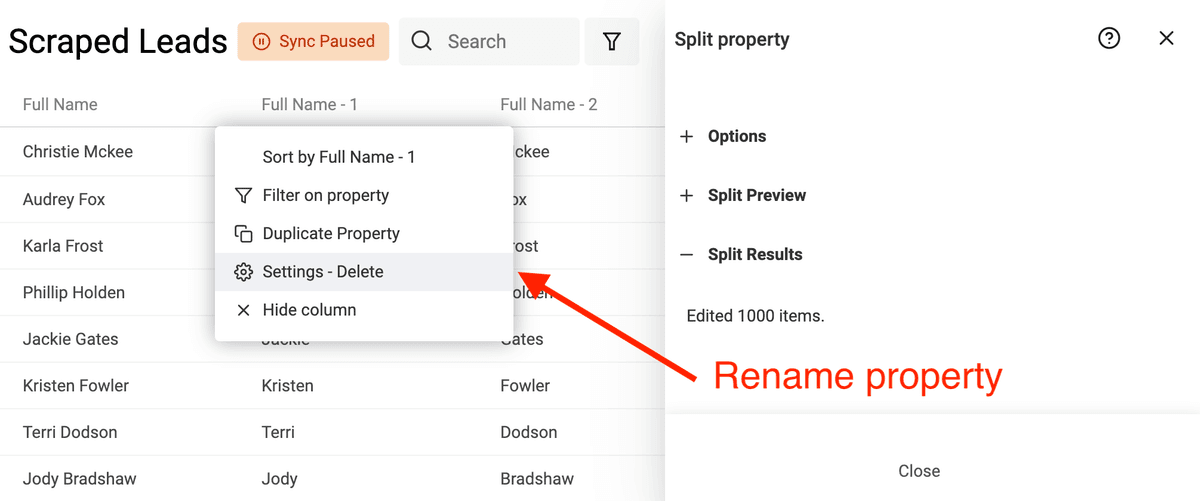
After running the splitting algorithm, rename the two created properties with "First Name" and "Last Name".
This example focuses on parsing names in the Western naming convention, which typically includes a first name and a last name. It can become more complex when dealing with non-Western names, including those with multiple given names or surnames. Or when names have titles or suffixes.
Data Deduplication
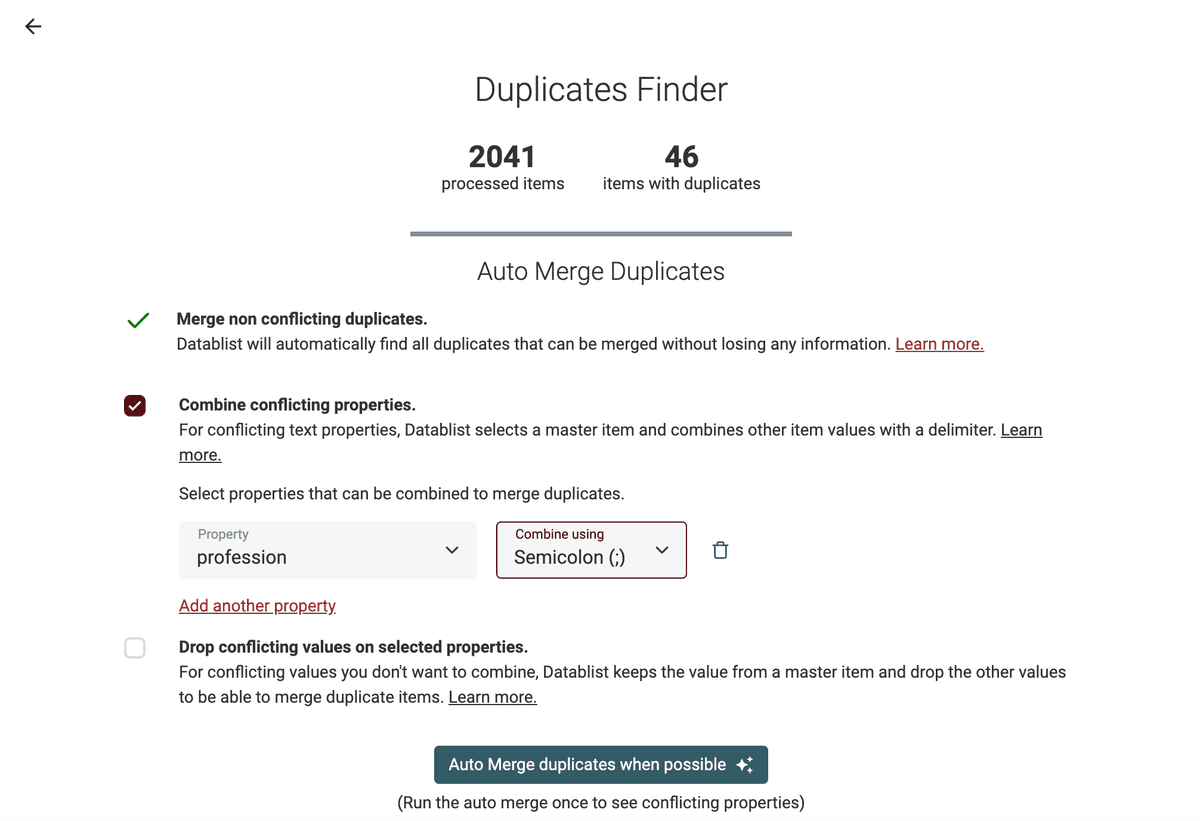
Open Clean > Merge duplicates when several rows contain information you want to retain. Use Remove duplicates when you want to keep one row unchanged and delete the others. The screenshot below shows an earlier menu layout.
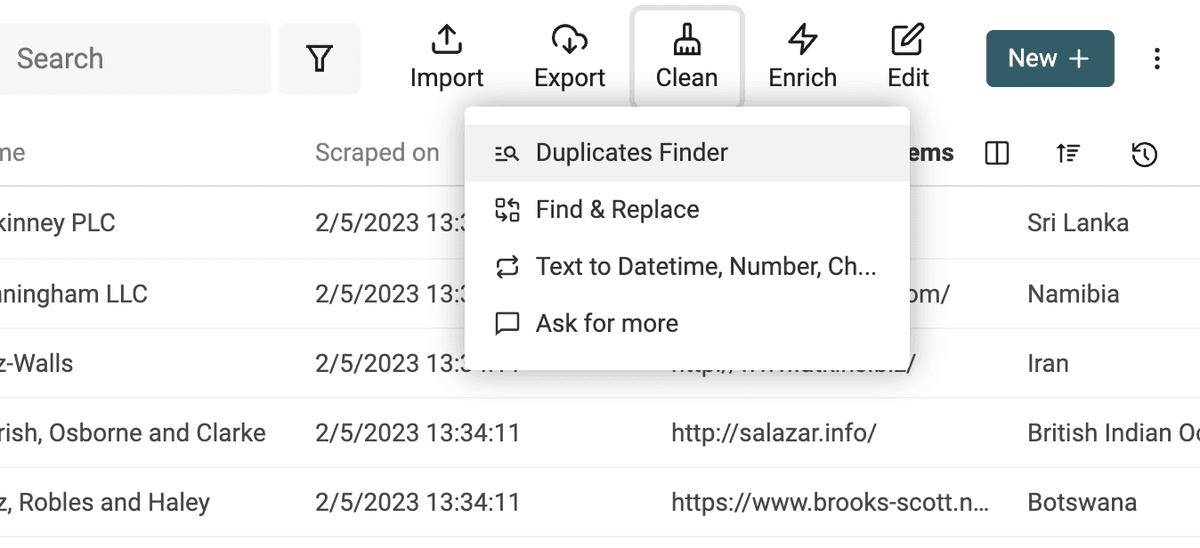
Select the properties that identify one record. I start with a contact email or a product URL rather than a company name alone. Normalizing every field is unnecessary when a reliable match key already exists.
The check creates groups for review without changing your data. In the result workspace, choose Merge and preserve data, inspect Record to keep, and configure rules under Resolve conflicting values. Combine text values when you need both; keep one value only when you are prepared to discard the others.
Review the Ready groups before clicking Merge ready groups. If you choose removal instead, inspect the removed rows for extra data because that mode leaves the kept row unchanged.
Validate Email Addresses
Data from scraping can be old, can have typos, or it can be invalid. This is especially true for email addresses that you get from scraping.
When the data is user generated, you will get fake email addresses in your database. Or email addresses from a disposable provider.
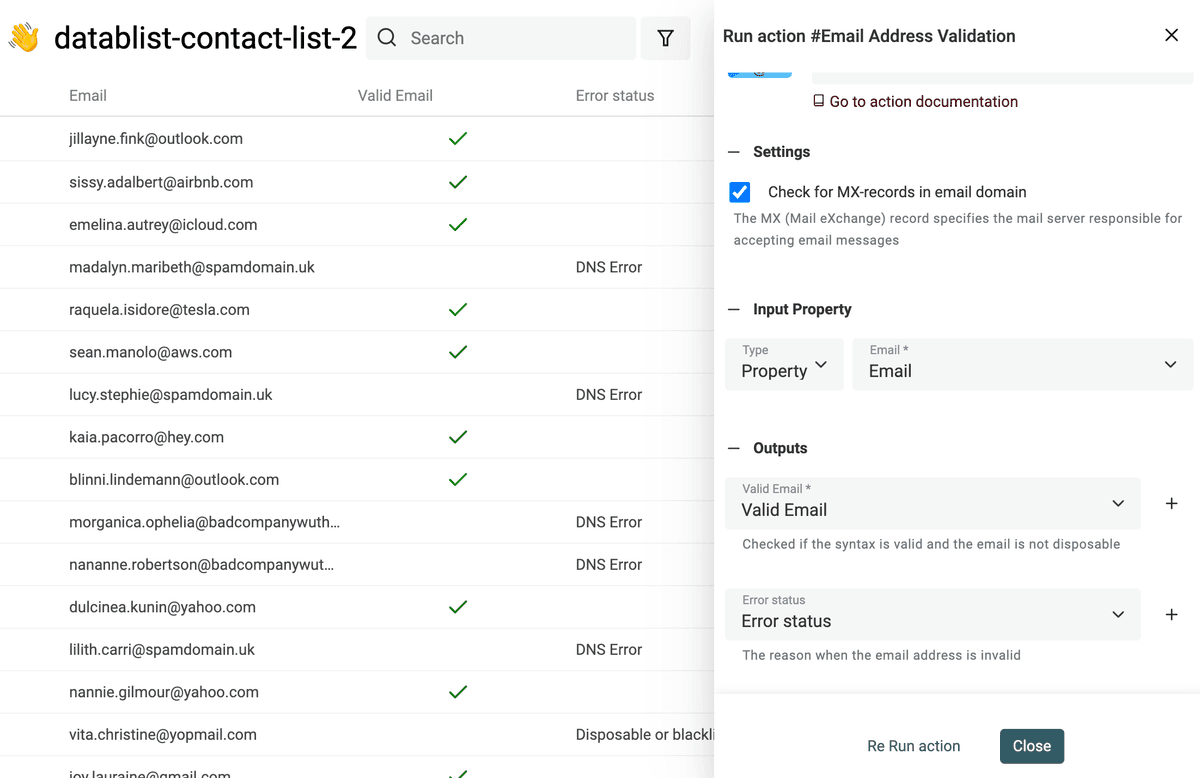
Datablist has a built-in email validation tool that let you validate thousands of email addresses.
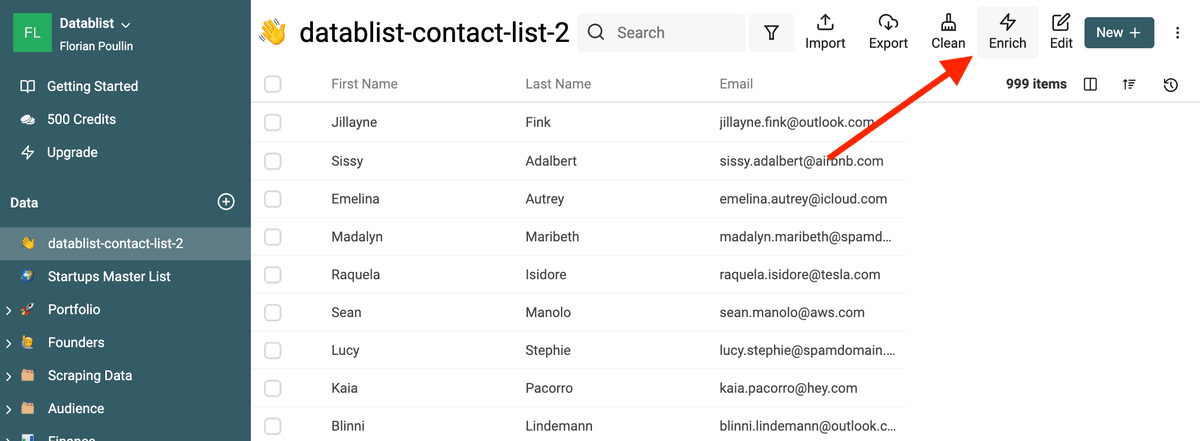
The free email cleaning service checks syntax, disposable domains, and domain MX records when that check is enabled. These checks do not prove that a specific mailbox exists or that a message will be delivered. Keep the returned status or reason so you can review exceptions.
The service provides:
- Email syntax analysis - Flags malformed addresses, such as text without an
@sign or with an invalid domain format. - Disposable providers check - The second check is to detect temporary emails. The service looks for domains belonging to Disposable Email Address (DEA) providers such as Mailinator, Temp-Mail, YopMail, etc.
- Domain MX records check - Looks up the domain's mail-server records unless you enable Disable MX-records analysis. Review failed or missing DNS results separately from syntax errors; the check concerns the domain, not the individual mailbox.
- Business and Personal Email addresses Segmentation - With prospects from lead magnets or to segment your user base, you might want to segment your contacts between business emails and personal ones. The email validation service gives you this information to enrich your contacts' data.
Extract person or business names from scraped texts
When scraping text from websites or other sources, it's often useful to be able to extract the names of people or businesses. This information can be used for a variety of purposes, such as lead generation or competitor analysis. However, extracting names from unstructured texts can be challenging, as names can take many different forms and may be embedded within larger blocks of text.
One of the main challenges in name extraction is the wide variety of naming conventions and formats that exist across different cultures and languages. For example, some cultures place the family name before the given name, while others do the opposite. Some people have multiple given names, while others have none. Additionally, names may be misspelled, abbreviated, or written in non-standard formats, making it difficult to identify them using simple pattern-matching techniques.
One common approach is to use Named Entity Recognition (NER), which is a natural language processing technique that identifies and classifies named entities in text. NER models can be trained to recognize different types of named entities, such as people, organizations, and locations, and can be customized to handle different naming conventions and variations.
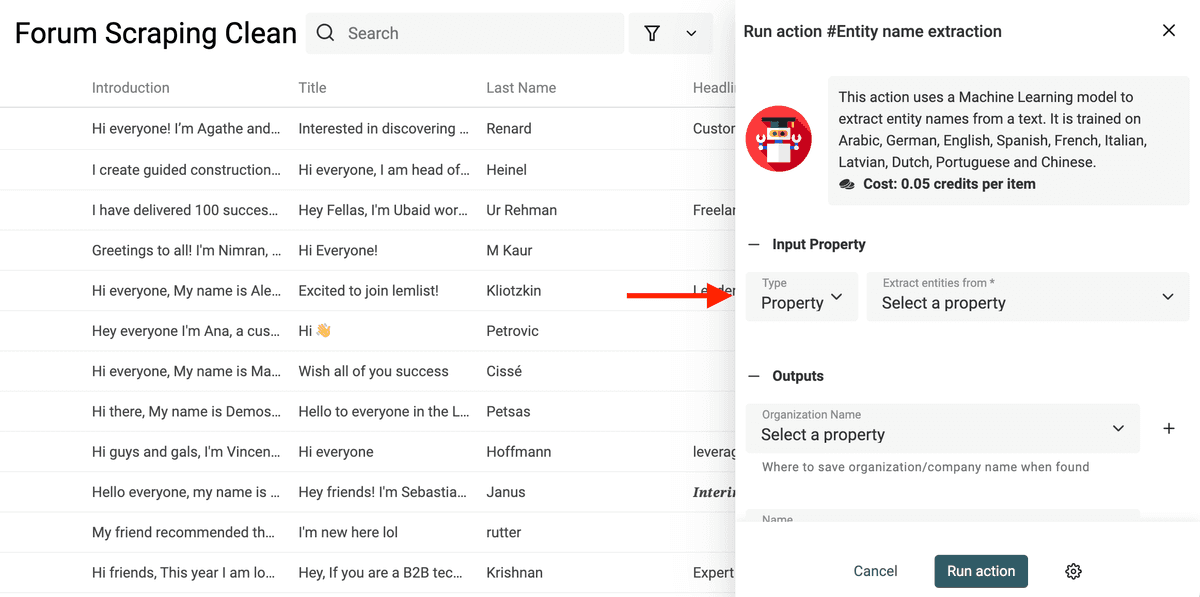
Datablist includes a powerful "Named Entity Recognition" (NER) model that you can run directly on your texts. It is trained in Arabic, German, English, Spanish, French, Italian, Latvian, Dutch, Portuguese, and Chinese.
Select the "Entity name extraction" from the "Enrichments" menu.
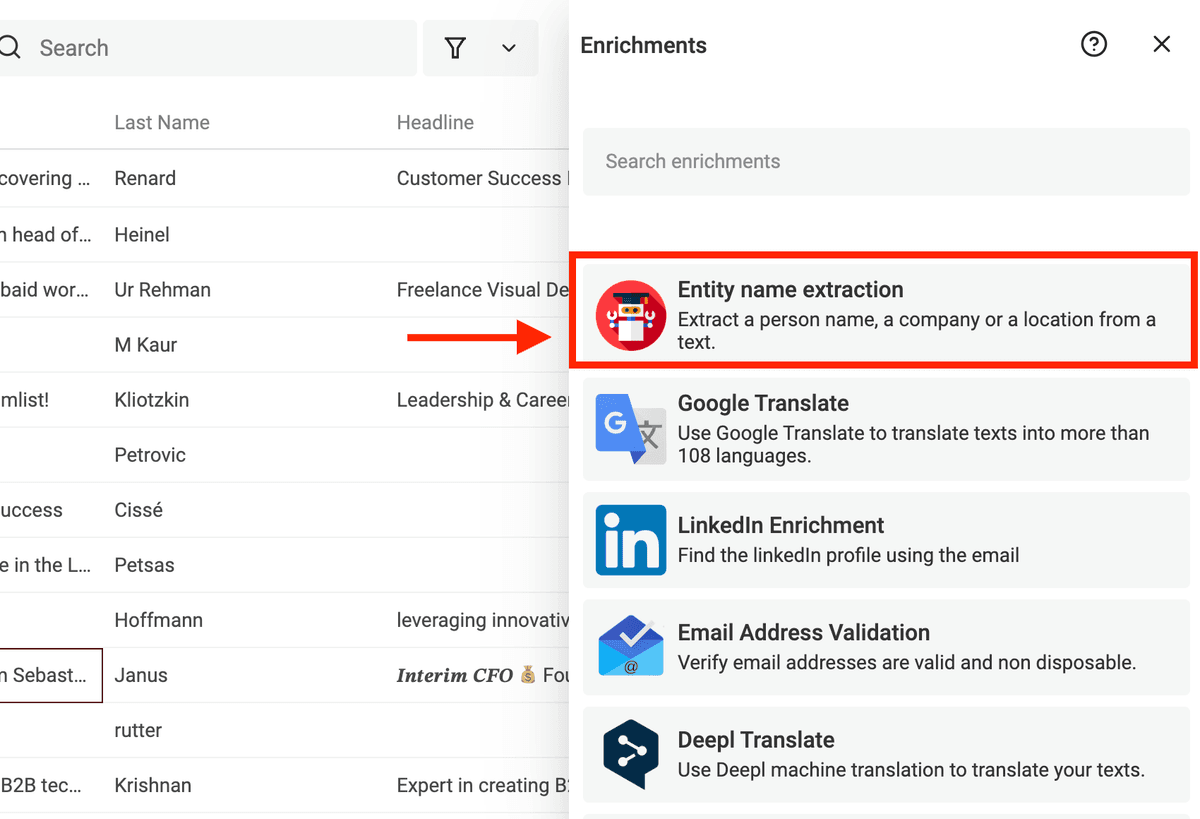
Then in the input option, select your property with text to extract names from.
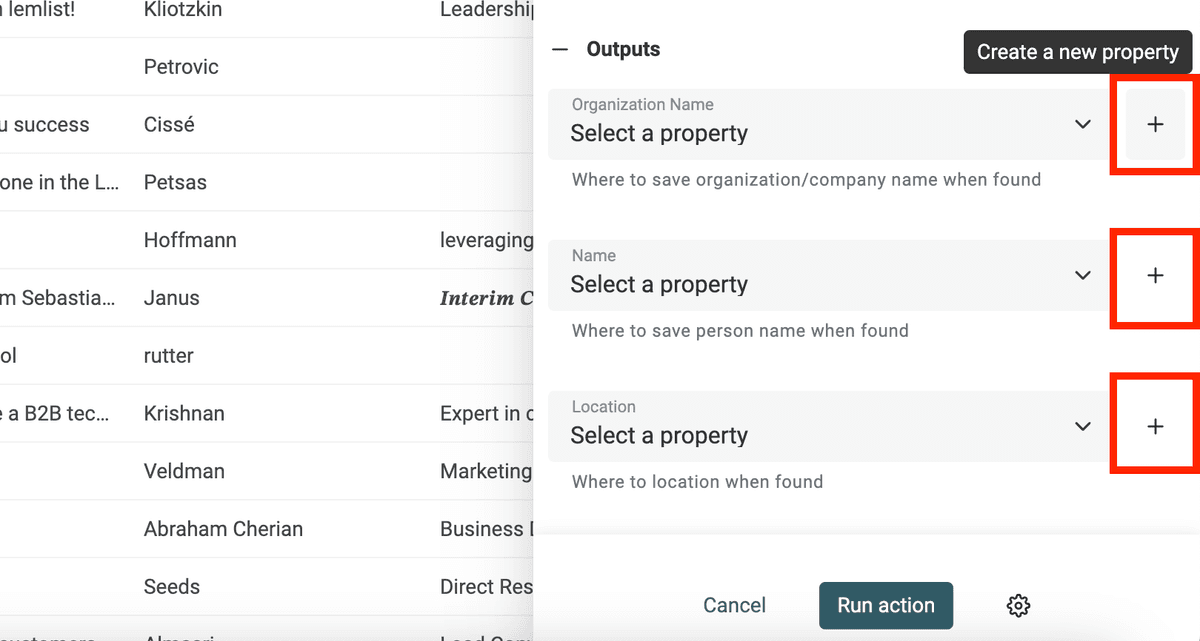
In the outputs, click on the "Create a new property" button for each kind of name you want to extract.
Datablist Entity Name extractor looks for:
- Organization Name: For example companies.
- Person Name: Full name or First Name/Last Name
- Location: Extract city, country and places
Then run the enrichment.
Need help with your data cleaning?
I'm always looking for feedback and data cleaning issues to fix. Please contact me to share your use case.