
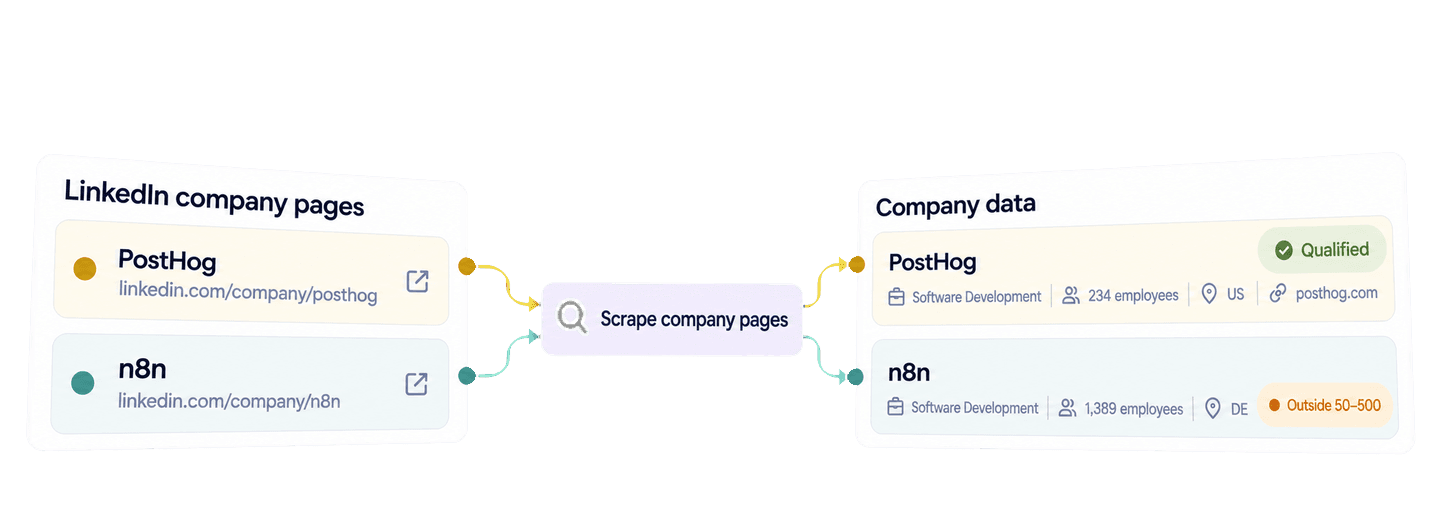
你可以使用 Requests 库,将一组 LinkedIn 公司主页 URL 发送至 Datablist API,从而在 Python 中抓取 LinkedIn 公司数据。如果公开公司主页上提供了相关信息,API 会返回结构化公司记录,包括行业、员工人数、总部所在地、网站和公司简介等字段。
本指南会使用一个易读的 Python 函数,获取 n8n、PostHog、Back Market 和 Datablist 的公司记录。然后复用这些结果,筛选总部位于美国或德国、员工人数为 50 至 500 人的软件公司账户。筛选后的记录会保留公司网站和简介,方便后续开展更深入的销售调研。
🔑 赶时间?先看摘要
Datablist 可以将经过确认的 LinkedIn 公司主页 URL 转换为结构化公司记录,供销售调研工作流使用。下面的 Python 示例会获取所有结果分页,再在本地筛选账户,无需发起第二次 API 调用。
- **输入:**LinkedIn 公司主页 URL。
- **输出:**可获取的公司详情和本地筛选结果,并将原始 URL 与完整公司数据保存在一起。
💡 **更喜欢 no-code 方案?**使用 Datablist 的 LinkedIn Company Page Scraper,无需编写代码,即可从已知的 LinkedIn 公司主页 URL 中提取公司字段。
配置 Python 和 Datablist API Key
本 Python 示例使用 requests 包。Datablist REST API 仅在 Growth 套餐中提供,每次查询公司主页都会消耗 enrichment credits。
请前往 Datablist API 账户页面创建 Personal API Key。
创建名为 scrape_linkedin_companies.py 的文件,然后配置虚拟环境并安装 Requests:
python -m venv .venv
source .venv/bin/activate
python -m pip install requests
export DATABLIST_API_KEY="your-api-key"脚本会从 DATABLIST_API_KEY 读取密钥,并通过 X-API-Key header 发送。
用一个 Python 函数抓取 LinkedIn 公司主页
下面的来源列表包含行业、规模和总部所在国家各不相同的公司。每个 account_id 都会成为 API 的 inputId。结果并不是按照响应中的位置与输入数据关联,因此需要使用这个稳定 ID,将每条结果匹配到正确的来源 URL。
将以下完整脚本粘贴到 scrape_linkedin_companies.py:
import json
import os
import time
import uuid
import requests
accounts = [
{
"account_id": "account-n8n",
"linkedin_company_url": "https://www.linkedin.com/company/n8n/",
},
{
"account_id": "account-posthog",
"linkedin_company_url": "https://www.linkedin.com/company/posthog/",
},
{
"account_id": "account-back-market",
"linkedin_company_url": "https://www.linkedin.com/company/back-market/",
},
{
"account_id": "account-datablist",
"linkedin_company_url": "https://www.linkedin.com/company/datablist/",
},
]
def scrape_companies(accounts, api_key):
"""Submit one task, wait for it to finish, and return every result."""
tasks_url = "https://api.datablist.com/v1/enrichments/tasks"
headers = {"X-API-Key": api_key}
inputs = [
{
"inputId": account["account_id"],
"data": {"companyLinkedInUrl": account["linkedin_company_url"]},
}
for account in accounts
]
unique_id = str(uuid.uuid4())
print(f"Request ID: {unique_id}")
payload = {
"enrichmentId": "linkedin-company-enrichment",
"uniqueId": unique_id,
"settings": {},
"inputs": inputs,
}
response = requests.post(tasks_url, headers=headers, json=payload)
response.raise_for_status()
task = response.json()
task_id = task["@id"]
task_url = f"{tasks_url}/{task_id}"
print(f"Task ID: {task_id}")
while task["status"] not in ("completed", "failed", "stopped"):
time.sleep(3)
response = requests.get(task_url, headers=headers)
response.raise_for_status()
task = response.json()
if task["status"] != "completed":
raise RuntimeError(
f"Task {task_id} {task['status']}: {task.get('error')}"
)
results = []
results_url = f"{task_url}/results"
params = {"limit": 100}
while True:
response = requests.get(results_url, headers=headers, params=params)
response.raise_for_status()
page = response.json()
results.extend(page["results"])
next_cursor = page["nextCursor"]
if next_cursor is None:
break
params["cursor"] = next_cursor
return results
api_key = os.environ.get("DATABLIST_API_KEY")
if not api_key:
raise RuntimeError("Set DATABLIST_API_KEY before running this script.")
company_results = scrape_companies(accounts, api_key)
print(json.dumps(company_results, indent=2, ensure_ascii=False))运行命令:
python scrape_linkedin_companies.py主要需要修改的是 accounts 中的记录。确保每个 account_id 固定且唯一,再将 linkedin_company_url 替换为已确认的 LinkedIn 公司主页。该函数会把这些记录转换为 API 所需的 inputs 格式,并通过 companyLinkedInUrl 发送公司 URL。由于此 enrichment 没有公开设置,settings 保持为空。
POST 请求会创建一个后台 enrichment task。API 返回 202 Accepted 和 task ID,Requests client 则通过轮询状态 URL 等待任务完成。对于小型脚本,这种阻塞式 Python 代码用起来很方便,但任务在 Datablist 端仍然是异步运行的。
第一个 GET 请求用于检查任务本身。任务可能以 completed、failed 或 stopped 状态结束。脚本只会在状态为 completed 时继续执行;否则会抛出错误,其中包含 task ID 和 API 返回的任务错误。排查问题时请保留该 ID,因为即使任务失败或停止,也可能仍有结果和 credits 使用情况需要检查。
任务完成后,最后一个循环会以每页 100 条的上限获取结果,并持续请求下一页,直到 nextCursor 为 null。每条结果都会保留你提交的 inputId。因此,即使响应顺序与输入顺序不同,后续的筛选循环也能正确匹配结果。
查看公司结果并理解数据获取方式
LinkedIn URL 可以直接标识公司。Datablist 会标准化该公司 URL,并获取可用的公开公司主页数据,而不是搜索多个候选公司并逐一评分。对于指定公司的 URL,它会从公开主页开始获取信息,并在保留已有有效值的同时,通过托管的 fallback 数据源补充尚未解析出的字段。
理解这一点有助于正确解读结果。可选字段取决于公开可用的信息。总部地址为 null 或缺少专长字段,并不代表整个公司查询失败。
以下是这四个 URL 返回的完整结果页:
{
  "taskId": "69516a973dc34481920f41ade748e917",
  "results": [
    {
      "inputId": "account-n8n",
      "status": "success",
      "outputs": {
        "companyName": "n8n",
        "companyHQPostalCode": "10115",
        "companyDescription": "n8n is a workflow automation platform that uniquely combines AI capabilities with business process automation. The platform enables connection to any app or API while maintaining the flexibility of code with the speed of no-code.\n\nReleased under a fair-code license, n8n can be self-hosted and is supported by a vibrant community of developers and builders. Users can start simple and layer complexity as needed - utilizing the visual builder for quick wins, and adding custom Javascript or Python code where more control is required, enabling the connection of anything to everything.\n\nn8n is privately held, with funding from Sequoia, Felicis Ventures, Firstminute Capital, Harpoon Ventures, and others. Individual investors include Eventbrite's Kevin Hartz and Supercell's IIkka Paananen. n8n was founded in 2019 and is headquartered in Berlin.",
        "companyTagline": "Flexible AI workflow automation for technical teams.",
        "companyIndustry": "Software Development",
        "companySpecialities": "AI, SOAR, Workflow Automation, and AI agents",
        "companyWebsite": "https://n8n.io",
        "companyHQCity": "Berlin",
        "linkedInCompanyId": "28491094",
        "companyType": "Privately Held",
        "companyHQCountry": "DE",
        "companySize": 1389,
        "companyLogoUrl": "https://media.licdn.com/dms/image/v2/D4D0BAQEgEphZqatXwA/company-logo_200_200/B4DaFY.Sa2JcAE-/0/1792494086070/n8n_logo?e=2147483647&v=beta&t=NTL4C6f5QAd_o9nXd15PO8pOMSSEoms_tJdDHEo6eLk",
        "companyHQAddress": "Novalisstraße 10",
        "companyFoundedYear": 2019,
        "companyFollowerCount": 442229
      },
      "creditsUsed": "25",
      "error": null
    },
    {
      "inputId": "account-posthog",
      "status": "success",
      "outputs": {
        "companyName": "PostHog",
        "companyHQPostalCode": null,
        "companyDescription": "At PostHog, we're working to increase the number of successful products in the world.\n\nUntil now, tools for building products have been fragmented. Product analytics, heatmaps, session recording, web analytics, feature flags, and A/B testing are all helpful, but no one wants to buy, send data to, and integrate multiple products.\n\nPostHog offers these tools (and more) in an integrated, open source platform which can be hosted in either the US or EU. Both versions are SOC2 certified, GDPR-ready, and HIPAA compliant. \n\nWe started PostHog during Y Combinator's W20 cohort and had the most successful B2B software launch on Hacker News since 2012 - with a product that was just 4 weeks old.\n\nWith over 100,000 users, we're default alive, growing 97% through word of mouth, and we are in the top 0.01% most popular repos on GitHub.",
        "companyTagline": "Your product's context layer. Get started with npx @posthog/wizard",
        "companyIndustry": "Software Development",
        "companySpecialities": "analytics, open source, product analytics, product, data, engineering, self-driving product, session replay, context warehouse, AI, product context, and error tracking",
        "companyWebsite": "https://posthog.com/",
        "companyHQCity": "San Francisco",
        "linkedInCompanyId": "37415928",
        "companyType": "Privately Held",
        "companyHQCountry": "US",
        "companySize": 234,
        "companyLogoUrl": "https://media.licdn.com/dms/image/v2/D560BAQGQUyE_CXUxIw/company-logo_200_200/B56aCMWEgaJAAE-/0/1789060991251/posthog_logo?e=2147483647&v=beta&t=WfTGRSqp5UfYL33sBXx3tZ1zmFUECfUPf7JtEGPAvbA",
        "companyHQAddress": null,
        "companyFoundedYear": 2020,
        "companyFollowerCount": 59696
      },
      "creditsUsed": "25",
      "error": null
    },
    {
      "inputId": "account-back-market",
      "status": "success",
      "outputs": {
        "companyName": "Back Market",
        "companyHQPostalCode": null,
        "companyDescription": "The world is waking up to what fast tech costs. Back Market is where the revolution shops. \nWe make refurbished tech the smart, confident choice by building trust in quality, repair and circularity. New is not always better. Smarter is.\n\nAs a certified B Corp, our mission is to create a world that does more with what we already have by prolonging the lifespan of electronic devices through circularity and repair. We have grown by double digits year over year and now serve 18 million customers across 17 markets, avoiding more than 2 million tons of CO2 emissions*\n*Back Market calculation based on ADEME 2022 methodology.\n\nFounded in Paris in 2014 by Thibaud Hug de Larauze, Quentin Le Brouster and Vianney Vaute, Back Market is a leading global marketplace where people can buy professionally refurbished technology or trade in their devices.\n\nAre you ready to join us?",
        "companyTagline": "Where the world shops refurbished tech.",
        "companyIndustry": "Internet Marketplace Platforms",
        "companySpecialities": "refurbished tech, marketplace, sustainability, circularity, Right to Repair, sustainable solutions, refurbished marketplace, circular economy, and sustainable alternatives",
        "companyWebsite": "http://www.backmarket.com",
        "companyHQCity": "Paris",
        "linkedInCompanyId": "4793443",
        "companyType": "Privately Held",
        "companyHQCountry": "FR",
        "companySize": 1054,
        "companyLogoUrl": "https://media.licdn.com/dms/image/v2/D4E0BAQHRv6UClt5D2g/company-logo_200_200/B4EZnoUG3tKgAI-/0/1760539209613/back_market_logo?e=2147483647&v=beta&t=Pywpeu1Qs3h0Cl8kgvYurmBfXbImm5QIIc-aQog1MqM",
        "companyHQAddress": null,
        "companyFoundedYear": 2014,
        "companyFollowerCount": 101878
      },
      "creditsUsed": "25",
      "error": null
    },
    {
      "inputId": "account-datablist",
      "status": "success",
      "outputs": {
        "companyName": "Datablist",
        "companyHQPostalCode": null,
        "companyDescription": "When people hear \"data,\" they think of something complicated. We will change this.\n\nDatablist is an AI-powered spreadsheet that helps you: get, manipulate, or clean data and create workflows that run automatically while you focus on what matters most.\n\nIf you want to separate Datablist.com into its main parts, you can say we have:\n\n- Deduplicating, grouping, and labeling data\n- Cleaning and editing data\n- Managing data and automated workflows\n- 50+ B2B data sources and scrapers\n- 3 AI agents:\n    - Editing assistant\n    - AI Research agent\n    - Deduplication assistant\n\nThe top 3 reasons why companies choose Datablist.com are:\n\n1. Simplicity: you don't need to have technical knowledge or experience with formulas to get everything out of it.\n2. Flexibility that allows you to do (almost) everything with your data and AI while keeping everything under your control.\n3. Scalability that no other solution can match. Up to 2 million rows—forget Excel.\n\nGo on try it for free!\n\nhttps://www.Datablist.com",
        "companyTagline": "Let your tasks become workflows: automated workflows.",
        "companyIndustry": "Information Technology & Services",
        "companyWebsite": "https://www.datablist.com",
        "companyHQCity": "Paris",
        "linkedInCompanyId": "69842428",
        "companyType": "Privately Held",
        "companyHQCountry": "FR",
        "companySize": 3,
        "companyLogoUrl": "https://media.licdn.com/dms/image/v2/C4E0BAQFNFlMb8KEPRQ/company-logo_200_200/company-logo_200_200/0/1630622803412?e=2147483647&v=beta&t=UVkk7BOerChiWgS9Y06zOpT08SlK4kpAWGDYiVvUEVU",
        "companyFollowerCount": 134,
        "companyFoundedYear": 2020,
        "companyHQAddress": null
      },
      "creditsUsed": "25",
      "error": null
    }
  ],
  "nextCursor": null
}
四条记录均成功返回,每条消耗 25 credits。PostHog 返回了 Software Development、234 名员工、美国总部、公司网站和简介。n8n 同样是位于目标国家的软件公司,但返回的员工人数为 1,389。Back Market 返回 Internet Marketplace Platforms、1,054 名员工和法国总部。Datablist 返回 Information Technology & Services、3 名员工和法国总部。
保留完整对象很有价值,因为账户调研很少只看一个字段。你可以使用行业、员工人数和国家来筛选账户,同时保留 API 返回的确切网站和公司简介,供下一步调研使用。
在本响应中,companySize 是返回的员工人数,而不是 LinkedIn 的公司规模区间标签。companyHQCountry 表示总部所在地,并不代表公司开展业务的所有国家。根据理想客户画像调整公司规模和国家筛选条件时,务必注意这些区别。
筛选时,并非所有可选字段都必须存在。只要行业、员工人数和总部所在国家可用,缺失的地址或专长字段可以留空。请保留 companyWebsite 的原始返回值,不要假设 API 会将其转换为裸域名。公司简介可以帮助销售研究人员了解公司的产品,并在 Outbound 触达前完成针对该账户的调研。在审核或存储记录时,应让结果级别的 status、creditsUsed 和 error 与公司字段保存在一起。
筛选用于销售调研的目标账户
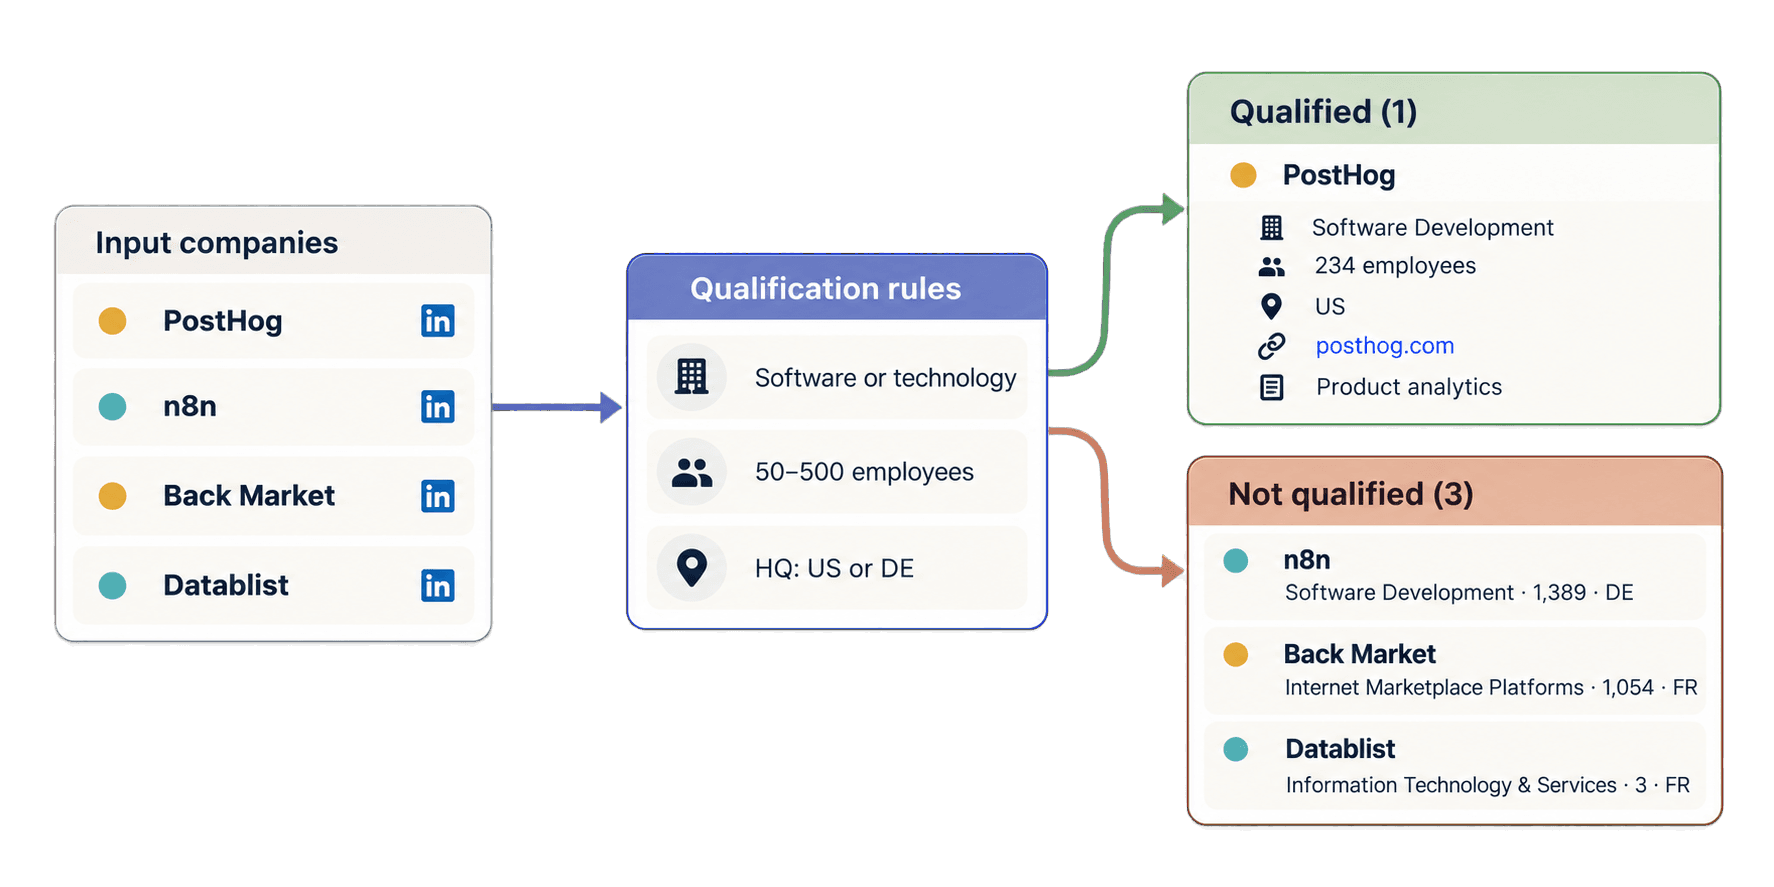
假设你的目标是总部位于美国或德国、员工人数为 50 至 500 人的软件或科技公司。将下面的循环添加到完整脚本之后。它会复用 company_results,因此不会再提交一个新任务:
accounts_by_id = {account["account_id"]: account for account in accounts}
qualified_accounts = []
other_accounts = []
for result in company_results:
account = accounts_by_id.get(result["inputId"])
qualification = "needs_review"
if result["status"] == "success":
outputs = result["outputs"]
industry = outputs.get("companyIndustry")
company_size = outputs.get("companySize")
country = outputs.get("companyHQCountry")
if industry and isinstance(company_size, (int, float)) and country:
industry_matches = any(
keyword in industry.lower()
for keyword in ("software", "technology")
)
size_matches = 50 <= company_size <= 500
country_matches = country in {"US", "DE"}
if industry_matches and size_matches and country_matches:
qualification = "qualified"
else:
qualification = "not_qualified"
source_url = None
if account is not None:
source_url = account["linkedin_company_url"]
reviewed_account = dict(result)
reviewed_account["sourceLinkedInUrl"] = source_url
reviewed_account["qualification"] = qualification
if qualification == "qualified":
qualified_accounts.append(reviewed_account)
else:
other_accounts.append(reviewed_account)
print(json.dumps(qualified_accounts, indent=2, ensure_ascii=False))即使 API 以不同顺序返回记录,PostHog 仍会正确匹配到 account-posthog。由于 Software Development、234 名员工和 US 同时满足三个条件,它会通过筛选。循环会复制原始结果,保留完整的 outputs、返回的网站 https://posthog.com/、公司简介、creditsUsed 和 error,只额外添加来源 URL 和本地筛选标签。
n8n 会匹配到 account-n8n,但由于 1,389 名员工超过上限,因此无法通过筛选。Back Market 不符合所选的行业、规模和国家条件;Datablist 则低于规模范围,且不在所选国家。未来遇到未成功或信息不完整的记录时,系统会将其标记为 needs_review,而不是直接丢弃。
你可以下载持续维护的同步 Requests 示例;如果应用需要非阻塞代码,也可以使用该代码仓库中的异步 HTTPX 版本。
估算 LinkedIn 公司数据抓取 credits
抓取一个标准的具名 LinkedIn 公司主页需要 25 credits。如果数字公司 ID URL 需要使用最后一层 fallback,则可能消耗 75 credits,但并非每个数字 URL 都会消耗 75 credits。查询失败或无匹配结果也可能消耗 credits,因此应以任务总用量及每条结果中的 creditsUsed 作为实际用量记录。
本指南中的四个具名 URL 共消耗 100 credits。按照标准费率,抓取 1,000 个公司主页需要 25,000 credits。如果输入中包含大量数字 ID,则需要为可能出现的 75-credit 路径预留更多额度。
使用 REST API 需要 Growth 套餐。月度套餐包含 20,000 credits,额外的 top-up credits 需要单独购买。按照当前美元基础价格计算,20 美元可购买 20,000 credits,即每个 credit 为 0.001 美元。按此费率,25,000 credits 的价值为 25 美元。请查看 Datablist 定价,了解最新套餐与 credits 目录。
解决常见的输入、任务和结果问题
- **缺少
DATABLIST_API_KEY:**脚本会在发送请求前停止。请导出该环境变量,然后重新运行文件。 - **API 拒绝密钥:**检查你的 Personal API Key,并确保它仍放在示例所用的
X-API-Keyheader 中。 - **来源 URL 无效:**如果输入的是个人主页、无关网站、空值或格式错误的 URL,请将其替换为受支持的公开 LinkedIn 公司、学校、Showcase Page、数字 ID 或 Sales Navigator 公司 URL。
- **credits 不足:**检查余额,然后使用套餐内 credits,或先购买 top-up 再创建新任务。
- **任务状态为
failed或stopped:**在决定是否重新提交一个付费任务之前,先检查错误、已有结果和 credits 使用情况。 - **结果内容过少,或状态为
no_result、error:**保留来源 URL、状态、credits 和错误信息,以供审核。重新提交前,请先确认输入的是公开公司主页,不要主观猜测数据为何无法获取。
如果创建任务后的响应丢失,请使用脚本在 POST 请求前打印的 request ID。先列出任务,再在 uniqueId 中匹配该值:
curl "https://api.datablist.com/v1/enrichments/tasks?limit=100" \
-H "X-API-Key: $DATABLIST_API_KEY"匹配任务的 @id 就是 task ID。使用它继续检查 /v1/enrichments/tasks/{taskId},或获取 /v1/enrichments/tasks/{taskId}/results,不要自动创建另一个任务。单次请求最多可包含 10,000 条输入,数据大小上限为 10 MiB;有关数据保留和其他生命周期细节,请参阅 task 文档。
后续步骤
现在,你已经拥有一个可复用的 Python Requests 函数,可以将一组 LinkedIn 公司主页 URL 转换为结构化公司记录;同时还有一个本地筛选循环,能够为销售调研保留完整的 API 输出。
请用一份经过确认的小型目标账户列表替换这四个示例,保持 ID 稳定,并根据理想客户画像调整行业、员工人数和国家规则。如果你的起点是联系人而不是公司,请阅读 LinkedIn 个人资料抓取 API 指南。如果你只有公司名称,可以先了解如何使用 Python 查找公司网站。