Use Extract to pull email addresses, URLs, mentions, tags, and other patterns from a text property. If you already have one email address or URL per cell, choose Extract domains from email addresses or URLs to create a domain property. Preview the first results before processing the selected items or view.
For data cleaning, the Data Extractor helps you find entities in your CSV texts. When dealing with scraped data, this tool finds URLs and email addresses in scraped text to build your lead list.
Choose the action that matches your source data:
- Email Addresses in texts
- URLs in texts
- Domains from email addresses
- Domains from URLs
- Mentions (ex: @name) in texts
- Tags (ex: #tag) in texts
How to use the Data Extractor
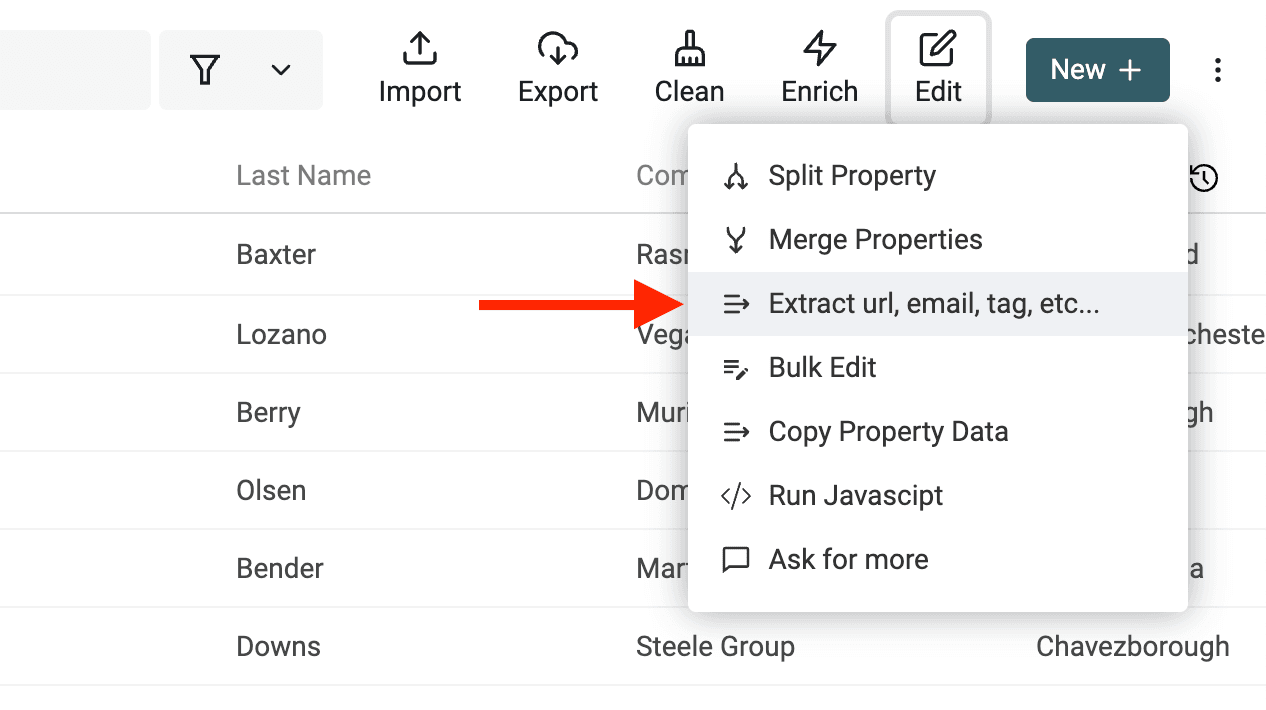
Step 1: Open the Data Extractor
The Data Extractor tool works by selecting the items to process in this order:
- If you have selected items in your collection, it will process them
- If you have a filter or a full-text search term, it will process the filtered items
- Otherwise, it will process all your collection items
Click Extract in the collection header, then choose an action such as Extract email(s) from texts or Extract domains from email addresses or URLs. The domain action expects a valid email address or URL in the source cell. To handle a sentence containing an email or URL, extract that value to a separate property first, then run the domain action on the new property.
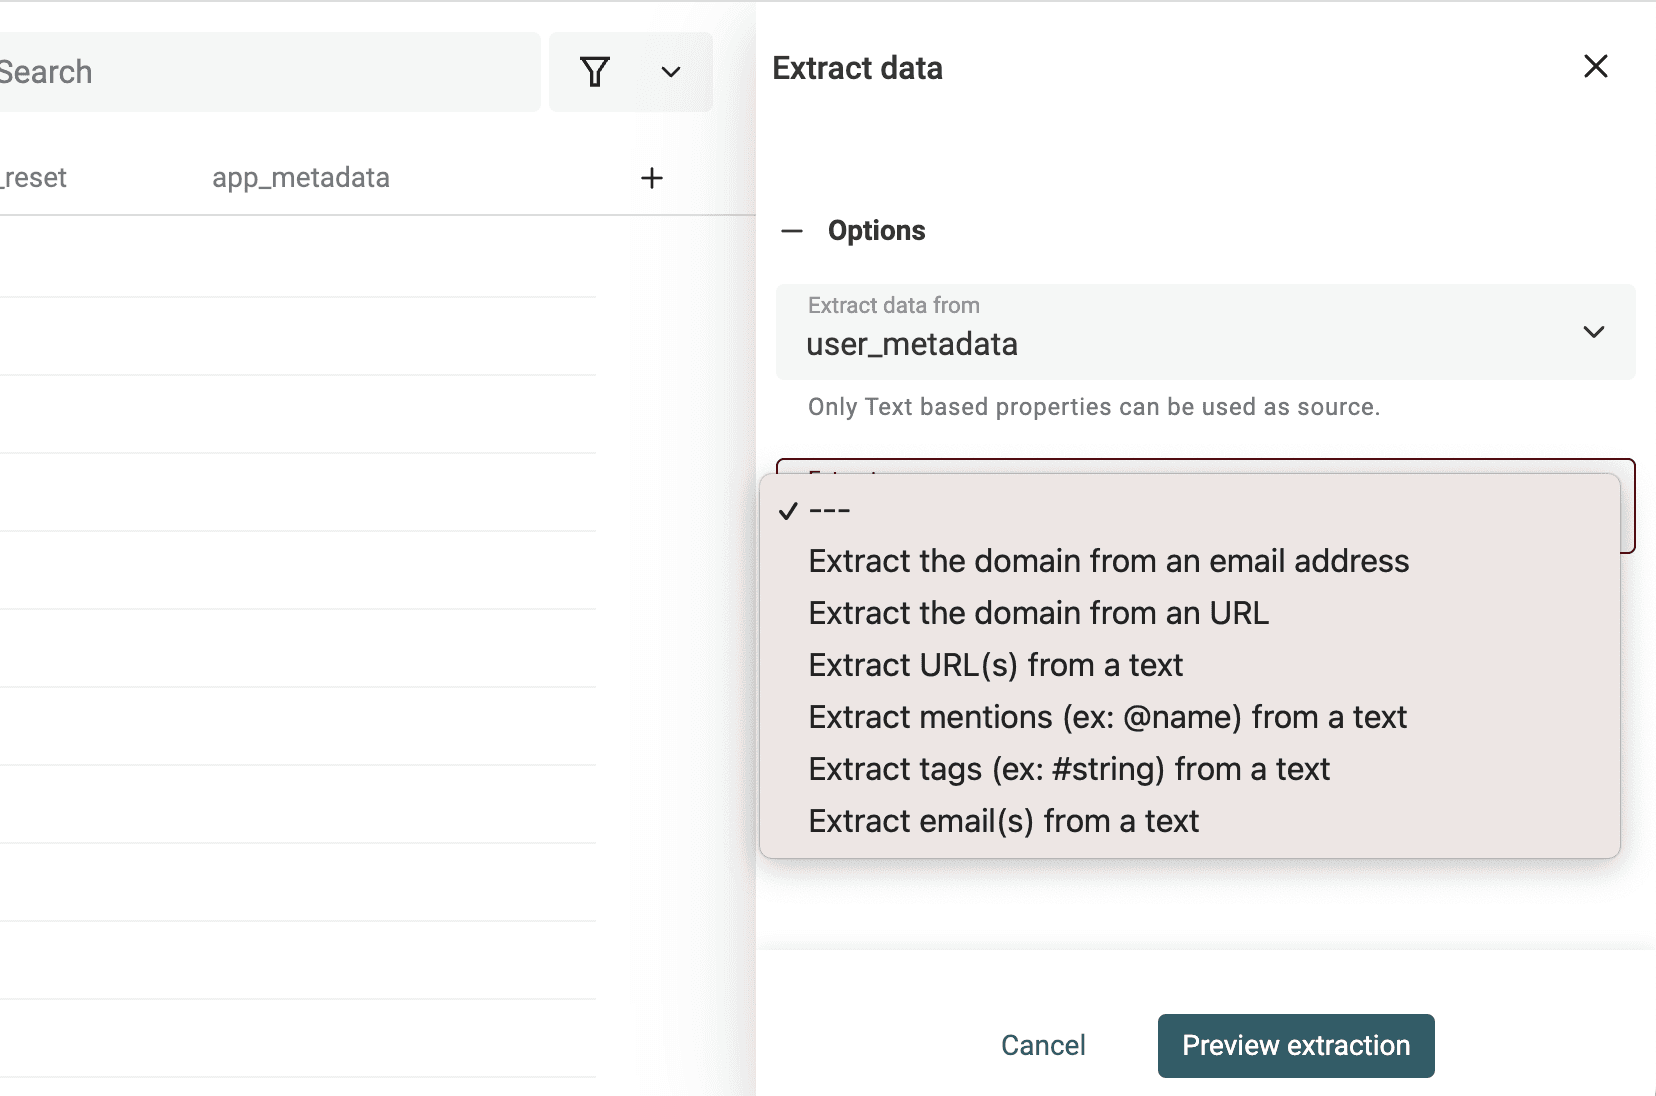
Step 2: Select a property with unstructured text
Select the text property to read. Map the extracted result to a new property if you want to keep the original value, or choose an existing destination property deliberately.
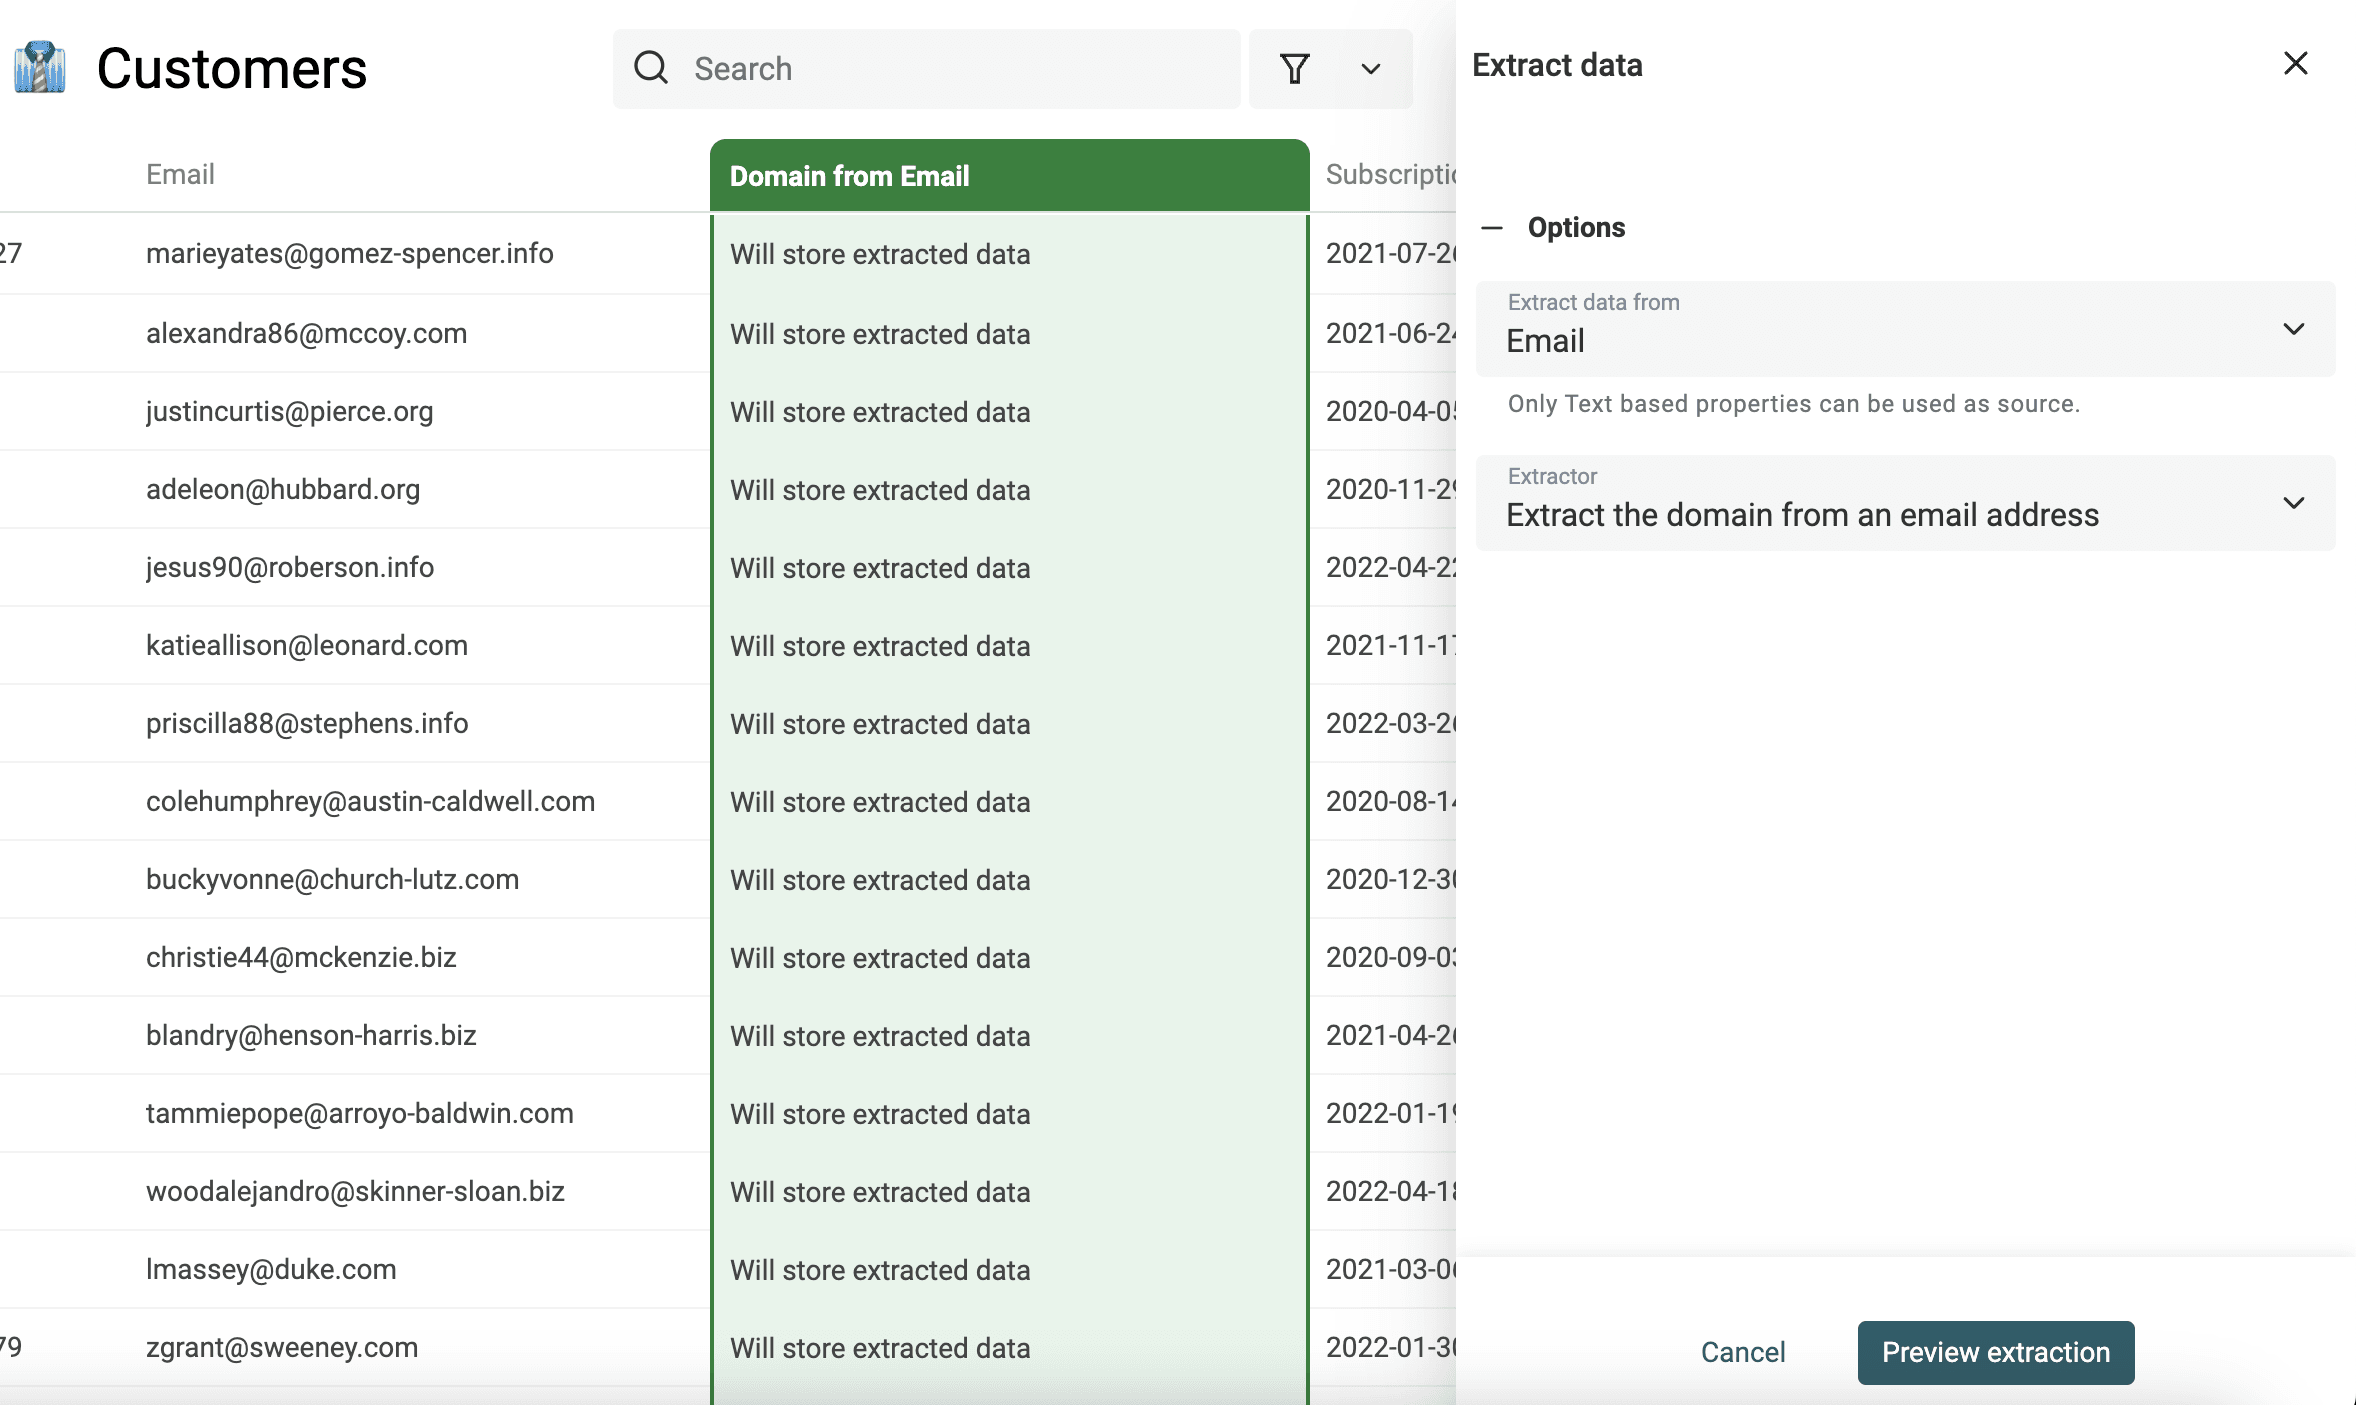
Step 3: Preview and run the Data Extractor
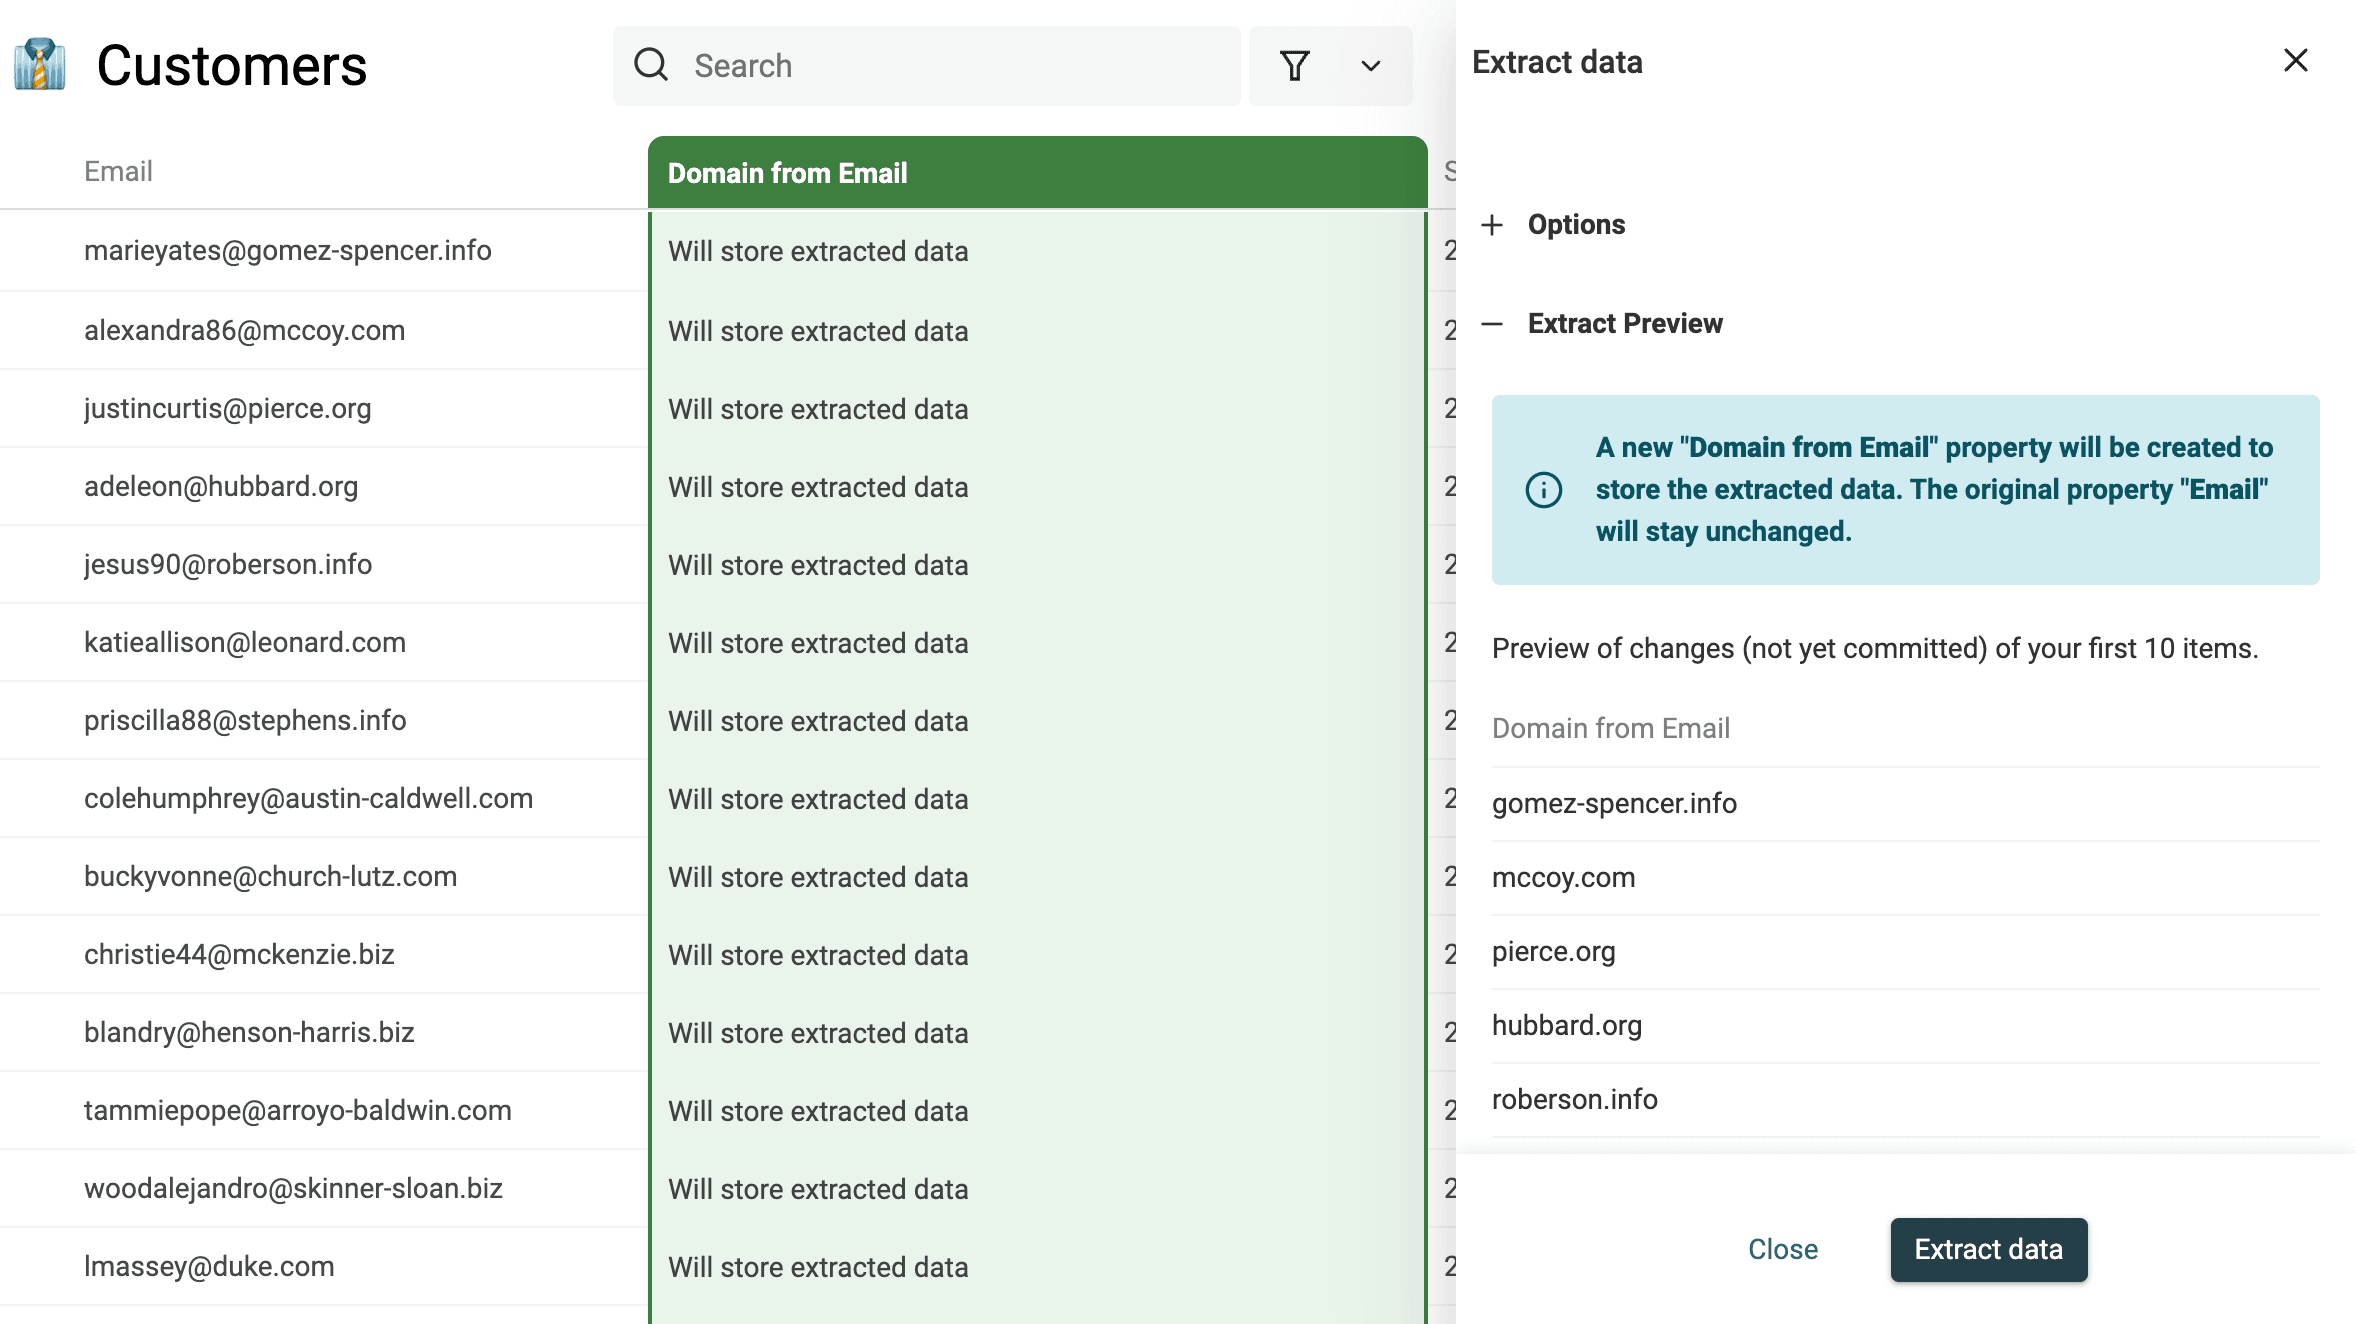
A preview shows the extraction on a small sample without saving the result. Check blanks and multi-value cells before running it on the selected scope.
If the preview results suit you, click on the "Extract data" to process your items.
Notes: The dry run step is reinitialized each time the data extractor options change.
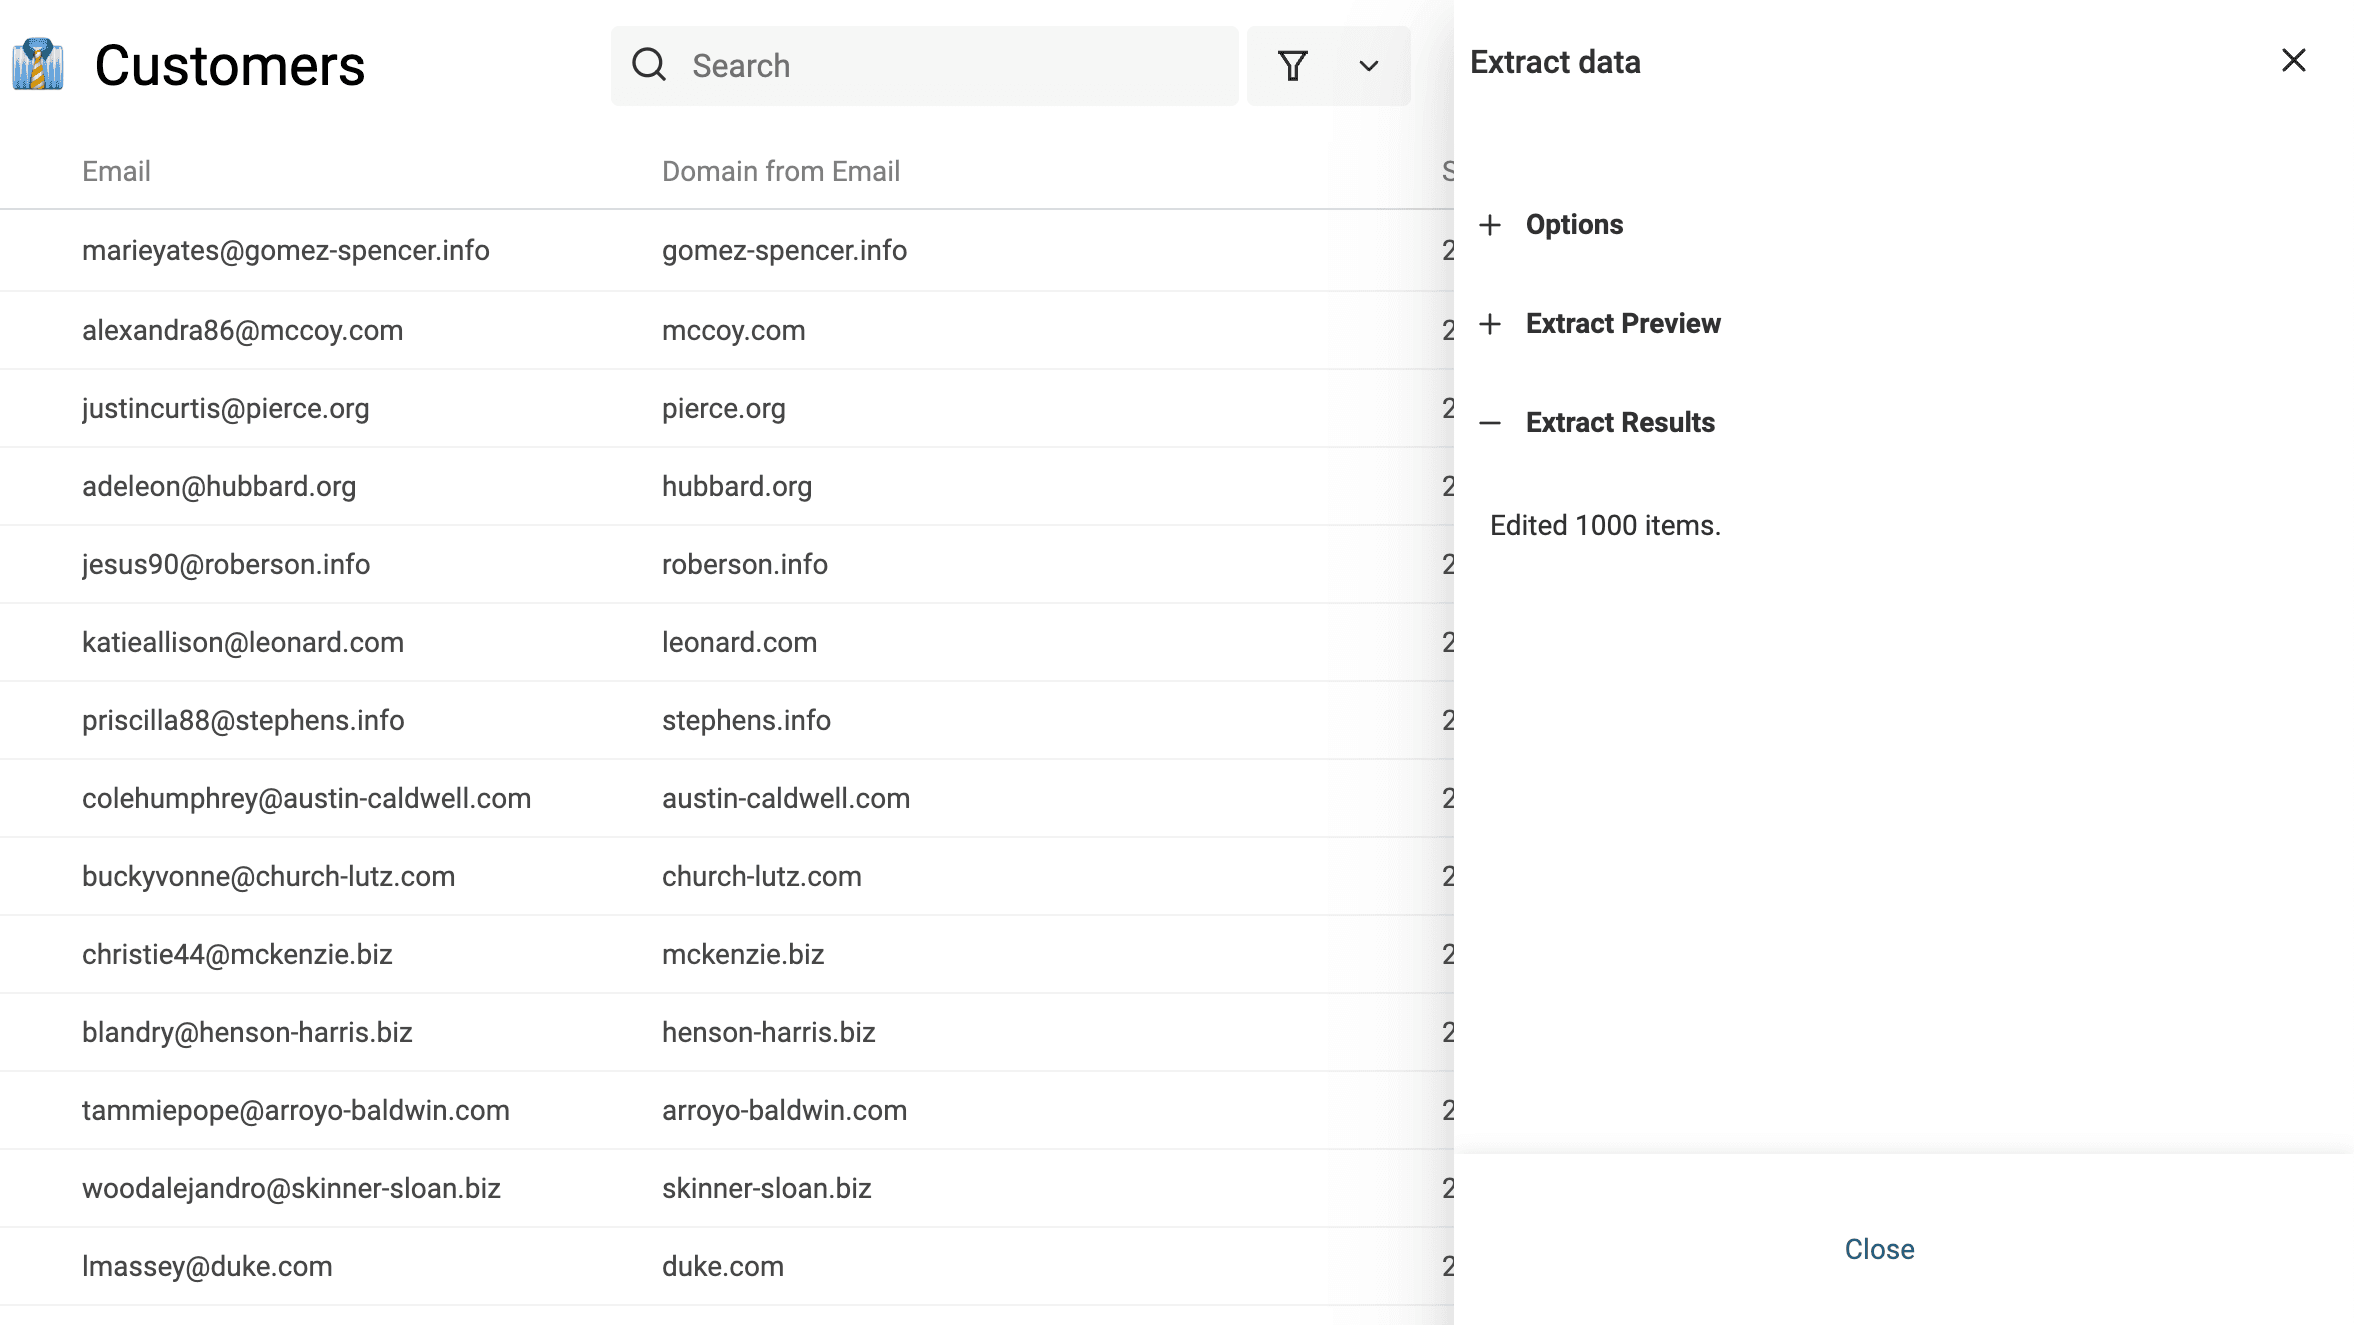
Once finished, a summary is displayed with the number of items processed. And your data table is updated with the results.
Dealing with multiple results
For actions that find several values in one text cell, the output is comma-separated text. If you need one row per email or URL, split or process the output after extraction. Inspect the extracted values before splitting: punctuation inside a URL can make a simple comma split unsuitable.
Extract a domain from a sentence
The domain action expects one email or URL, not arbitrary text. For example, first extract https://www.example.com/contact from Visit https://www.example.com/contact into a new property. Then run Extract domains from email addresses or URLs on that property to obtain example.com.
If the first step returns several emails or URLs in one cell, separate and review them before the domain step. A comma-joined list is not one valid email or URL. Keep the source text so you can trace the result back to the intended record.
What happens when there is no match?
An invalid input or a cell with no matching pattern produces no extracted result. In a new destination property, that row stays empty. When writing to an existing destination, a live run skips a no-result update and keeps the previous value; it does not clear that value.
The preview may show an empty proposed result for that row. Do not use a no-match extraction as a clearing operation. Use a new destination when you need to distinguish fresh results from older values, then compare the source and output before accepting them.
Extractor descriptions
Extract the domain from an email address
This action takes a property containing one valid email address per cell and returns its domain, including the suffix by default.
Examples:
- contact@datablist.com -> datablist.com
- jean.bond@gmail.uk.co -> gmail.uk.co
Note: Invalid input returns no domain. The action also accepts a valid URL; it does not extract a domain directly from an arbitrary sentence.
Extract email addresses from a text
This extractor parses a text property to find one or several email addresses.
For example, from a text such as:
Please contact us at name@gmail.com for any inquiries about XXX.
Or use the following email address for customer support questions: support@xxx.com
The extractor returns: name@gmail.com,support@xxx.com
Extract URLs from a text
This extractor parses a text property to find one or several URLs. If the source is a webpage open in your browser rather than a text cell, export its clickable links to CSV first.
For example, from a text such as:
Visit our online documentation at https://docs.datablist.com
The extractor returns: https://docs.datablist.com
Note: To be valid, the URLs must be absolute, with scheme (https, http, or ftp, etc). A partial URL like
doc.datablist.comwon't be returned.
Extract the domain from a URL
This extractor takes one valid URL per cell and returns its registrable domain, including the suffix. For example, https://portal.example.co.uk/path returns example.co.uk. This is not the same as preserving the complete URL hostname. The email action keeps the domain portion after @, including an email subdomain when present.
Examples:
- https://www.datablist.com -> datablist.com
- https://www.google.io/test/path/string.html -> google.io
Note: An invalid URL produces no extracted domain. An existing destination value is retained on a live run; see the no-match behavior above.
Extract mentions from a text
This extractor parses a text and returns the mentions in it. The @ character is also returned.
Examples:
Mum, friend with @pseudo and married with @pseudo2
Returns @pseudo,@pseudo2
Extract tags from a text
This extractor parses a text and returns the tags in it. The # character is also returned.
Examples:
Live in #paris. #workhardplayhard
Returns #paris,#workhardplayhard