To run an enrichment, choose one from the catalog, configure its settings and input properties, map the outputs, then run a small sample and inspect the result. For example, with a translation enrichment, map a Description property as input and create a Translated Description output property. The source text remains available for comparison.
First step: Configure Settings and Inputs
Datablist asks you for some information to configure the enrichment. The first step is about the enrichment settings and input properties.
Enrichment settings are defined values that apply to the whole enrichment process.
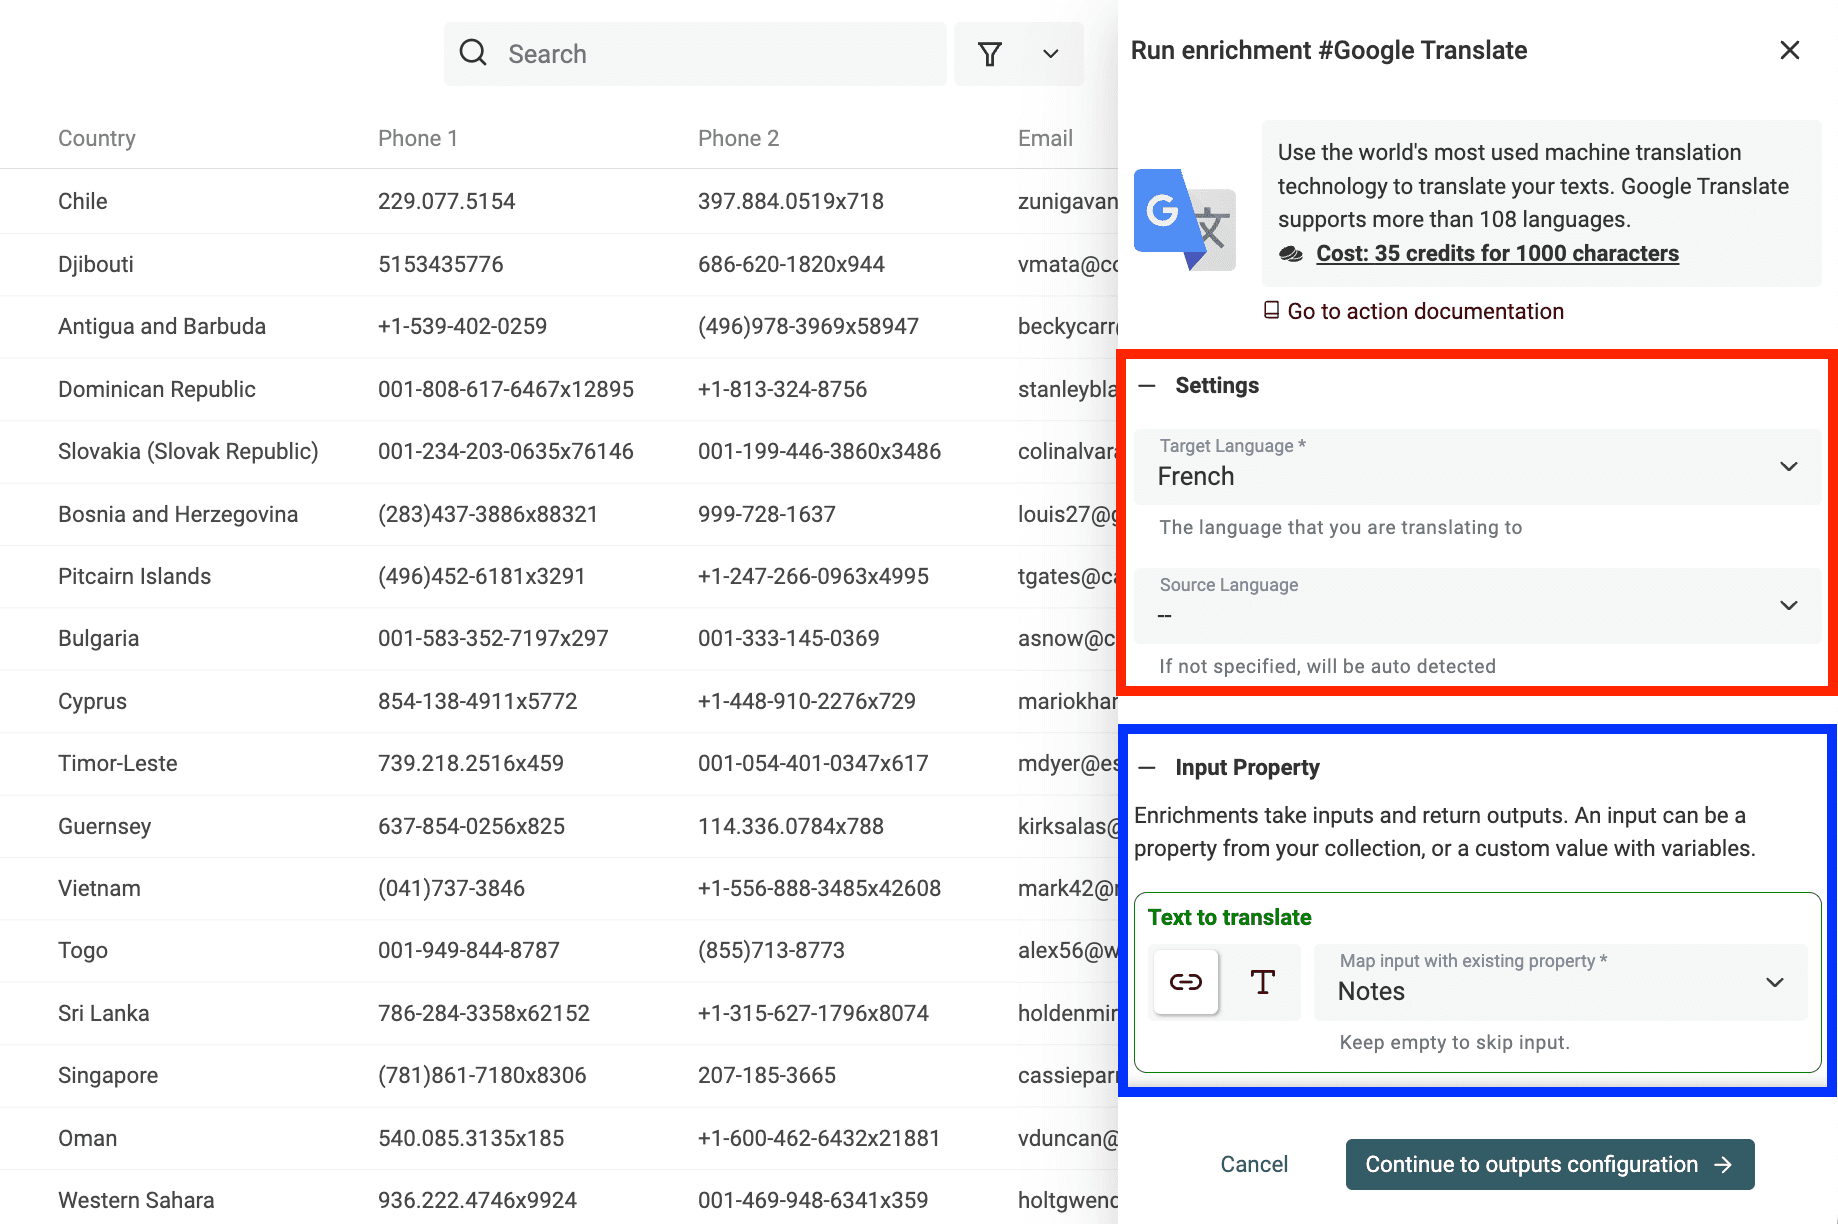
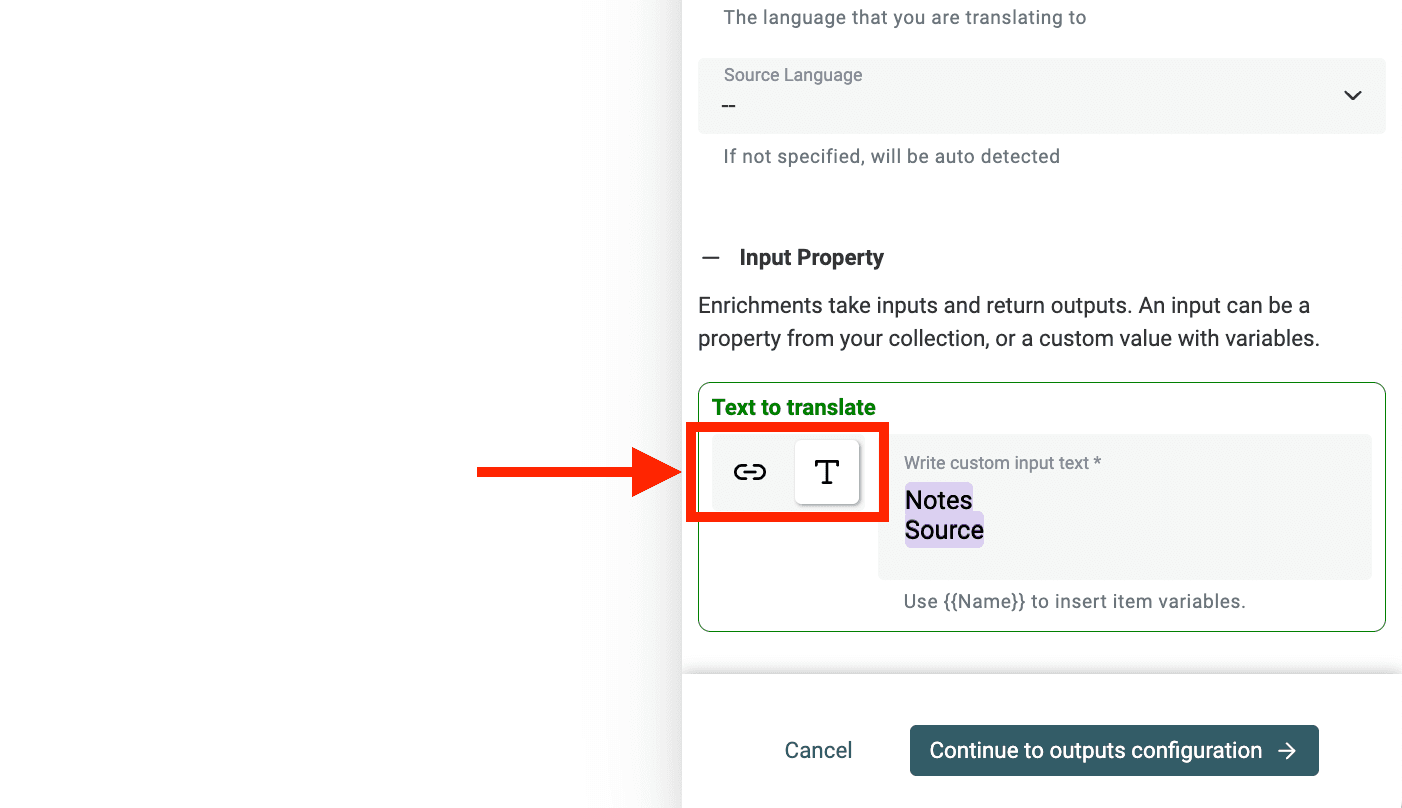
Input Properties are variable data. They are the source of data for the enrichment. For example, with a translation enrichment, the input is the text that must be translated. Each item has a distinct text. So, the input "Text to translate" might be a direct mapping with a property or a custom-built source text using texts from several properties.
Note
The values in the input properties are not edited. The result of the enrichment is saved in the output properties.
Click Continue to outputs configuration to move to the second step.
Second step: Outputs and run settings
Outputs
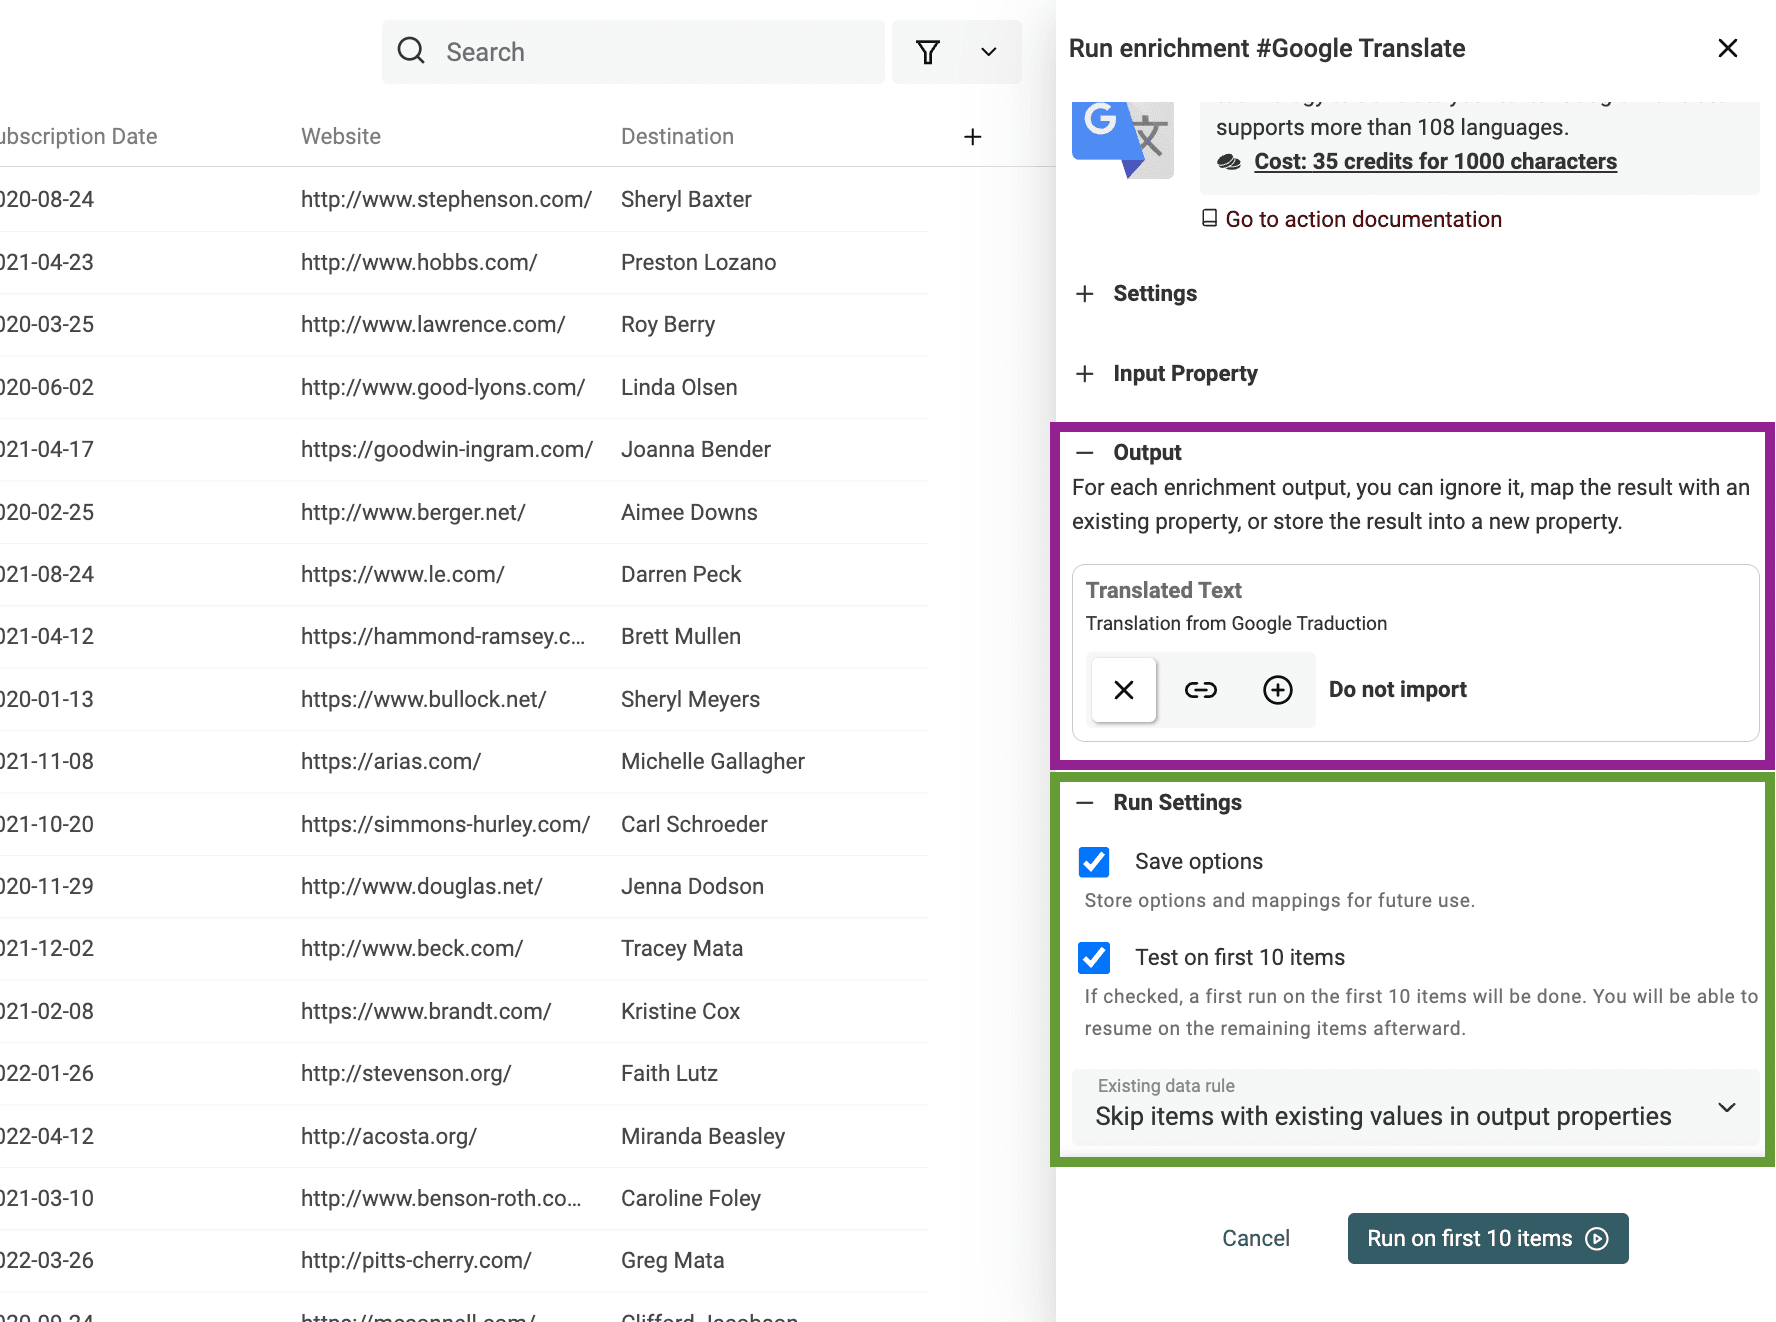
After configuring your inputs, you have to configure your output properties. Outputs are what is generated by the enrichment. In our example with Google Translate, the output is the translated text. An enrichment can have one or more output properties.
For each output property, you can:
- Ignore it - When an enrichment returns several properties, you might skip some.
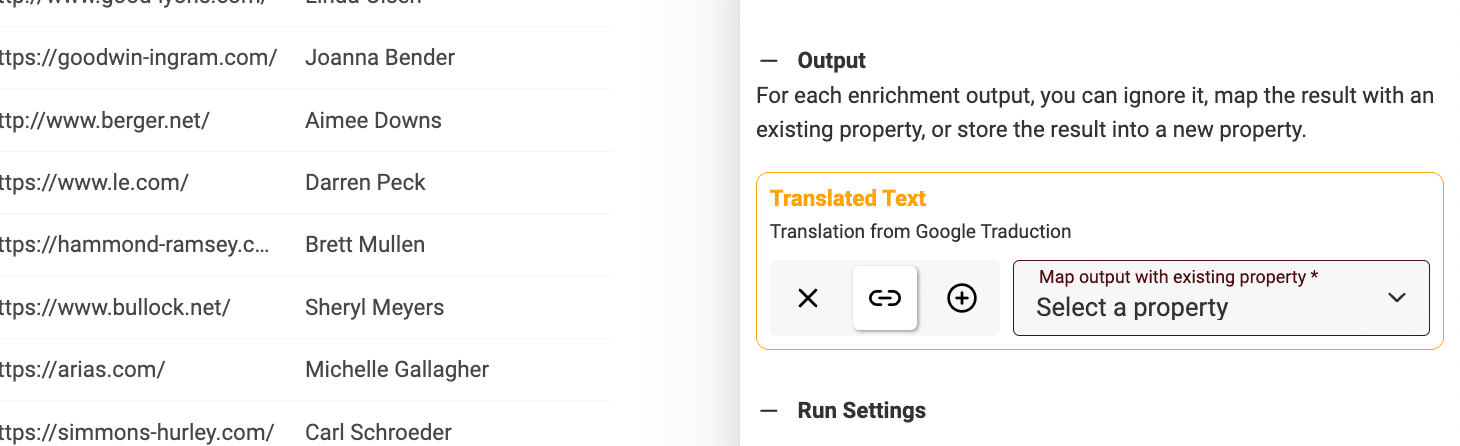
- Map the result with an existing property from your collection
- Create a new property to store the result - When selected, Datablist will add a new property at the end of your existing ones. The property will be automatically configured with the suited data type.
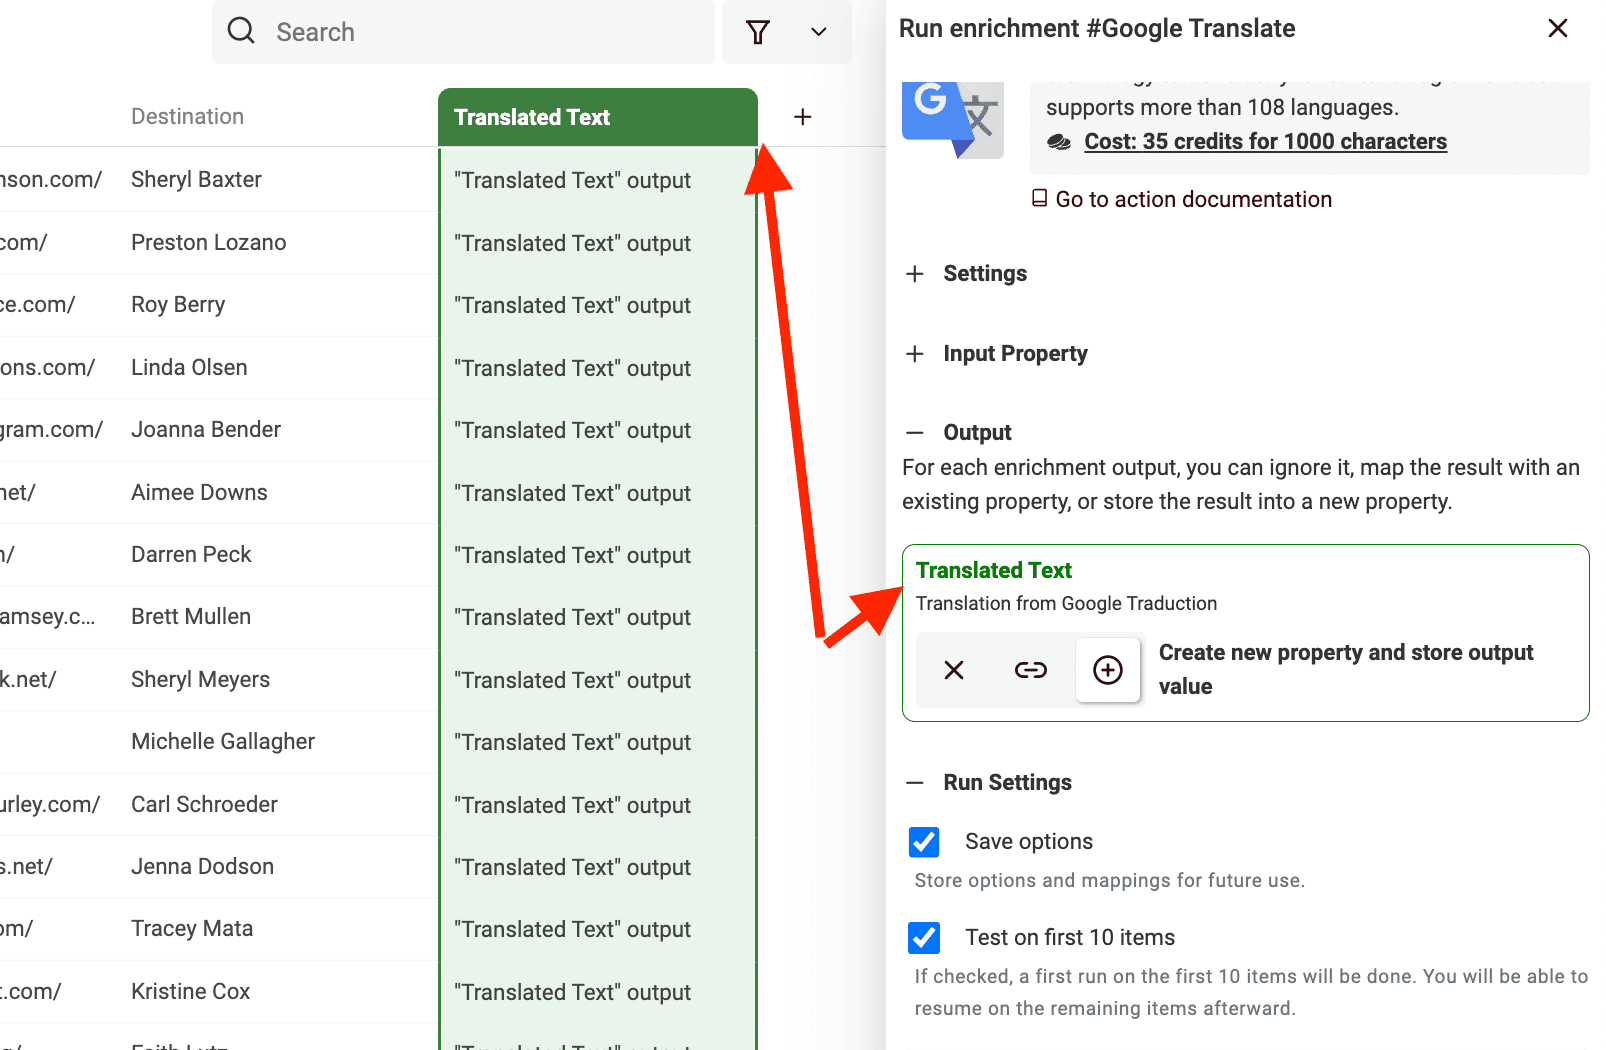
Run settings
Before running your enrichment, please check the run settings.
The run button initially selects a sample of up to 10 items when the view contains more items. Use its menu to choose the first 100, a custom count, or all view items. Review a sample before a larger credit-consuming run.
If existing output properties already contain data, Datablist asks you to choose an Existing data rule. This setting is separate from the Run on status filter, which controls whether a later run includes previously processed items or items with errors.
Detail for Existing Data Rules:
-
Skip items with existing values in output properties - Do not process an item if any mapped output already has data.
-
Update only empty cells - Keep filled output cells and write returned values only into empty outputs. An item with every mapped output filled is skipped.
-
Overwrite existing data in output properties - Replace mapped output values on processed items. This is the default behavior when an existing-data conflict is detected, so choose another rule before running if the current values must remain.
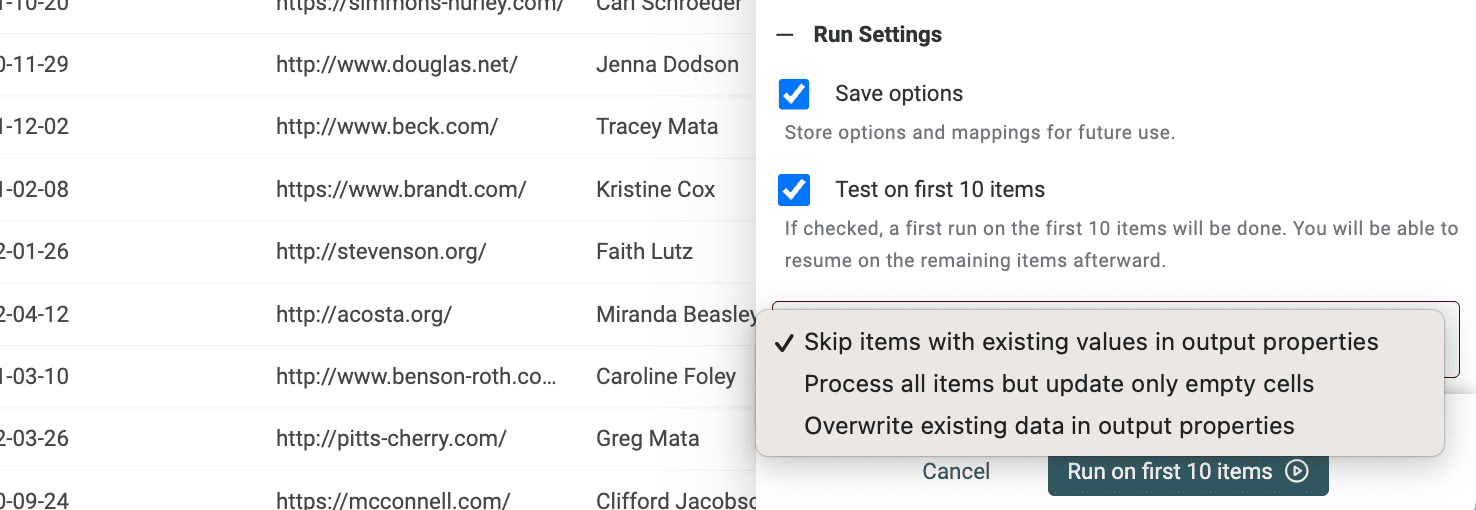
Run on the first 10 items
When the initial sample option is available, Datablist selects up to 10 items by default. It may omit that sample choice when the entire collection fits within the sample size. You can run in two steps:
- Phase 1: Run the selected sample and check output values, empty results, and credit usage
- Phase 2: Choose the remaining view items after the sample looks correct
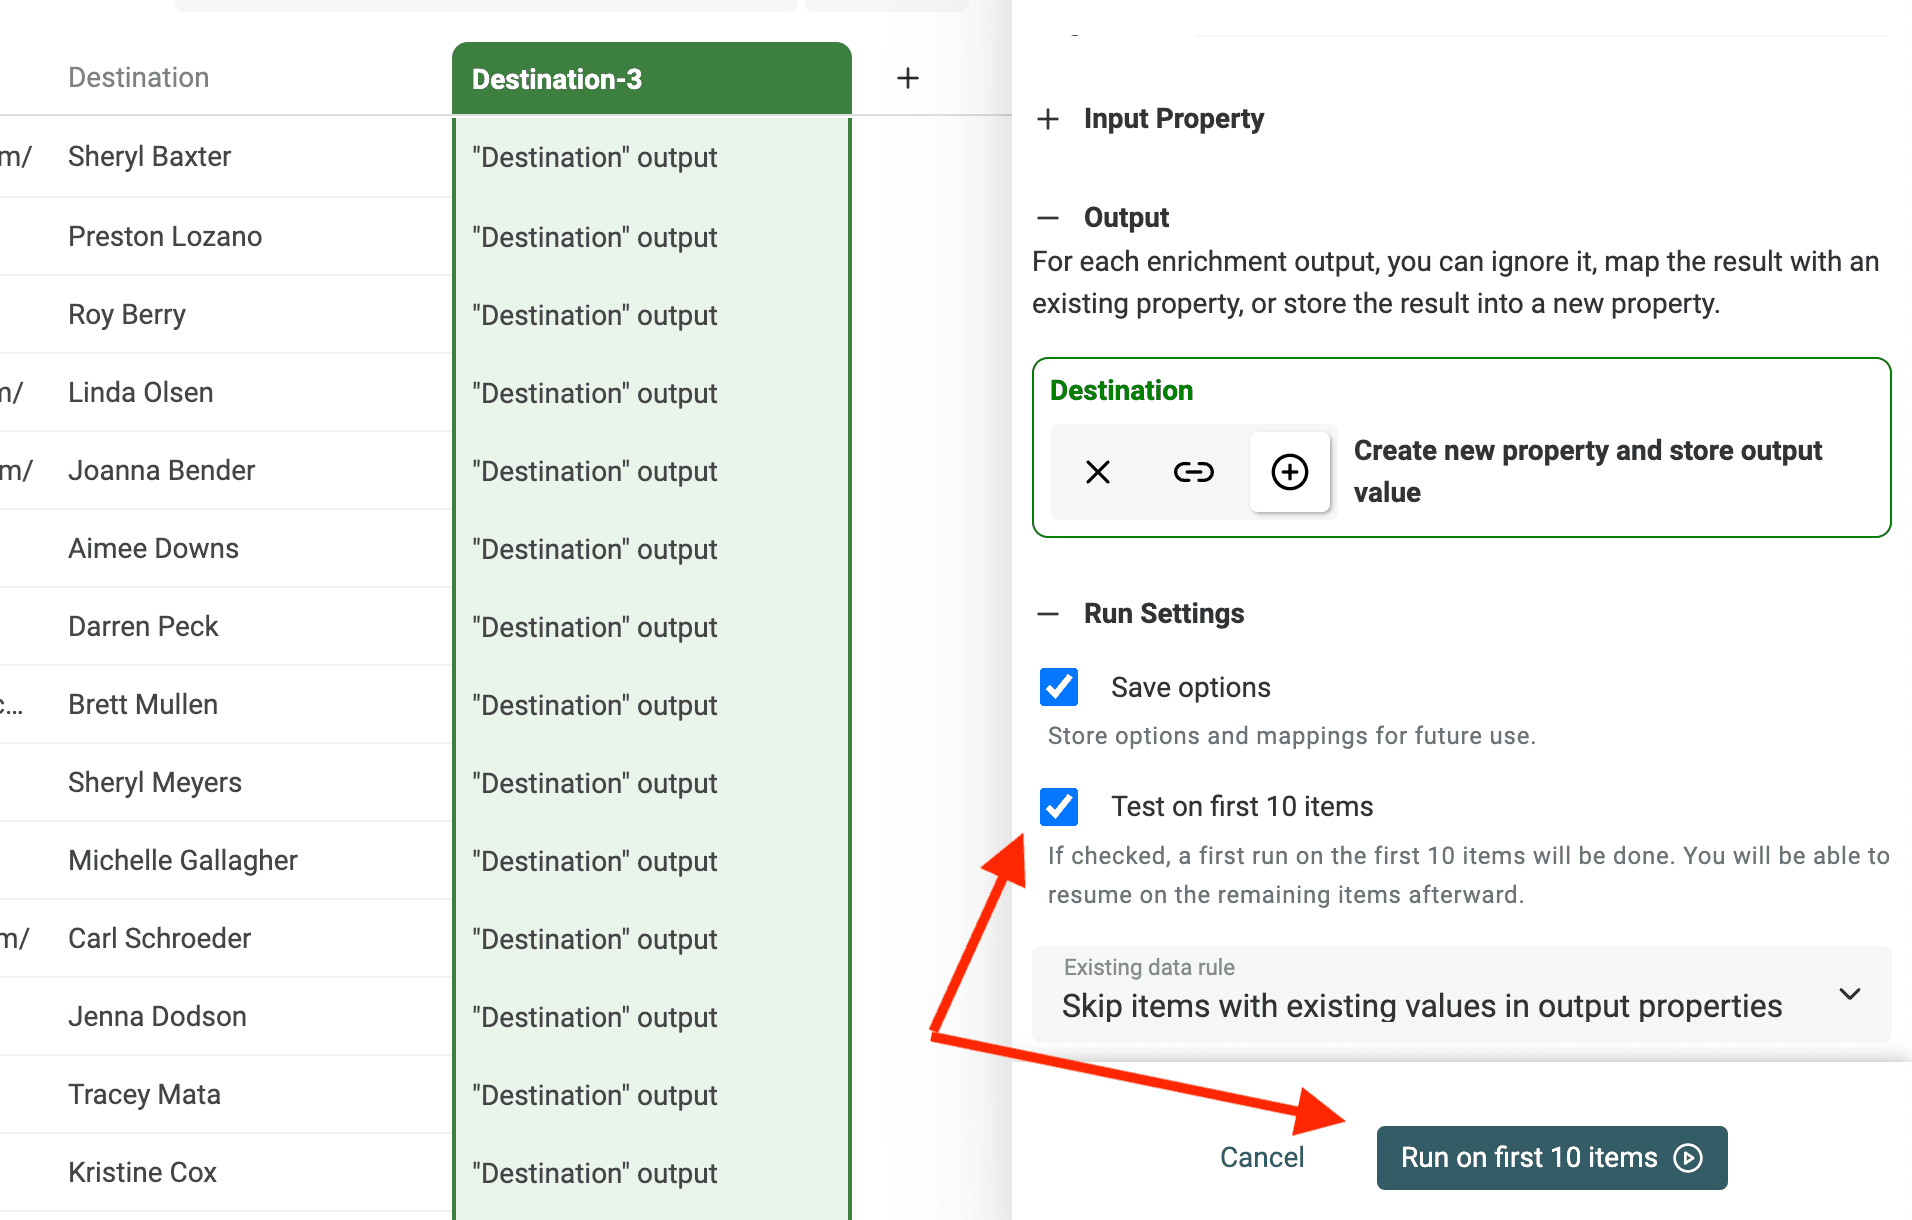
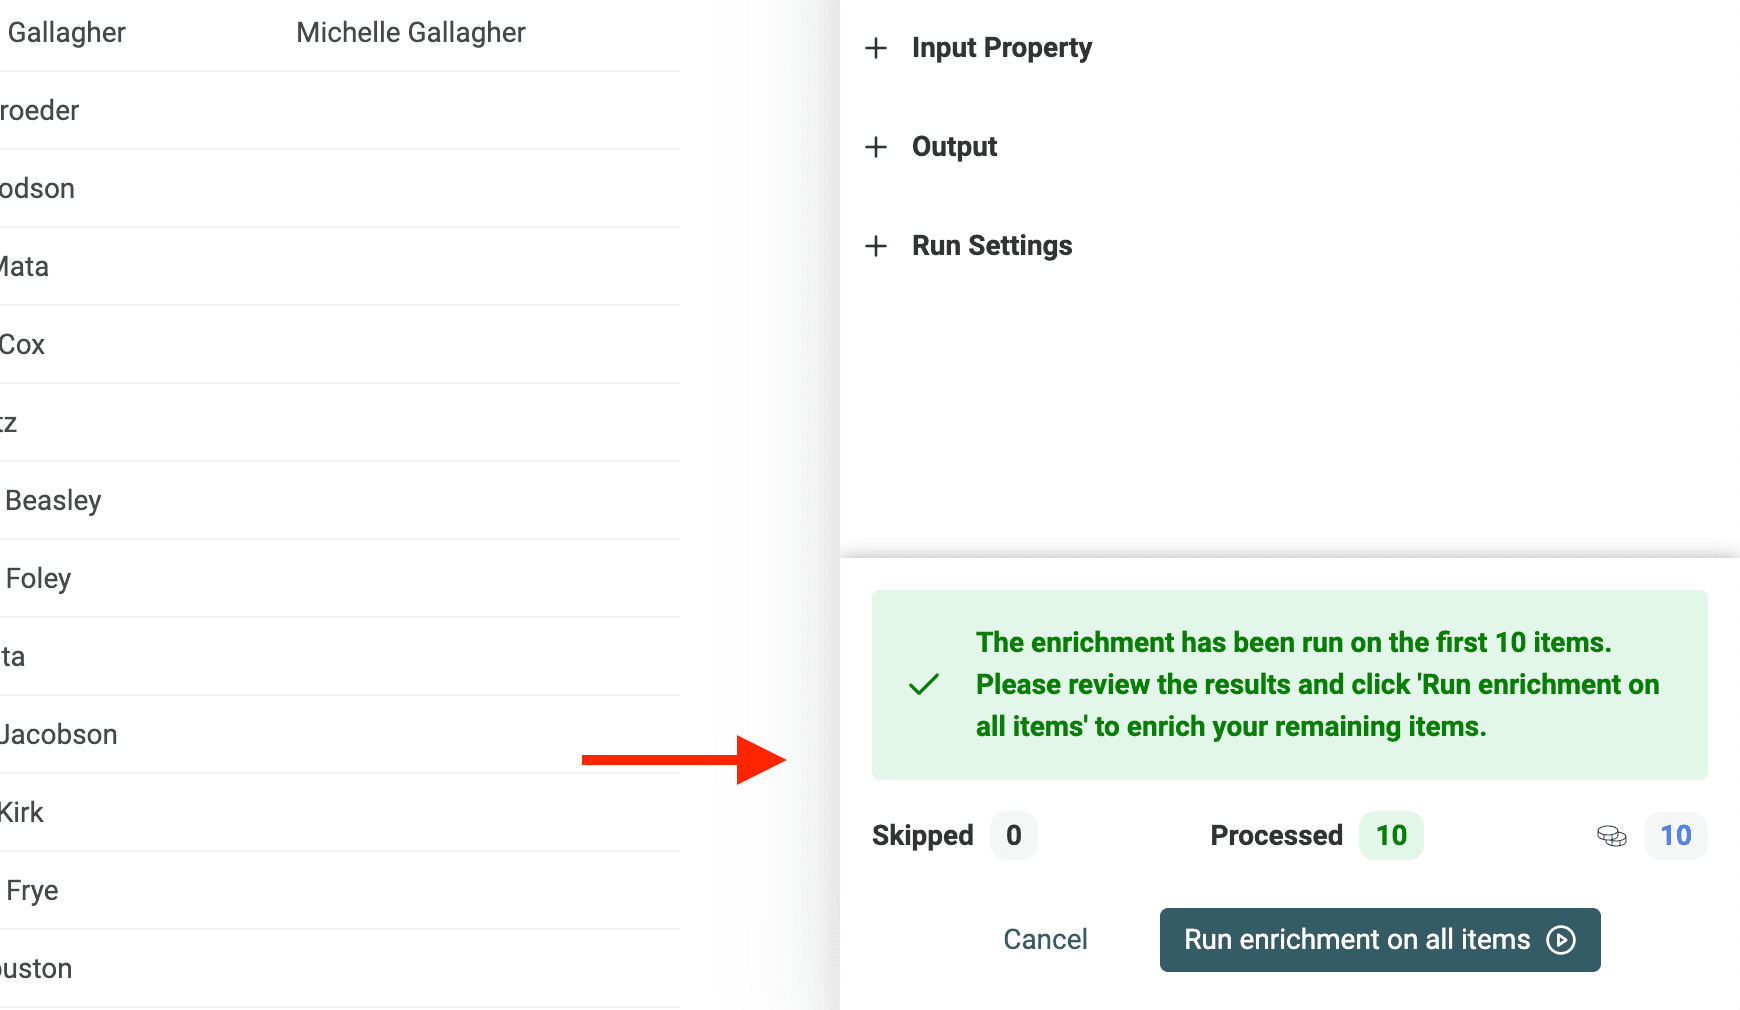
Counters with how many items have been skipped, and processed are available in real time during the processing. The amount of credits used is also visible.
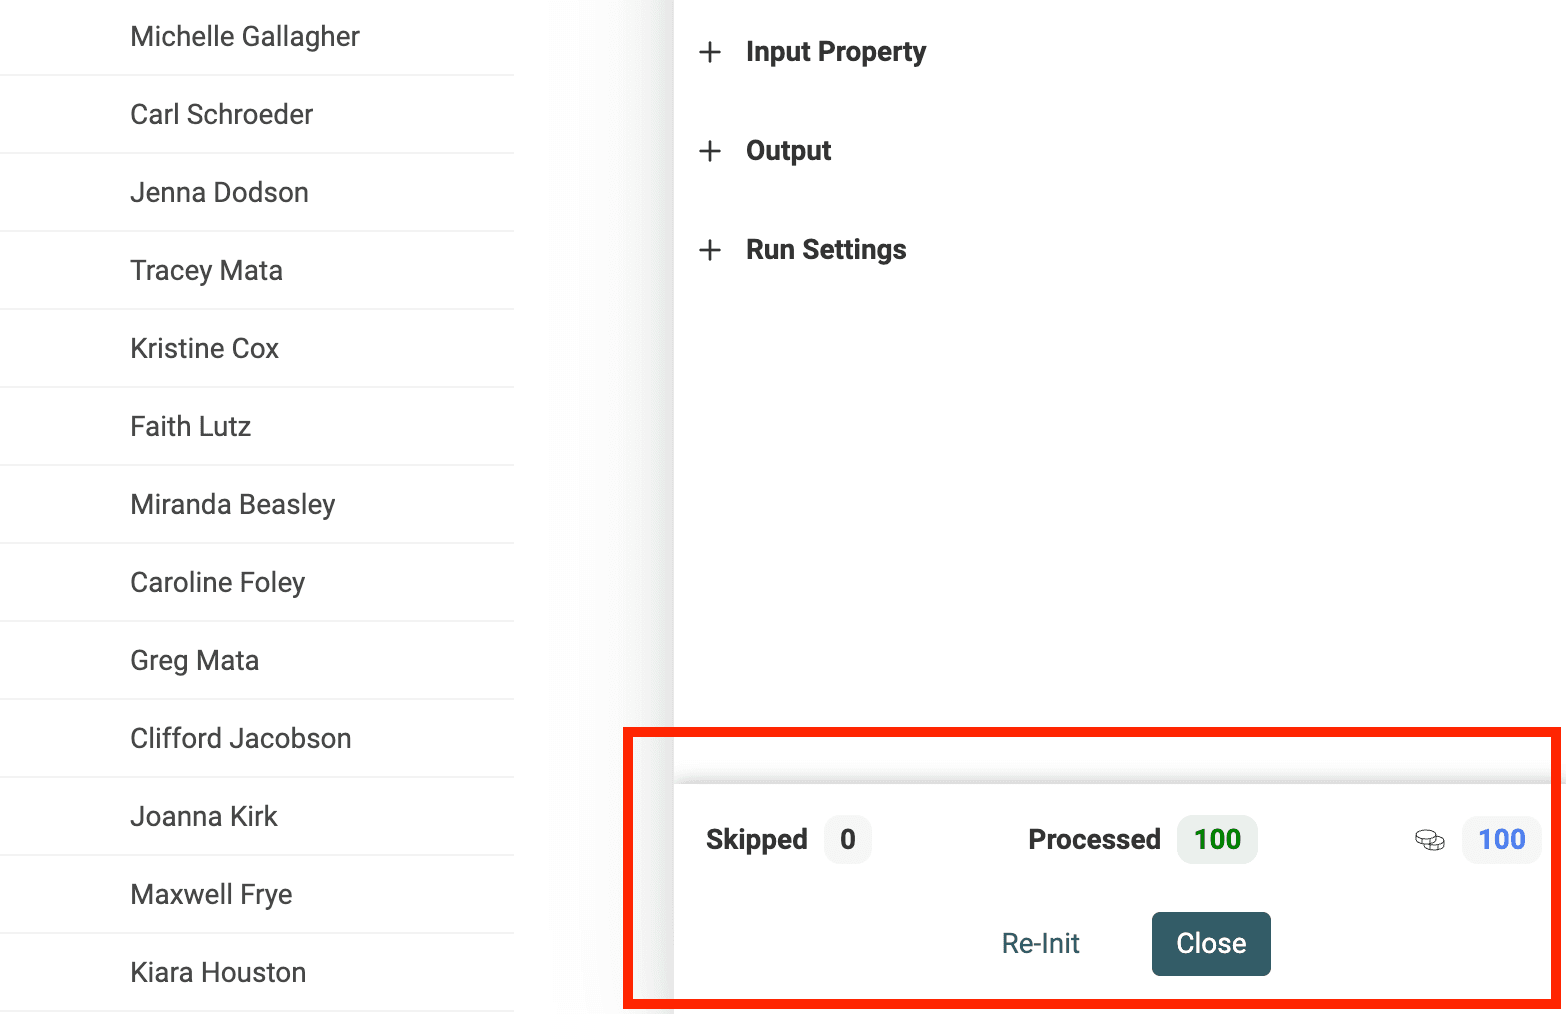
Enrichment interruption
Manual interruption
If you feel the enrichment is blocked or if you wish to change your current settings, click the "Stop" button while the enrichment is running. Datablist will wait for the current processing items to be finished and will stop the enrichment before the end.
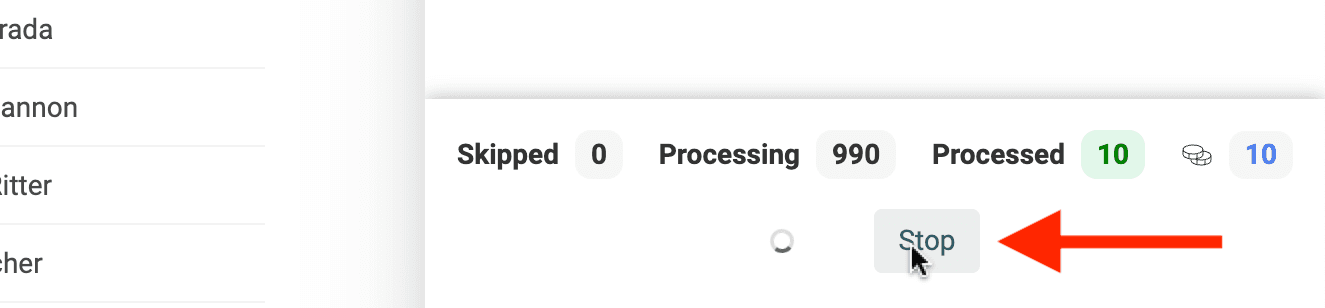
Once stopped, you can change the settings, or just resume the current processing.
Interruption following an error
An error can leave a run partially processed. Check the run status and error details, correct the input or settings, then use the available Run on choice to retry unprocessed or errored items. Inspect existing output values before choosing overwrite.
Parallel processing
Under the hood, Datablist splits items into chunks and processes them. When it is possible, Datablist will process several chunks of items in parallel.
If a run stops, some work already in progress may finish. Review the processed and skipped counts before restarting.
FAQ
Which items from my collection are processed?
Datablist will process the items in the "current view". It takes the items in this order:
- If you have selected items in your collection, it will process them
- If you have a filter or a full-text search term, it will process the filtered items
- Otherwise, it will process all your collection items
I have an idea for a new enrichment action
Great! I love to learn about new use cases and new enrichment. Please contact me using this contact form. Or just book a meeting on my Calendly.
Can I code my own enrichment action?
Growth users can configure Custom API Enrichment. For a one-off calculation, Run JavaScript can also process collection items; browser requests to external APIs require plan access and support from the target API.